# NodeLLM Full Documentation
> Auto-generated context for LLMs containing all project documentation.
# 📄 llms.txt
---
layout: null
permalink: /llms.txt
---
# NodeLLM
> The Backend-First AI SDK for Node.js
NodeLLM is an open-source infrastructure layer for building provider-agnostic, production-grade LLM systems in Node.js. It standardizes integrations across OpenAI, Anthropic, Gemini, DeepSeek, Bedrock, OpenRouter, xAI, Ollama, and Mistral into a single, predictable API.
## Project Details
- **Type**: Node.js LLM SDK / Infrastructure Layer
- **Primary Use**: Building scalable AI workers, APIs, and agents
- **Languages**: JavaScript, TypeScript
- **License**: MIT
- **Package**: `@node-llm/core`
- **Testing Package**: `@node-llm/testing`
- **Repository**: `https://github.com/node-llm/node-llm`
- **Documentation**: `https://nodellm.dev`
## Core Features
- **Provider Agnostic**: Unified API for 540+ models (OpenAI, Anthropic, Gemini, Bedrock, DeepSeek, OpenRouter, xAI, Ollama, Mistral).
- **Backend-First**: Optimized for long-running processes, CRON jobs, and persistent agents (not just frontend streaming).
- **Static Model Registry**: Zero-latency, offline access to model metadata (context window, pricing, capabilities).
- **Middleware Architecture**: Intercept and modify LLM requests/responses globally or locally (PII masking, cost tracking, telemetry).
- **ORM Integration**: First-class support for persisting chat history and tools via `@node-llm/orm`.
- **Deterministic Testing**: Native support for recording/replaying LLM interactions (VCR) and fluent mocking via `@node-llm/testing`.
## Architecture
1. **Core**: Light-weight, zero-dependency abstraction layer with middleware support.
2. **Providers**: Pluggable adapters that normalize inputs/outputs.
3. **Registry**: Static JSON database of model capabilities.
4. **MiddlewareStack**: Multi-layer orchestration for Evals, Logging, and Redaction.
## Usage Example
```ts
import { NodeLLM } from "@node-llm/core";
// 1. Unified Interface with Middleware
const chat = NodeLLM.chat("gpt-4o", {
middlewares: [piiMasker, costLogger]
});
// 2. Standardized Response
const response = await chat.ask("Explain infrastructure-as-code");
```
## Comparisons
- **vs Vercel AI SDK**: NodeLLM is optimized for backend/workers, whereas Vercel AI SDK is optimized for Frontend/Next.js streaming.
- **vs LangChain**: NodeLLM is a thin infrastructure layer with a static registry, whereas LangChain is a comprehensive framework with complex abstractions.
- **vs OpenAI SDK**: NodeLLM wraps the OpenAI SDK to provide multi-provider support with identical code.
## Quick Links
- **Get Started**: https://nodellm.dev/getting-started/overview
- **Architecture**: https://nodellm.dev/architecture
- **Testing**: https://nodellm.dev/core-features/testing
- **Contributing**: https://github.com/node-llm/node-llm/blob/main/CONTRIBUTING.md
----------------------------------------
# 📄 intro.md
---
layout: default
title: Introduction
nav_order: 1
permalink: /docs/intro
---
# Introduction
[](https://www.npmjs.com/package/@node-llm/core)
[](https://github.com/node-llm/node-llm)
[](https://github.com/node-llm/node-llm/actions/workflows/cicd.yml)
[](https://www.typescriptlang.org/)
[](https://opensource.org/licenses/MIT)
**The Provider-Agnostic LLM Runtime for Node.js.**
**NodeLLM is a backend orchestration layer designed for building reliable, testable, and provider-agnostic AI systems.**
It is not a "simple API wrapper" or a "prompt engineering tool." NodeLLM deals with the hard infrastructure problems: normalizing streaming across providers, managing tool execution loops, enforcing timeouts, and enabling first-class testing and telemetry.
Unified support for
```text
Your App
↓
NodeLLM (Unified API + State + Security)
↓
OpenAI | Anthropic | Bedrock | xAI | Ollama | Mistral
```
---
## 🛑 What NodeLLM is NOT
To understand NodeLLM, you must understand what it is **NOT**.
NodeLLM is **NOT**:
- ❌ **A thin wrapper** around vendor SDKs (like `openai` or `@anthropic-ai/sdk`)
- ❌ **A UI streaming library** (like Vercel AI SDK)
- ❌ **A prompt-only framework**
NodeLLM **IS**:
- ✅ **A Backend Runtime**: Designed for workers, cron jobs, agents, and API servers.
- ✅ **Provider Agnostic**: Switches providers via config, not code rewrites.
- ✅ **Contract Driven**: Guarantees identical behavior for Tools and Streaming across all models.
- ✅ **Infrastructure First**: Built for evals, telemetry, retries, and circuit breaking.
---
## 🏗️ The "Infrastructure-First" Approach
Most AI SDKs optimize for "getting a response to the user fast" (Frontend/Edge). NodeLLM optimizes for **system reliability** (Backend).
It is designed for architects and platform engineers who need:
- **Strict Process Protection**: Preventing hung requests from stalling event loops.
- **Normalized Persistence**: Treating chat interactions as database records via `@node-llm/orm`.
- **Determinism**: Testing your AI logic with VCR recordings and time-travel debugging.
### Strategic Goals
- **Decoupling**: Isolate your business logic from the rapid churn of AI model versions.
- **Production Safety**: Native support for circuit breaking, redaction, and audit logging.
- **Predictability**: A unified Mental Model for streaming, structured outputs, and vision.
---
## ⚡ The 5-Minute Path
```ts
import { createLLM } from "@node-llm/core";
// 1. Explicit Initialization (Preferred)
const llm = createLLM({ provider: "openai" });
const chat = llm.chat("gpt-4o");
// 2. Chat (High-level request/response)
const response = await chat.ask("Explain event-driven architecture");
console.log(response.content);
// 3. Streaming (Standard AsyncIterator)
for await (const chunk of chat.stream("Explain event-driven architecture")) {
process.stdout.write(chunk.content);
}
```
---
## 🚀 Why Use This Over Official SDKs?
| Feature | NodeLLM | Official SDKs | Architectural Impact |
| :----------------- | :---------------------------- | :-------------------------- | :------------------------ |
| **Provider Logic** | Transparently Handled | Exposed to your code | **Low Coupling** |
| **Streaming** | Standard `AsyncIterator` | Vendor-specific Events | **Predictable Data Flow** |
| **Tool Loops** | Automated Recursion | Manual implementation | **Reduced Boilerplate** |
| **Files/Vision** | Intelligent Path/URL handling | Base64/Buffer management | **Cleaner Service Layer** |
| **Configuration** | Centralized & Global | Per-instance initialization | **Easier Lifecycle Mgmt** |
---
## 🔮 Capabilities
### 💬 Unified Chat
Stop rewriting code for every provider. `NodeLLM` normalizes inputs and outputs into a single, predictable mental model.
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({ provider: "openai" });
const chat = llm.chat("gpt-4o");
await chat.ask("Hello world");
```
### 🛠️ Auto-Executing Tools
Define tools once using our clean **Class-Based DSL**; NodeLLM manages the recursive execution loop for you.
```ts
import { Tool, z } from "@node-llm/core";
class WeatherTool extends Tool {
name = "get_weather";
description = "Get current weather";
schema = z.object({ loc: z.string() });
async handler({ loc }) {
return `Sunny in ${loc}`;
}
}
await chat.withTool(WeatherTool).ask("Weather in Tokyo?");
```
### 💾 [Persistence Layer](/orm/prisma)
Automatically track chat history, tool executions, and API metrics with [**@node-llm/orm**](https://www.npmjs.com/package/@node-llm/orm). Now with full support for **Extended Thinking** persistence.
```ts
import { createChat } from "@node-llm/orm/prisma";
// Chat state is automatically saved to your database (Postgres/MySQL/SQLite)
const chat = await createChat(prisma, llm, { model: "claude-3-7-sonnet" });
await chat.withThinking({ budget: 16000 }).ask("Develop a strategy");
```
### 🧪 [Deterministic Testing](/core-features/testing)
Validate your AI agents with **VCR cassettes** (record/replay) and a **Fluent Mocker** for unit tests. No more flaky or expensive test runs. Powered by [**@node-llm/testing**](https://www.npmjs.com/package/@node-llm/testing).
```ts
import { vcr, Mocker } from "@node-llm/testing";
// 1. Integration Tests (VCR)
await vcr.useCassette("pricing_flow", async () => {
const res = await chat.ask("How much?");
expect(res.content).toContain("$20/mo");
});
// 2. Unit Tests (Mocker)
const mock = new Mocker()
.chat("Next step?")
.respond("Login User")
.callsTool("getCurrentUser", { id: 1 });
```
### 🛡️ [Security & Compliance](/advanced/security)
Implement custom security, PII detection, and compliance logic using pluggable asynchronous hooks (`beforeRequest` and `afterResponse`).
### 🔧 Strategic Configuration
NodeLLM provides a flexible configuration system designed for enterprise usage:
```ts
// Switch providers at the framework level
const llm = createLLM({ provider: "anthropic" });
```
### ⚡ Scoped Parallelism
Run multiple providers in parallel safely without global configuration side effects using isolated contexts.
```ts
const [gpt, claude] = await Promise.all([
NodeLLM.withProvider("openai").chat("gpt-4o").ask(prompt),
NodeLLM.withProvider("anthropic").chat("claude-3-5-sonnet").ask(prompt)
]);
```
### 🧠 [Extended Thinking](/core-features/reasoning)
Direct access to the thought process of modern reasoning models like **Claude 3.7**, **DeepSeek R1**, or **OpenAI o1/o3** using a unified interface.
```ts
const res = await chat
.withThinking({ budget: 16000 })
.ask("Solve this logical puzzle");
console.log(res.thinking.text); // Full chain-of-thought
```
---
## 📋 Supported Providers
| Provider | Supported Features |
| :----------------------------------------------------------------------------------------------------------------------------------- | :---------------------------------------------------------------------------------------------------- |
|  **OpenAI** | Chat, Streaming, Tools, Vision, Audio, Images, Transcription, **Reasoning**, **Smart Developer Role** |
|
 **Gemini** | Chat, Streaming, Tools, Vision, Audio, Video, Embeddings |
|
 **Anthropic** | Chat, Streaming, Tools, Vision, PDF, Structured Output, **Extended Thinking (Claude 3.7)** |
|
 **DeepSeek** | Chat (V3), **Extended Thinking (R1)**, Tools, Streaming |
|
 **Bedrock** | Chat, Streaming, Tools, Image Gen (Titan/SD), Embeddings, **Prompt Caching** |
|
 **OpenRouter** | **Aggregator**, Chat, Streaming, Tools, Vision, Embeddings, **Reasoning** |
|

 **xAI** | Chat, Streaming, Tools, Vision, Images, **Reasoning** |
|
 **Ollama** | **Local Inference**, Chat, Streaming, Tools, Vision, Embeddings |
|
 **Mistral** | Chat, Streaming, Tools, Vision, Embeddings, Transcription, Moderation, **Reasoning (Magistral)** |
---
## 🤝 Contributing
We welcome contributions! Please see our [Contributing Guide](https://github.com/node-llm/node-llm/blob/main/CONTRIBUTING.md) for more details on how to get started.
---
## 🫶 Credits
Heavily inspired by the elegant design of [RubyLLM](https://rubyllm.com/).
---
**Upgrading to v1.6.0?** Read the [Migration Guide](/getting_started/migration-v1-6.html) to understand the new strict provider requirements and typed error hierarchy.
----------------------------------------
# 📄 getting_started/configuration.md
---
layout: default
title: Configuration
nav_order: 3
parent: Getting Started
permalink: /getting-started/configuration
description: Learn how to configure NodeLLM with API keys, custom base URLs, security limits, and per-request overrides.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
`NodeLLM` provides three ways to configure providers: **Zero-Config** (via environment variables), **Explicit Factory** (via `createLLM`), and **Isolated Branching** (via `.withProvider`).
---
## 1. Zero-Config (The "Direct" Pattern)
The simplest way to use NodeLLM is by relying on environment variables. NodeLLM will automatically snapshot your environment at load time.
**Environment variables (`.env`):**
```env
NODELLM_PROVIDER=openai
OPENAI_API_KEY=sk-....
```
**Code:**
```typescript
import "dotenv/config";
import { NodeLLM } from "@node-llm/core";
// Zero setup required
const chat = NodeLLM.chat();
```
---
## 2. Explicit Factory (`createLLM`)
Recommended for production applications where you want to explicitly define provider behavior or manage multiple providers in one application.
### Switching Providers
Since `NodeLLM` is immutable, you switch providers by creating a new instance using `createLLM()` or `withProvider()`.
```typescript
// Create an Anthropic instance
const llm = createLLM({
provider: "anthropic",
anthropicApiKey: process.env.ANTHROPIC_API_KEY
});
```
### Provider Configuration
#### API Keys
Configure API keys in the configuration object.
```typescript
const llm = createLLM({
openaiApiKey: process.env.OPENAI_API_KEY,
anthropicApiKey: process.env.ANTHROPIC_API_KEY,
geminiApiKey: process.env.GEMINI_API_KEY,
deepseekApiKey: process.env.DEEPSEEK_API_KEY,
openrouterApiKey: process.env.OPENROUTER_API_KEY,
xaiApiKey: process.env.XAI_API_KEY,
mistralApiKey: process.env.MISTRAL_API_KEY
});
```
#### Custom Base URLs
Override the default API endpoints for custom deployments (e.g., Azure OpenAI):
```typescript
const llm = createLLM({
provider: "openai",
openaiApiKey: process.env.AZURE_OPENAI_API_KEY,
openaiApiBase: process.env.AZURE_OPENAI_API_BASE_ENDPOINT
});
```
#### Loop Protection & Security Limits
Prevent runaway costs, infinite loops, and hanging requests by setting execution and timeout limits:
```typescript
const llm = createLLM({
maxToolCalls: 5, // Stop after 5 sequential tool execution turns
maxRetries: 2, // Retry network/server errors 2 times
requestTimeout: 30000, // Timeout requests after 30 seconds (default)
maxTokens: 4096 // Limit output to 4K tokens (default)
});
```
**Security Benefits:**
- **`maxToolCalls`**: Prevents infinite tool execution loops
- **`maxRetries`**: Prevents retry storms that could exhaust resources
- **`requestTimeout`**: Prevents hanging requests and DoS attacks
- **`maxTokens`**: Prevents excessive output generation and cost overruns
---
## Supported Configuration Keys
| Key | Description | Default |
| --------------------------- | ----------------------------------- | --------------------------------- |
| `openaiApiKey` | OpenAI API key | `process.env.OPENAI_API_KEY` |
| `openaiApiBase` | OpenAI API base URL | `process.env.OPENAI_API_BASE` |
| `anthropicApiKey` | Anthropic API key | `process.env.ANTHROPIC_API_KEY` |
| `anthropicApiBase` | Anthropic API base URL | `process.env.ANTHROPIC_API_BASE` |
| `geminiApiKey` | Google Gemini API key | `process.env.GEMINI_API_KEY` |
| `geminiApiBase` | Gemini API base URL | `process.env.GEMINI_API_BASE` |
| `deepseekApiKey` | DeepSeek API key | `process.env.DEEPSEEK_API_KEY` |
| `deepseekApiBase` | DeepSeek API base URL | `process.env.DEEPSEEK_API_BASE` |
| `openrouterApiKey` | OpenRouter API key | `process.env.OPENROUTER_API_KEY` |
| `openrouterApiBase` | OpenRouter API base URL | `process.env.OPENROUTER_API_BASE` |
| `xaiApiKey` | xAI API key | `process.env.XAI_API_KEY` |
| `xaiApiBase` | xAI API base URL | `process.env.XAI_API_BASE` |
| `mistralApiKey` | Mistral API key | `process.env.MISTRAL_API_KEY` |
| `mistralApiBase` | Mistral API base URL | `process.env.MISTRAL_API_BASE` |
| `ollamaApiBase` | Ollama API base URL | `process.env.OLLAMA_API_BASE` |
| `defaultChatModel` | Default model for `.chat()` | Provider default |
| `defaultTranscriptionModel` | Default model for `.transcribe()` | Provider default |
| `defaultModerationModel` | Default model for `.moderate()` | Provider default |
| `defaultEmbeddingModel` | Default model for `.embed()` | Provider default |
| `maxToolCalls` | Max sequential tool execution turns | `5` |
| `maxRetries` | Max retries for provider errors | `2` |
| `requestTimeout` | Request timeout in milliseconds | `30000` (30s) |
| `maxTokens` | Max output tokens per request | `4096` |
| `retry` | Retry configuration (legacy) | `{ attempts: 1, delayMs: 0 }` |
---
## Inspecting Configuration
You can inspect the current internal configuration at any time.
```typescript
console.log(NodeLLM.config.openaiApiKey);
```
---
## Error Handling
Attempting to use an unconfigured provider will raise a clear error:
```typescript
// If API key is not set
const llm = createLLM({ provider: "openai" });
// Error: openaiApiKey is not set in config...
```
### Snapshotting & Instance Initialization
When you create an LLM instance (including the default `NodeLLM` export), it **snapshots** all relevant environment variables.
In the global `NodeLLM` instance, this initialization is **lazy**. It only snapshots `process.env` the first time you access a property or method (like `.chat()`). This makes it safe to use with `dotenv/config` or similar libraries in ESM, even if they are imported after the core library.
```typescript
// ✅ Safe in NodeLLM v1.6.0+: Initialized on first call
import { NodeLLM } from "@node-llm/core";
import "dotenv/config";
const chat = NodeLLM.chat(); // Snapshots environment NOW
```
---
## Best Practices
### Use Dotenv for Local Development
```typescript
import "dotenv/config";
import { createLLM } from "@node-llm/core";
const llm = createLLM({ provider: "openai" });
```
### Configure Once at Startup
```typescript
// app.ts
const llm = createLLM({
openaiApiKey: process.env.OPENAI_API_KEY,
anthropicApiKey: process.env.ANTHROPIC_API_KEY
});
```
### Scoped Configuration (Isolation)
`NodeLLM` is a **frozen, immutable instance**. It cannot be mutated at runtime. This design ensures that configurations do not leak between parallel requests, making it safe for multi-tenant applications.
Use `createLLM()` or `.withProvider()` to create an **isolated context**.
#### Isolated Provider State
Run multiple providers in parallel safely without any side effects:
```ts
const [gpt, claude] = await Promise.all([
NodeLLM.withProvider("openai").chat("gpt-4o").ask(prompt),
NodeLLM.withProvider("anthropic").chat("claude-3-5-sonnet").ask(prompt)
]);
```
#### Scoped Credentials
You can also pass a second argument to `withProvider` to override configuration keys (like API keys) for that specific instance only. This is useful for multi-tenant applications.
```ts
const userA = NodeLLM.withProvider("openai", {
openaiApiKey: "USER_A_KEY"
});
const userB = NodeLLM.withProvider("openai", {
openaiApiKey: "USER_B_KEY"
});
// These calls use different API keys simultaneously
const [resA, resB] = await Promise.all([
userA.chat().ask("Hello from A"),
userB.chat().ask("Hello from B")
]);
```
This ensures each parallel call uses the correct provider and credentials without interfering with others.
----------------------------------------
# 📄 getting_started/getting-started.md
---
layout: default
title: Quick Start
nav_order: 2
parent: Getting Started
permalink: /getting-started/quick-start
description: A 5-minute guide to get started with NodeLLM. Install, configure, and run your first chat, image generation, and embedding scripts.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Start building AI apps in Node.js in 5 minutes. Chat, generate images, and create embeddings with one unified API.
---
## Installation
```bash
npm install @node-llm/core
# or
pnpm add @node-llm/core
```
---
## Configuration
The fastest way to start is using **Zero-Config**. NodeLLM automatically reads your API keys and the active provider from environment variables.
```ts
import "dotenv/config";
import { createLLM } from "@node-llm/core";
// Explicit initialization is recommended for production apps
const llm = createLLM({ provider: "openai" });
```
Alternatively, use the **Zero-Config** singleton for rapid prototyping. NodeLLM automatically reads your API keys and the active provider from environment variables:
```ts
import { NodeLLM } from "@node-llm/core";
const llm = NodeLLM; // Exported singleton
```
---
## Quick Start Examples
### Chat
```ts
const chat = llm.chat(); // Uses default model
const response = await chat.ask("Explain quantum computing in 5 words.");
console.log(response.content);
// => "Computing using quantum mechanical phenomena."
```
### Generate Images
```ts
const image = await llm.paint("A cyberpunk city with neon rain");
console.log(image.url);
```
### Create Embeddings
```ts
const embedding = await llm.embed("Semantic search is powerful.");
console.log(`Vector dimensions: ${embedding.dimensions}`);
```
### Streaming
Real-time responses are essential for good UX.
```ts
for await (const chunk of chat.stream("Write a poem")) {
process.stdout.write(chunk.content);
}
```
---
## Next Steps
- [Chat Features](/core-features/chat.html): Learn about history, system prompts, and JSON mode.
- [Multimodal](/core-features/multimodal.html): Send images, audio, and documents.
- [Tool Calling](/core-features/tools.html): Give your AI ability to execute code.
- [Deterministic Testing](/core-features/testing): Setup reliable, zero-cost integration tests.
- [Migration Guide (v1.6)](/getting_started/migration-v1-6): Moving from legacy mutable versions.
----------------------------------------
# 📄 getting_started/index.md
---
layout: default
title: Getting Started
nav_order: 2
has_children: true
permalink: /getting-started
description: New to NodeLLM? Start here to understand the core philosophy and get your first model running in minutes.
back_to_top: false
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
----------------------------------------
# 📄 getting_started/migration-v1-6.md
---
layout: default
title: Migration Guide (v1.6)
parent: Getting Started
nav_order: 10
permalink: /getting-started/migration-guide-v1-6
description: Guide for migrating to NodeLLM v1.6.0 strict provider configuration.
---
# Migrating to NodeLLM v1.6.0
{: .no_toc }
NodeLLM v1.6.0 builds upon the **Immutable Architecture** introduced in v1.5.0 and introduces stricter configuration requirements to eliminate ambiguity when working with multiple providers.
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
## Strict Provider Requirement
The most significant change in v1.6.0 is the removal of "Automatic Provider Detection."
### Legacy Behavior (v1.5 and below)
NodeLLM would previously attempt to guess which provider you wanted based on the presence of API keys (e.g., defaulting to OpenAI if `OPENAI_API_KEY` was found).
### New Behavior (v1.6.0)
If you use the direct `NodeLLM` singleton, you **must now explicitly set** the `NODELLM_PROVIDER` environment variable.
```bash
# .env - REQUIRED for Zero-Config
NODELLM_PROVIDER=openai
OPENAI_API_KEY=sk-...
```
If this variable is missing, `NodeLLM.chat()` will now throw a `ProviderNotConfiguredError` rather than guessing.
---
## Immutable Global Configuration (Reminder)
While introduced in v1.5.0, v1.6.0 reinforces that the global `NodeLLM` instance is **Frozen**.
### ❌ No-Op: `NodeLLM.configure()`
Programmatic mutation of the global singleton is no longer supported.
```javascript
// This pattern has been deprecated since v1.5 and remains a no-op in v1.6
import { NodeLLM } from "@node-llm/core";
NodeLLM.configure({ ... }); // ⚠️ WARNING: No effect.
```
### ✅ Use Scoped Instances
For programmatic configuration, always use `createLLM()` or `.withProvider()`.
```javascript
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "anthropic",
anthropicApiKey: "sk-..."
});
```
---
## Typed Error Hierarchy
In v1.6.0, we have moved from generic `Error` strings to a robust, typed error hierarchy. This allows for better programmatic handling of LLM failures.
| Feature | Legacy Error | New v1.6 Error |
| :--------------- | :-------------------------------------- | :--------------------------- |
| Missing Feature | `Error: ... does not support ...` | `UnsupportedFeatureError` |
| Missing Provider | `Error: LLM provider not configured` | `ProviderNotConfiguredError` |
| Model Mismatch | `Error: Model ... does not support ...` | `ModelCapabilityError` |
---
## Design Rationale
These changes complete the architectural transition started in v1.5.0:
1. **No Ambiguity**: By requiring `NODELLM_PROVIDER`, we ensure that a single model (like `llama3`) is never accidentally routed to the wrong provider (Ollama vs OpenRouter).
2. **Stable Contracts**: The Immutable Singleton ensures that your application configuration is predictable and thread-safe from the moment of first access.
3. **Production Observability**: Typed errors make it easier to build automated monitors and fallback logic around specific provider failure modes.
----------------------------------------
# 📄 getting_started/overview.md
---
layout: default
title: Overview
nav_order: 1
parent: Getting Started
permalink: /getting-started/overview
description: High-level overview of NodeLLM components, design principles, and how the framework works.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
`NodeLLM` provides a seamless, unified interface for interacting with multiple Large Language Model (LLM) providers. Whether you are building a simple chat bot or a complex multi-modal agentic workflow, `NodeLLM` abstracts away the provider-specific complexities.
---
## Core Components
Understanding these components will help you use the framework effectively.
### Chat
The primary interface for conversational AI. `NodeLLM.chat()` creates a stateful object that manages conversation history.
```ts
const chat = llm.chat("gpt-4o");
```
### Providers
Adapters that translate the unified `NodeLLM` format into provider-specific API calls (OpenAI, Anthropic, Gemini). You rarely interact with them directly; the library handles this based on the model ID you choose.
### Tools
Functions that the AI can execute. You define the schema and the handler, and `NodeLLM` manages the execution loop automatically.
### Configuration
Global settings for API keys and defaults.
```ts
const llm = createLLM({
openaiApiKey: "sk-...",
provider: "openai"
});
```
---
## Design Principles
### Unified Interface
Every provider works differently. `NodeLLM` normalizes inputs (messages, images) and outputs (content, usage stats) so your code doesn't change when you switch models.
### Streaming First
AI responses are slow. `NodeLLM` is built around `AsyncIterator` to make streaming text to the user as easy as a `for await` loop.
### Progressive Disclosure
Start simple with `NodeLLM.chat().ask("Hello")`. As your needs grow, you can access advanced features like raw API responses, custom headers, and token usage tracking without breaking your initial code.
---
## Configuration Patterns
NodeLLM supports two primary styles of configuration to match your preferred architectural pattern.
### 1. Fluent Builder API
Ideal for step-by-step configuration and readable "action" chains.
```ts
const chat = NodeLLM.chat("claude-3-7-sonnet")
.withInstructions("You are a logic expert")
.withTemperature(0.2)
.withThinking({ budget: 16000 });
await chat.ask("Solve this puzzle");
```
### 2. Direct Configuration Object (Stateless)
Ideal for integrations that pass configuration dynamically or from a centralized settings object.
**Enhanced in v1.7.0**
{: .label .label-green }
```ts
// All options can be passed together at initialization
const chat = NodeLLM.chat("gpt-4o", {
instructions: "You are a helpful assistant",
temperature: 0.7,
maxTokens: 500,
thinking: { effort: "high" },
headers: { "X-Tenant-ID": "123" }
});
// Or per-request for granular override
await chat.ask("Hello", {
temperature: 0.1,
maxToolCalls: 5
});
```
---
## How It Works
1. **Normalization**: Your inputs (text, images, files) are converted into a standardized format.
2. **Configuration**: The library uses the provider and model you specify (e.g., GPT-4o with OpenAI).
3. **Execution**: The request is sent. If tools are called, the library executes them and feeds the result back to the model.
4. **Response**: The final response is normalized into a consistent object.
----------------------------------------
# 📄 core-features/agents.md
---
layout: default
title: Agents
nav_order: 6
parent: Core Features
permalink: /core-features/agents
description: Build intelligent agents with a declarative class-based DSL for model routing, RAG, multi-agent collaboration, and more.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The `Agent` class provides a declarative way to define reusable agents with static configuration. This is inspired by Ruby on Rails' class macros and provides a clean DSL for agent definition.
```bash
npm install @node-llm/core
```
---
## Basic Usage v1.11.0+
Define agents using static properties on a class:
```typescript
import { Agent, createLLM } from "@node-llm/core";
// Define an agent with static properties
class AssistantAgent extends Agent {
static model = "gpt-4o";
static instructions = "You are a helpful assistant. Be concise.";
static temperature = 0.7;
}
// Create and use
const llm = createLLM({ provider: "openai" });
const agent = new AssistantAgent({ llm });
const response = await agent.ask("What is the capital of France?");
```
### Agent Methods
**Instance Methods:**
| Method | Description |
|:-------|:------------|
| `ask(prompt)` | Send a message and get a response |
| `say(prompt)` | Alias for `ask()` |
| `stream(prompt)` | Stream the response |
**Static Methods** v1.11.0+
| Method | Description |
|:-------|:------------|
| `Agent.ask(prompt)` | One-liner execution (creates instance automatically) |
| `Agent.stream(prompt)` | One-liner streaming |
```typescript
// Static API (one-liner)
const result = await AssistantAgent.ask("What is TypeScript?");
// Instance API (traditional)
const agent = new AssistantAgent({ llm });
const result = await agent.ask("What is TypeScript?");
```
### Available Static Properties
| Property | Type | Description |
|:---------|:-----|:------------|
| `model` | `string` | The model ID to use (e.g., "gpt-4o") |
| `instructions` | `string` | System prompt for the agent |
| `tools` | `Tool[]` | Array of Tool classes to register |
| `temperature` | `number` | Sampling temperature (0-2) |
| `thinking` | `boolean \| object` | Enable extended thinking (Claude) |
| `schema` | `ZodSchema` | Output schema for structured responses |
---
## Agents with Tools
Register tools on an agent class:
```typescript
import { Agent, Tool, z, createLLM } from "@node-llm/core";
class CalculatorTool extends Tool {
name = "calculator";
description = "Performs arithmetic operations";
schema = z.object({
a: z.number(),
b: z.number(),
operation: z.enum(["add", "subtract", "multiply", "divide"])
});
async execute({ a, b, operation }) {
const ops = { add: a + b, subtract: a - b, multiply: a * b, divide: a / b };
return { result: ops[operation] };
}
}
class MathAgent extends Agent {
static model = "gpt-4o";
static instructions = "Use the calculator tool to solve math problems.";
static tools = [CalculatorTool];
static temperature = 0;
}
const llm = createLLM({ provider: "openai" });
const agent = new MathAgent({ llm });
await agent.ask("What is 15 multiplied by 7?"); // Uses the tool automatically
```
---
## Model Routing Agent
Route requests to the best model for the job:
```typescript
import { Agent, Tool, z, createLLM } from "@node-llm/core";
class ClassifierTool extends Tool {
name = "classify_task";
description = "Classifies the task type";
schema = z.object({ query: z.string() });
async execute({ query }) {
const response = await createLLM({ provider: "openai" })
.chat("gpt-4o-mini")
.system("Classify as: code, creative, or factual. One word only.")
.ask(query);
return { taskType: response.content.toLowerCase().trim() };
}
}
class SmartRouter extends Agent {
static model = "gpt-4o";
static instructions = "Classify the task, then route to the appropriate specialist.";
static tools = [ClassifierTool];
}
const llm = createLLM({ provider: "openai" });
const router = new SmartRouter({ llm });
await router.ask("Write a poem about the ocean");
```
---
## RAG Agent (Retrieval-Augmented Generation)
Combine vector search with LLM generation:
```typescript
import { Agent, Tool, z, createLLM } from "@node-llm/core";
import { PrismaClient } from "@prisma/client";
const prisma = new PrismaClient();
class KnowledgeSearchTool extends Tool {
name = "search_knowledge";
description = "Searches internal documents for relevant context";
schema = z.object({ query: z.string().describe("What to search for") });
async execute({ query }) {
const embedding = await createLLM({ provider: "openai" }).embed(query);
const docs = await prisma.$queryRaw`
SELECT title, content FROM documents
ORDER BY embedding <-> ${embedding.vector}::vector LIMIT 3
`;
return docs.map(d => `[${d.title}]: ${d.content}`).join("\n\n");
}
}
class RAGAgent extends Agent {
static model = "gpt-4o";
static instructions = "Answer questions using the knowledge search tool. Cite sources.";
static tools = [KnowledgeSearchTool];
}
const llm = createLLM({ provider: "openai" });
const agent = new RAGAgent({ llm });
await agent.ask("What's our vacation policy?");
```
See the [HR Chatbot Example](https://github.com/node-llm/node-llm/tree/main/examples/applications/hr-chatbot-rag) for a complete RAG implementation.
---
## Multi-Agent Collaboration
Compose specialized agents for complex workflows:
```typescript
import { Agent, createLLM } from "@node-llm/core";
class ResearchAgent extends Agent {
static model = "gemini-2.0-flash";
static instructions = "List 5 key facts about the topic. Be concise.";
}
class WriterAgent extends Agent {
static model = "claude-sonnet-4-20250514";
static instructions = "Write a compelling article from the provided research notes.";
}
// Orchestrator: directly coordinates sub-agents
async function researchAndWrite(topic: string) {
// Step 1: Research
const researcher = new ResearchAgent({
llm: createLLM({ provider: "gemini" })
});
const facts = await researcher.ask(`Research: ${topic}`);
// Step 2: Write
const writer = new WriterAgent({
llm: createLLM({ provider: "anthropic" })
});
const article = await writer.ask(`Write an article from these facts:\n\n${facts}`);
return article;
}
// Usage
const result = await researchAndWrite("TypeScript 5.4 features");
console.log(result);
```
**Why not wrap in tools?** Direct orchestration is clearer when you control the workflow. Use tools only when the LLM needs to decide *when* to call sub-agents dynamically.
```
---
## Structured Output
Agents support structured output via Zod schemas:
```typescript
import { Agent, z, createLLM } from "@node-llm/core";
const SentimentSchema = z.object({
sentiment: z.enum(["positive", "negative", "neutral"]),
confidence: z.number(),
keywords: z.array(z.string())
});
class SentimentAnalyzer extends Agent> {
static model = "gpt-4o";
static instructions = "Analyze the sentiment of the given text.";
static schema = SentimentSchema;
}
const llm = createLLM({ provider: "openai" });
const analyzer = new SentimentAnalyzer({ llm });
const result = await analyzer.ask("I love this product!");
console.log(result.parsed?.sentiment); // "positive"
```
---
## Inline Definition with `defineAgent()`
For quick one-off agents without creating a class:
```typescript
import { defineAgent, createLLM } from "@node-llm/core";
const QuickAgent = defineAgent({
model: "gpt-4o-mini",
instructions: "You are a helpful assistant.",
temperature: 0
});
const llm = createLLM({ provider: "openai" });
const agent = new QuickAgent({ llm });
await agent.ask("Hello!");
```
---
## Agent Inheritance
Agents support class inheritance for specialization:
```typescript
class BaseAgent extends Agent {
static model = "gpt-4o";
static temperature = 0;
}
class CodeReviewer extends BaseAgent {
static instructions = "Review code for bugs and suggest improvements.";
}
class SecurityReviewer extends BaseAgent {
static instructions = "Review code for security vulnerabilities.";
}
```
---
## Instance Overrides
Override static properties at instantiation:
```typescript
const agent = new AssistantAgent({
llm,
temperature: 0.9, // Override static temperature
maxTokens: 500 // Add runtime options
});
```
---
## Lazy Configuration & Dynamic Inputs v1.12.0+
For agents that need to adapt based on runtime context (e.g., current user, workspace, or environment), `Agent` support **Lazy Evaluation** for instructions and tools.
### Defining Lazy Behavior
Instead of static strings or arrays, use functions that receive a typed `inputs` object:
```typescript
interface WorkContext {
userName: string;
workspace: string;
}
class WorkAssistant extends Agent {
static model = "gpt-4o";
// Dynamic instructions resolved at runtime
static instructions = (inputs: WorkContext) =>
`You are helping ${inputs.userName} in the ${inputs.workspace} workspace.`;
// Dynamic tools resolved at runtime
static tools = (inputs: WorkContext) => [
new SearchDocs({ scope: inputs.workspace })
];
}
```
### Passing Inputs
You can provide inputs during instantiation or at the turn level (via `ask` or `stream`):
```typescript
// Option A: At instantiation
const agent = new WorkAssistant({
inputs: { userName: "Alice", workspace: "hr" }
});
await agent.ask("What is my salary?");
// Option B: At the request level (Explicit context)
const agent = new WorkAssistant();
await agent.ask("Hello", {
inputs: { userName: "Bob", workspace: "general" }
});
```
### Why use Lazy Evaluation?
1. **Cleaner Controllers:** No more string concatenation in your service objects or API handlers.
2. **Type Safety:** Define your `inputs` interface once and get full autocomplete.
3. **Code Sovereignty:** Business logic (how to scope a tool) stays inside the Agent class, not scattered across your app.
---
## Telemetry Hooks v1.11.0+
Agent telemetry hooks provide declarative observability for production agents. They enable debugging, cost auditing, latency tracking, and integration with monitoring systems—without cluttering your agent logic.
### Available Hooks
| Hook | When Fired | Use Cases |
|:-----|:-----------|:----------|
| `onStart(context)` | Agent session begins | Request logging, session initialization |
| `onThinking(thinking, result)` | Model generates reasoning trace | Debug extended thinking (o1, Claude) |
| `onToolStart(toolCall)` | Tool execution starts | Latency tracking, audit trails |
| `onToolEnd(toolCall, result)` | Tool execution completes | Performance metrics, result logging |
| `onToolError(toolCall, error)` | Tool execution fails | Error tracking, alerting |
| `onComplete(result)` | Agent turn finishes | Cost logging, response analytics |
### Basic Example
```typescript
import { Agent, Tool, z } from "@node-llm/core";
class WeatherTool extends Tool {
name = "get_weather";
description = "Get current weather for a city";
schema = z.object({ city: z.string() });
async execute({ city }) {
return `Sunny, 25°C in ${city}`;
}
}
class ObservableAgent extends Agent {
static model = "gpt-4o";
static tools = [WeatherTool];
static onStart(context) {
console.log(`[Agent] Started with ${context.messages.length} messages`);
}
static onToolStart(toolCall) {
console.log(`[Tool] ${toolCall.function.name} started`);
console.time(`tool-${toolCall.id}`);
}
static onToolEnd(toolCall, result) {
console.timeEnd(`tool-${toolCall.id}`);
}
static onComplete(result) {
console.log(`[Agent] Complete. Tokens: ${result.total_tokens}`);
}
}
```
### Production Monitoring
Track costs and latency in production:
```typescript
import { Agent } from "@node-llm/core";
import { metrics } from "./monitoring";
class ProductionAgent extends Agent {
static model = "gpt-4o";
static onStart(context) {
metrics.increment("agent.requests");
}
static onToolError(toolCall, error) {
metrics.increment(`tool.${toolCall.function.name}.errors`);
console.error(`Tool ${toolCall.function.name} failed:`, error);
}
static onComplete(result) {
metrics.gauge("agent.cost", result.usage.cost);
metrics.gauge("agent.tokens", result.total_tokens);
}
}
```
### Debug Extended Thinking
For models with extended thinking (o1, Claude):
```typescript
class ThinkingAgent extends Agent {
static model = "o1-preview";
static thinking = { effort: "high" };
static onThinking(thinking, result) {
console.log("🧠 Reasoning:", thinking.text);
console.log(`Thinking tokens: ${thinking.tokens}`);
}
}
```
### Async Hooks
All hooks support async operations:
```typescript
class AuditedAgent extends Agent {
static model = "gpt-4o";
static async onComplete(result) {
await db.metrics.create({
model: result.model,
tokens: result.total_tokens,
cost: result.usage.cost
});
}
}
```
---
## Agent Persistence with @node-llm/orm v0.5.0+
For long-running agents that need to persist conversations across requests (e.g., support tickets, chat sessions), use `AgentSession` from `@node-llm/orm`.
```bash
npm install @node-llm/orm @prisma/client
```
### Create & Resume Sessions
```typescript
import { Agent, Tool, z, createLLM } from "@node-llm/core";
import { createAgentSession, loadAgentSession } from "@node-llm/orm/prisma";
import { PrismaClient } from "@prisma/client";
const prisma = new PrismaClient();
const llm = createLLM({ provider: "openai" });
// Define agent (configuration lives in code)
class SupportAgent extends Agent {
static model = "gpt-4.1";
static instructions = "You are a helpful support agent.";
static tools = [LookupOrderTool, CancelOrderTool];
}
// Create a persistent session
const session = await createAgentSession(prisma, llm, SupportAgent, {
metadata: { userId: "user_123", ticketId: "TKT-456" }
});
await session.ask("Where is my order #789?");
console.log(session.id); // "abc-123" - save this to resume later
// Resume in a later request
const session = await loadAgentSession(prisma, llm, SupportAgent, "abc-123");
await session.ask("Can you cancel it?");
```
### The "Code Wins" Principle
When you resume a session, the agent uses **current code configuration** but **database history**:
| Aspect | Source | Rationale |
|:-------|:-------|:----------|
| Model | Agent class | Immediate upgrades when you deploy |
| Tools | Agent class | Only code can execute functions |
| Instructions | Agent class | Deploy prompt fixes immediately |
| History | Database | Sacred, never modified |
This means if you deploy an upgrade (new model, better prompt), all resumed sessions get the improvement automatically.
### Prisma Schema
Add `LlmAgentSession` to your schema:
```prisma
model LlmAgentSession {
id String @id @default(uuid())
agentClass String // Validated on load (e.g., 'SupportAgent')
chatId String @unique
metadata Json?
createdAt DateTime @default(now())
updatedAt DateTime @updatedAt
chat LlmChat @relation(fields: [chatId], references: [id], onDelete: Cascade)
@@index([agentClass])
@@index([createdAt])
}
model LlmChat {
// ... existing fields
agentSession LlmAgentSession?
}
```
See the [@node-llm/orm documentation](https://node-llm.eshaiju.com/orm/prisma) for full details.
---
## Next Steps
- [Tool Calling Guide](tools.html) — Deep dive on tool patterns and safety
- [Agentic Workflows](../advanced/agentic-workflows.html) — Advanced patterns like parallel execution and supervisor patterns
- [HR Chatbot RAG](https://github.com/node-llm/node-llm/tree/main/examples/applications/hr-chatbot-rag) — Full RAG implementation
----------------------------------------
# 📄 core-features/audio-transcription.md
---
layout: default
title: Audio Transcription
parent: Core Features
nav_order: 6
description: Convert speech to text using specialized models like Whisper or leverage multimodal models for native audio understanding and analysis.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Convert audio files to text using models like OpenAI's Whisper or Google's Gemini. `NodeLLM` supports both raw transcription and multimodal chat analysis.
---
## Basic Transcription
Use `NodeLLM.transcribe()` for direct speech-to-text conversion.
```ts
const text = await NodeLLM.transcribe("meeting.mp3", {
model: "whisper-1"
});
console.log(text.toString());
```
---
## Advanced Options
### Speed vs Accuracy
You can choose different models or parameters depending on your needs.
```ts
await NodeLLM.transcribe("audio.mp3", {
model: "whisper-1",
language: "en", // ISO-639-1 code hint to improve accuracy
prompt: "ZyntriQix, API" // Guide the model with domain-specific terms
});
```
### Accessing Segments & Timestamps
The `transcribe` method returns a `Transcription` object that contains more than just text. You can access detailed timing information if supported by the provider (e.g., using `response_format: 'verbose_json'` with OpenAI).
```ts
const response = await NodeLLM.transcribe("interview.mp3", {
params: { response_format: "verbose_json" }
});
console.log(`Duration: ${response.duration}s`);
for (const segment of response.segments) {
console.log(`[${segment.start}s - ${segment.end}s]: ${segment.text}`);
}
```
---
## Multimodal Chat vs. Transcription
There are two ways to work with audio:
1. **Transcription (`NodeLLM.transcribe`)**: Best when you need the verbatim text.
- _Result_: "Hello everyone today we are..."
2. **Multimodal Chat (`chat.ask`)**: Best when you need to **analyze** or **summarize** the audio directly, without seeing the raw text first. Supported by models like `gemini-1.5-pro` and `gpt-4o`.
```ts
// Multimodal Chat Example
const chat = NodeLLM.chat("gemini-1.5-pro");
await chat.ask("What is the main topic of this podcast?", {
files: ["podcast.mp3"]
});
```
---
## Error Handling
Audio files can be large and prone to timeouts.
```ts
try {
await NodeLLM.transcribe("large-file.mp3");
} catch (error) {
console.error("Transcription failed:", error.message);
}
```
----------------------------------------
# 📄 core-features/chat.md
---
layout: default
title: Chat
parent: Core Features
nav_order: 1
permalink: /core-features/chat
description: A unified interface for stateful conversations across all providers. Learn how to manage history, instructions, and lifecycle hooks.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
`NodeLLM` provides a unified chat interface across all supported providers (OpenAI, Anthropic, Gemini, DeepSeek, Bedrock, OpenRouter, xAI, Ollama, Mistral). It normalizes the differences in their APIs, allowing you to use a single set of methods for interacting with them.
```bash
npm install @node-llm/core
```
---
## Starting a Conversation
The core entry point is `NodeLLM.chat(model_id?, options?)`.
```ts
import "dotenv/config";
import { NodeLLM } from "@node-llm/core";
// 1. Get a chat instance
// (No setup required if NODELLM_PROVIDER is in env)
const chat = NodeLLM.chat("gpt-4o-mini");
// 2. Ask a question
const response = await chat.ask("What is the capital of France?");
console.log(response.content); // "The capital of France is Paris."
```
### Continuing the Conversation
The `chat` object maintains a history of the conversation, so you can ask follow-up questions naturally.
```ts
await chat.ask("What is the capital of France?");
// => "Paris"
await chat.ask("What is the population there?");
// => "The population of Paris is approximately..."
```
---
## System Prompts (Instructions)
Guide the AI's behavior, personality, or constraints using system prompts. You can set this when creating the chat or update it later.
```ts
// Option 1: Set at initialization
const chat = llm.chat("gpt-4o", {
systemPrompt: "You are a helpful assistant that answers in rhyming couplets."
});
// Option 2: Set or update later
chat.withInstructions("Now speak like a pirate.");
// Option 3: Standard Alias v1.6.0
chat.system("You are a helpful assistant.");
await chat.ask("Hello");
// => "Ahoy matey! The seas are calm today."
```
---
## Manual History Management v1.6.0
While NodeLLM handles history automatically during a session, you can manually inject messages into the conversation. This is especially useful for **Session Rehydration** from a database.
```ts
const chat = NodeLLM.chat("gpt-4o");
// Rehydrate previous turns from your DB
chat
.add("user", "What is my name?")
.add("assistant", "You told me your name is Alice.");
const response = await chat.ask("What did I just say?");
// => "You asked me what your name is."
```
The `.add()` method correctly isolates `system` and `developer` roles while maintaining chronological order for `user` and `assistant` messages.
---
## Custom HTTP Headers
Some providers offer beta features or require specific headers (like for observability proxies).
```ts
// Enable Anthropic's beta features
const chat = llm.chat("claude-3-5-sonnet").withRequestOptions({
headers: {
"anthropic-beta": "max-tokens-3-5-sonnet-2024-07-15"
}
});
await chat.ask("Tell me about the weather");
```
---
## Raw Content Blocks (Advanced)
For advanced use cases like **Anthropic Prompt Caching**, you can pass provider-specific content blocks directly. `NodeLLM` attempts to pass array content through to the provider.
```ts
// Example: Anthropic Prompt Caching
const systemBlock = {
type: "text",
text: "You are a coding assistant. (Cached context...)",
cache_control: { type: "ephemeral" }
};
const chat = llm.chat("claude-3-5-sonnet", {
systemPrompt: systemBlock as any // Cast if strict types complain
});
```
---
## Working with Multiple Providers
### Isolation and Multi-Tenancy
`NodeLLM` is a **frozen, immutable instance**. It cannot be mutated at runtime. This design ensures that configurations (like API keys) do not leak between different parts of your application, making it safe for multi-tenant environments like SaaS or serverless functions.
If you need isolated configurations for different users or requests, use `createLLM()` or `NodeLLM.withProvider()`.
```ts
import { createLLM } from "@node-llm/core";
// Safe for multi-tenant apps
const userA = createLLM({ provider: "openai", openaiApiKey: "..." });
const userB = createLLM({ provider: "anthropic", anthropicApiKey: "..." });
await userA.chat().ask("Hello!"); // Uses User A's key
await userB.chat().ask("Hello!"); // Uses User B's key
```
### ⚡ Scoped Instances
Use `withProvider()` to create isolated instances with their own configuration. Each instance maintains separate state without affecting others.
```ts
// ✅ SAFE: Each instance is isolated
const tenant1 = NodeLLM.withProvider("openai", {
openaiApiKey: tenant1Key,
requestTimeout: 30000
});
const tenant2 = NodeLLM.withProvider("openai", {
openaiApiKey: tenant2Key,
requestTimeout: 60000
});
// No interference - each has its own config
await Promise.all([tenant1.chat("gpt-4o").ask(prompt), tenant2.chat("gpt-4o").ask(prompt)]);
```
**Multi-provider parallelism:**
```ts
const [gpt, claude, gemini] = await Promise.all([
NodeLLM.withProvider("openai").chat("gpt-4o").ask(prompt),
NodeLLM.withProvider("anthropic").chat("claude-3-5-sonnet").ask(prompt),
NodeLLM.withProvider("gemini").chat("gemini-2.0-flash").ask(prompt)
]);
```
**Per-request isolation in Express/Fastify:**
```ts
app.post("/chat", async (req, res) => {
const userApiKey = req.user.openaiApiKey; // From database
// Create isolated instance per request
const llm = NodeLLM.withProvider("openai", {
openaiApiKey: userApiKey
});
const response = await llm.chat("gpt-4o").ask(req.body.message);
res.json(response);
});
```
---
## Temperature & Creativity
Adjust the randomness of the model's responses using `.withTemperature(0.0 - 1.0)`.
```ts
// Deterministic / Factual (Low Temperature)
const factual = NodeLLM.chat("gpt-4o").withTemperature(0.0);
// Creative / Random (High Temperature)
const creative = NodeLLM.chat("gpt-4o").withTemperature(0.9);
```
---
## Lifecycle Events Enhanced in v1.5.0
Hook into the chat lifecycle for logging, UI updates, audit trails, or debugging.
```ts
chat
.onNewMessage(() => console.log("AI started typing..."))
.onToolCallStart((call) => console.log(`Starting tool: ${call.function.name}`))
.onToolCallEnd((call, res) => console.log(`Tool ${call.id} finished with: ${res}`))
.onToolCallError((call, err) =>
console.error(`Tool ${call.function.name} failed: ${err.message}`)
)
.onEndMessage((response) => {
console.log(`Finished. Total tokens: ${response.total_tokens}`);
});
await chat.ask("What's the weather?");
```
---
## 🛡️ Content Policy Hooks
NodeLLM allows you to plug in custom security and compliance logic through asynchronous hooks. This is useful for PII detection, redaction, and enterprise moderation policies.
- **`beforeRequest(handler)`**: Analyze or modify the message history before it is sent to the provider.
- **`afterResponse(handler)`**: Analyze or modify the AI's response before it is returned to your application.
```ts
chat
.beforeRequest(async (messages) => {
// Redact SSNs from user input
return messages.map((m) => ({
...m,
content: m.content.replace(/\d{3}-\d{2}-\d{4}/g, "[REDACTED]")
}));
})
.afterResponse(async (response) => {
// Block responses containing prohibited words
if (response.content.includes("Prohibited")) {
throw new Error("Compliance Violation");
}
});
```
---
## Retry Logic & Safety 🛡️
By default, `NodeLLM` handles network instabilities or temporary provider errors (like 500s or 429 Rate Limits) by retrying the request.
- **Default Retries**: 2 retries (3 total attempts).
- **Request Timeout**: 30 seconds (prevents hanging requests).
- **Loop Guard**: Tool calling is limited to 5 turns to prevent infinite loops.
You can configure these limits globally:
```ts
const llm = createLLM({
maxRetries: 3, // Increase retries for unstable connections
maxToolCalls: 10, // Allow deeper tool calling sequences
requestTimeout: 60000 // 60 second timeout for long-running requests
});
```
Or override per-request:
```ts
// Long-running task with extended timeout
await chat.ask("Analyze this large dataset", {
requestTimeout: 120000 // 2 minutes
});
```
### Request Cancellation v1.5.3+
You can cancel long-running requests using the standard `AbortController` API. This is useful for interactive UIs where users might navigate away or click "Stop".
```ts
const controller = new AbortController();
// Cancel after 5 seconds
setTimeout(() => controller.abort(), 5000);
try {
const response = await chat.ask("Write a very long essay...", {
signal: controller.signal
});
} catch (error) {
if (error.name === "AbortError") {
console.log("Request was cancelled");
}
}
```
The signal is propagated through all tool-calling turns, so even multi-step agentic workflows can be cancelled cleanly.
See the [Configuration Guide](/getting-started/configuration) for more details.
---
## 🧱 Smart Context Isolation
NodeLLM provides **Zero-Config Context Isolation** to ensure maximum instruction following and security.
Inspired by modern LLM architectures (like OpenAI's Developer Role), NodeLLM internally separates your system instructions from the conversation history. This prevents "instruction drift" as the conversation grows and provides a strong layer of protection against prompt injection.
### How It Works
- **Implicit Untangling**: If you pass a mixed array of messages to the Chat constructor, NodeLLM automatically identifies and isolates system-level instructions.
- **Dynamic Role Mapping**: On the official OpenAI API, instructions for modern models (`gpt-4o`, `o1`, `o3`) are automatically promoted to the high-privilege `developer` role.
- **Safe Fallbacks**: For older models or local providers (like Ollama or DeepSeek), NodeLLM safely maps instructions back to the standard `system` role to ensure perfect compatibility.
This behavior is **enabled by default** for all chats.
----------------------------------------
# 📄 core-features/embeddings.md
---
layout: default
title: Embeddings
parent: Core Features
nav_order: 3
description: Generate high-dimensional vector representations for semantic search, RAG, and clustering with single and batch embedding operations.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Embeddings are vector representations of text used for semantic search, clustering, and similarity comparisons. \`NodeLLM\` provides a unified interface for generating embeddings across different providers.
## Basic Usage
### Single Text
```ts
import { createLLM } from "@node-llm/core";
const embedding = await NodeLLM.embed("Ruby is a programmer's best friend");
console.log(embedding.vector); // number[] (e.g., 1536 dimensions)
console.log(embedding.dimensions); // 1536
console.log(embedding.model); // "text-embedding-3-small" (default)
console.log(embedding.input_tokens); // Token count
```
### Batch Embeddings
Always batch multiple texts in a single call when possible. This is much more efficient than calling `embed` in a loop.
```ts
const embeddings = await NodeLLM.embed(["First text", "Second text", "Third text"]);
console.log(embeddings.vectors.length); // 3
console.log(embeddings.vectors[0]); // Vector for "First text"
```
## Configuring Models
By default, `NodeLLM` uses `text-embedding-3-small`. You can change this globally or per request.
### Global Configuration
```ts
const llm = createLLM({
defaultEmbeddingModel: "text-embedding-3-large"
});
```
### Per-Request
```ts
const embedding = await NodeLLM.embed("Text", {
model: "text-embedding-004" // Google Gemini model
});
```
### Custom Models
For models not in the registry (e.g., Azure deployments or new releases), use `assumeModelExists`.
```ts
const embedding = await NodeLLM.embed("Text", {
model: "new-embedding-v2",
provider: "openai",
assumeModelExists: true
});
```
## Reducing Dimensions
Some models (like `text-embedding-3-large`) allow you to reduce the output dimensions to save on storage and compute, with minimal loss in accuracy.
```ts
const embedding = await NodeLLM.embed("Text", {
model: "text-embedding-3-large",
dimensions: 256
});
console.log(embedding.vector.length); // 256
```
## Best Practices
1. **Batching**: Use `NodeLLM.embed(["text1", "text2"])` instead of serial calls.
2. **Caching**: Embeddings are deterministic for a given model and text. Cache them in your database to save costs.
3. **Cosine Similarity**: To compare two vectors, calculate the cosine similarity. `NodeLLM` does not include math utilities to keep the core light, but you can implement it easily:
```ts
function cosineSimilarity(A: number[], B: number[]) {
const dotProduct = A.reduce((sum, a, i) => sum + a * B[i], 0);
const magnitudeA = Math.sqrt(A.reduce((sum, a) => sum + a * a, 0));
const magnitudeB = Math.sqrt(B.reduce((sum, b) => sum + b * b, 0));
return dotProduct / (magnitudeA * magnitudeB);
}
```
## Error Handling
Wrap calls in try/catch blocks to handle API outages or rate limits.
```ts
try {
await NodeLLM.embed("Text");
} catch (error) {
console.error("Embedding failed:", error.message);
}
```
----------------------------------------
# 📄 core-features/image-generation.md
---
layout: default
title: Image Generation
nav_order: 7
parent: Core Features
description: Create photorealistic images and digital art from text descriptions using DALL-E, Imagen, and other integrated image models.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Generate images from text descriptions using models like DALL-E, Imagen, and others.
## Basic Usage
The simplest way is using `NodeLLM.paint(prompt)`.
```ts
// Uses default model (e.g. dall-e-3)
const image = await NodeLLM.paint("A red panda coding");
console.log(`Image URL: ${image}`); // Acts as a string URL
```
## Choosing Models & Sizes
Customize the model and dimensions.
```ts
const image = await NodeLLM.paint("A red panda coding", {
model: "dall-e-3",
size: "1024x1792", // Portrait
quality: "hd" // DALL-E 3 specific
});
```
Supported sizes vary by model. Check your provider's documentation.
## Working with the Image Object
The return value is a `GeneratedImage` object which behaves like a URL string but contains rich metadata and helper methods.
```ts
const image = await NodeLLM.paint("A landscape");
// Metadata
console.log(image.url); // "https://..."
console.log(image.revisedPrompt); // "A photorealistic landscape..." (DALL-E 3)
console.log(image.mimeType); // "image/png"
// Check if it's base64 (some providers return data, not URLs)
if (image.isBase64) {
console.log("Image data received directly.");
}
```
## Saving & Processing
You can easily save the image or get its raw buffer for further processing (e.g., uploading to S3).
```ts
// Save to disk
await image.save("./output.png");
// Get raw buffer (works for both URL and Base64 source)
const buffer = await image.toBuffer();
console.log(`Size: ${buffer.length} bytes`);
// Stream it (e.g. to HTTP response)
const stream = await image.toStream();
stream.pipe(process.stdout);
```
----------------------------------------
# 📄 core-features/index.md
---
layout: default
title: Core Features
nav_order: 3
has_children: true
nav_fold: false
permalink: /core-features
description: Deep dive into the primary capabilities of NodeLLM, including chat, tools, vision, and reasoning.
back_to_top: false
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
----------------------------------------
# 📄 core-features/middlewares.md
---
layout: default
title: Middlewares
parent: Core Features
nav_order: 13
permalink: /core-features/middlewares
description: Intercept and modify LLM requests and responses with production-grade middlewares.
---
# Middlewares
{: .no_toc }
NodeLLM's middleware system allows you to intercept, monitor, and modify LLM interactions at the infrastructure level. This is essential for building production-grade systems that require observability, auditing, cost tracking, and safety.
1. TOC
{:toc}
---
## Why Middlewares?
In a production environment, you rarely want to call an LLM directly without additional logic. Middlewares allow you to separate these cross-cutting concerns from your business logic:
- **Observability**: Log requests, responses, and errors to external systems.
- **Cost Tracking**: Calculate and record the token usage and cost of every request.
- **Security & Compliance**: Redact PII (Personally Identifiable Information) before it segments to the LLM.
- **Auditing**: Maintain a permanent audit trail of all AI interactions.
- **Performance**: Track latency and success rates across different models.
- **Quality**: Automatically verify the integrity of the response.
---
## Basic Usage
Middlewares are passed when creating a chat instance. You can pass a single middleware or an array of middlewares.
```typescript
import { NodeLLM, Middleware, ChatResponseString } from "@node-llm/core";
const myMiddleware: Middleware = {
name: "MyMiddleware",
onRequest: async (context) => {
console.log(`[Request] Sending to ${context.model}`);
},
onResponse: async (context, result) => {
// result is NodeLLMResponse (union of Chat, Image, Transcription, etc.)
if (result instanceof ChatResponseString) {
console.log(`[Response] Received ${result.usage.total_tokens} tokens`);
}
}
};
const chat = NodeLLM.chat("gpt-4o", {
middlewares: [myMiddleware]
});
await chat.ask("Hello world");
```
---
## The Middleware Interface (v1.10.0+)
A middleware consists of a unique name and several optional hooks that cover the entire lifecycle of an LLM request, including tool execution.
```typescript
interface Middleware {
name: string;
onRequest?: (context: MiddlewareContext) => Promise | void;
onResponse?: (context: MiddlewareContext, result: NodeLLMResponse) => Promise | void;
onError?: (context: MiddlewareContext, error: Error) => Promise | void;
// Tool Execution Hooks
onToolCallStart?: (context: MiddlewareContext, tool: ToolCall) => Promise | void;
onToolCallEnd?: (context: MiddlewareContext, tool: ToolCall, result: unknown) => Promise | void;
onToolCallError?: (context: MiddlewareContext, tool: ToolCall, error: Error) => Promise | ToolErrorDirective;
}
```
> **Warning**: Since `v1.10.0`, the `onResponse` hook receives a `NodeLLMResponse` union. You must use a type guard (like `instanceof ChatResponseString`) before accessing chat-specific properties like `usage` or `content`.
### MiddlewareContext
The `context` object is persistent across the lifecycle of a single request and provides deep access to the execution state:
- `requestId`: A unique UUID for tracing the request.
- `provider`: The provider name (e.g., "openai", "anthropic").
- `model`: The model identifier.
- `messages`: The conversation history (mutable in `onRequest`).
- `options`: The `ChatOptions` for the request (mutable in `onRequest`).
- `state`: A record for sharing data between hooks in the same middleware (e.g., storing a timer).
- `metadata`: Custom metadata passed to the request.
- **Operation Specifics**: `input` (Embeddings), `imageOptions` (Paint), etc.
---
## Common Use Cases
### 1. PII Redaction (Security)
Redact sensitive information before it reaches the provider.
```typescript
const piiMiddleware = {
name: "PIIRedactor",
onRequest: async (context) => {
context.messages.forEach(msg => {
msg.content = msg.content.replace(/\b\d{4}-\d{4}-\d{4}-\d{4}\b/g, "[REDACTED_CC]");
});
}
}
```
### 2. Cost & Performance Tracking
Use standard telemetry patterns to track your infrastructure.
```typescript
const perfMiddleware = {
name: "PerformanceTracker",
onRequest: async (context) => {
context.state.startTime = Date.now();
},
onResponse: async (context, result) => {
const latency = Date.now() - (context.state.startTime as number);
// Safety check for usage metrics
if (result instanceof ChatResponseString) {
const cost = calculateCost(context.model, result.usage);
await db.metrics.create({ model: context.model, latency, cost });
}
}
}
```
---
## Middleware Execution Order (v1.10.0+)
Middlewares are executed as a **stack** (Onion model). This ensures that outer middlewares (like loggers) can correctly wrap and observe the transformations made by inner middlewares (like security maskers).
- **onRequest**: Executed in order (first to last).
- **onToolCallStart**: Executed in order (first to last).
- **onToolCallEnd**: Executed in **REVERSE** order (last to first).
- **onToolCallError**: Executed in **REVERSE** order (last to first).
- **onResponse**: Executed in **REVERSE** order (last to first).
- **onError**: Executed in **REVERSE** order (last to first).
### Example Lifecycle
If you have two middlewares: `[Logger, Security]`, the execution order for a successful tool-calling request is:
1. `Logger.onRequest`
2. `Security.onRequest`
3. `Logger.onToolCallStart`
4. `Security.onToolCallStart`
5. ... Tool Execution ...
6. `Security.onToolCallEnd`
7. `Logger.onToolCallEnd`
8. `Security.onResponse`
9. `Logger.onResponse`
---
## Standard Middleware Library
NodeLLM includes a set of pre-built, production-ready middlewares that you can use out of the box.
### 1. PIIMaskMiddleware
Automatically redacts sensitive information like emails, phone numbers, and credit cards from user messages before they are sent to the LLM.
```typescript
import { NodeLLM, PIIMaskMiddleware } from "@node-llm/core";
const chat = NodeLLM.chat("gpt-4o", {
middlewares: [new PIIMaskMiddleware({ mask: "[SECRET]" })]
});
```
### 2. CostGuardMiddleware
Monitors accumulated cost during a session (especially useful for multi-turn tool calling loops) and throws an error if a defined budget is exceeded.
```typescript
import { NodeLLM, CostGuardMiddleware } from "@node-llm/core";
const chat = NodeLLM.chat("gpt-4o", {
middlewares: [
new CostGuardMiddleware({
maxCost: 0.05, // $0.05 budget
onLimitExceeded: (ctx, cost) => console.log(`Budget blown for ${ctx.requestId}`)
})
]
});
```
### 3. UsageLoggerMiddleware
Standardizes telemetry by logging token usage, request IDs, and calculated costs for every successful interaction.
```typescript
import { NodeLLM, UsageLoggerMiddleware } from "@node-llm/core";
const chat = NodeLLM.chat("gpt-4o", {
middlewares: [new UsageLoggerMiddleware({ prefix: "MY-APP" })]
});
```
---
## Global Middlewares
You can also register middlewares at the global level when creating the LLM instance. These will be applied to **every** chat, embedding, or image generation call made from that instance.
```typescript
import { createLLM, UsageLoggerMiddleware } from "@node-llm/core";
const llm = createLLM({
provider: "openai",
middlewares: [new UsageLoggerMiddleware()]
});
// This chat will automatically use the global UsageLoggerMiddleware
const chat = llm.chat("gpt-4o");
```
---
## Integration with @node-llm/orm
When using the ORM, you can pass middlewares directly to the `createChat` call. They will be applied to the underlying chat instance but will NOT be persisted to the database.
```typescript
import { createChat } from "@node-llm/orm/prisma";
const chat = await createChat(prisma, llm, {
model: "gpt-4o",
middlewares: [new UsageLoggerMiddleware()]
});
```
----------------------------------------
# 📄 core-features/models.md
---
layout: default
title: Models & Registry
parent: Core Features
nav_order: 6
description: Programmatically discover available models, their capabilities, and real-time costs using our built-in registry powered by models.dev.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
\`NodeLLM\` includes a comprehensive, built-in registry of models using data from **models.dev**. This allows you to discover models and their capabilities programmatically.
---
## Inspecting a Model
You can look up any supported model to check its context window, costs, and features.
```ts
import { createLLM } from "@node-llm/core";
const model = NodeLLM.models.find("gpt-4o");
if (model) {
console.log(`Provider: ${model.provider}`);
console.log(`Context Window: ${model.context_window} tokens`);
console.log(`Input Price: $${model.pricing.text_tokens.standard.input_per_million}/1M`);
console.log(`Output Price: $${model.pricing.text_tokens.standard.output_per_million}/1M`);
}
```
---
## Discovery by Capability
You can filter the registry to find models that match your requirements.
### Finding Vision Models
```ts
const visionModels = NodeLLM.models.all().filter((m) => m.capabilities.includes("vision"));
console.log(`Found ${visionModels.length} vision-capable models.`);
visionModels.forEach((m) => console.log(m.id));
```
### Finding Tool-Use Models
```ts
const toolModels = NodeLLM.models.all().filter((m) => m.capabilities.includes("tools"));
```
### Finding Audio Models
```ts
const audioModels = NodeLLM.models.all().filter((m) => m.capabilities.includes("audio_input"));
```
---
## Supported Providers
The registry includes models from:
- **OpenAI** (GPT-4o, GPT-3.5, DALL-E)
- **Anthropic** (Claude 3.5 Sonnet, Haiku, Opus)
- **Google Gemini** (Gemini 1.5 Pro, Flash)
- **DeepSeek** (DeepSeek V3, R1)
- **AWS Bedrock** (Nova, Titan, Claude)
- **OpenRouter** (400+ models)
- **xAI** (Grok)
- **Ollama** (Local models)
- **Mistral** (Mistral Large, Codestral, Pixtral, Magistral)
---
## Custom Models & Endpoints
Sometimes you need to use models not in the registry, such as **Azure OpenAI** deployments, **Local Models** (Ollama/LM Studio), or brand new releases.
### Using `assumeModelExists`
This flag tells \`NodeLLM\` to bypass the registry check.
**Important**: You MUST specify the `provider` when using this flag, as the system cannot infer it from the ID.
```ts
const chat = NodeLLM.withProvider("openai").chat("my-custom-deployment", {
assumeModelExists: true
});
// Note: Capability checks are bypassed (assumed true) for custom models.
await chat.ask("Hello");
```
### Custom Endpoints (e.g. Azure/Local)
To point to a custom URL (like an Azure endpoint or local proxy), configure the base URL globally.
```ts
const llm = createLLM({
openaiApiBase: "https://my-azure-resource.openai.azure.com",
openaiApiKey: process.env.AZURE_API_KEY
});
// Now valid for all OpenAI requests
const chat = llm.chat("gpt-4", { provider: "openai" });
```
----------------------------------------
# 📄 core-features/moderation.md
---
layout: default
title: Moderation
parent: Core Features
nav_order: 4
description: Protect your users and your brand by checking text content against safety policies for violence, hate speech, and harassment.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Check if text content violates safety policies using \`NodeLLM.moderate\`. This is crucial for user-facing applications to prevent abuse.
## Basic Usage
The simplest check returns a flagged boolean and categories.
```ts
const result = await NodeLLM.moderate("I want to help everyone!");
if (result.flagged) {
console.log(`❌ Flagged for: ${result.flaggedCategories.join(", ")}`);
} else {
console.log("✅ Content appears safe");
}
```
## Understanding Results
The moderation result object provides detailed signals:
- `flagged`: (boolean) Overall safety check. if true, content violates provider policies.
- `categories`: (object) Boolean flags for specific buckets (e.g., `sexual: false`, `violence: true`).
- `category_scores`: (object) Confidence scores (0.0 - 1.0) for each category.
```ts
const result = await NodeLLM.moderate("Some controversial text");
// Check specific categories
if (result.categories.hate) {
console.log("Hate speech detected");
}
// Check confidence levels
console.log(`Violence Score: ${result.category_scores.violence}`);
```
### Common Categories
- **Sexual**: Sexual content.
- **Hate**: Content promoting hate based on identity.
- **Harassment**: Threatening or bullying content.
- **Self-Harm**: Promoting self-harm or suicide.
- **Violence**: Promoting or depicting violence.
## Integration Patterns
### Pre-Chat Moderation
We recommend validating user input _before_ sending it to a Chat model to save costs and prevent jailbreaks.
```ts
async function safeChat(input: string) {
const mod = await NodeLLM.moderate(input);
if (mod.flagged) {
throw new Error(`Content Unsafe: ${mod.flaggedCategories.join(", ")}`);
}
// Only proceed if safe
return await chat.ask(input);
}
```
### Custom Risk Thresholds
Providers have their own thresholds for "flagging". You can implement stricter (or looser) logic using raw scores.
```ts
const result = await NodeLLM.moderate(userInput);
// Custom strict policy: Flag anything with > 0.1 confidence
const isRisky = Object.entries(result.category_scores).some(([category, score]) => score > 0.1);
if (isRisky) {
console.warn("Potential risk detected (custom strict mode)");
}
```
----------------------------------------
# 📄 core-features/multimodal.md
---
layout: default
title: Multi-modal
parent: Core Features
nav_order: 2
description: Go beyond text. Learn how to pass images, audio, video, and documents to modern models using NodeLLM’s unified file handling system.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Modern LLMs can understand more than just text. `NodeLLM` provides a unified way to pass images, audio, video, and documents to models that support them.
---
## Quick Start
```ts
// Single file
await chat.ask("What's in this image?", { files: ["photo.jpg"] });
// Multiple files
await chat.ask("Analyze these", {
files: ["diagram.png", "report.pdf", "meeting.mp3"]
});
// URL or local path
await chat.ask("Describe this", { files: ["https://example.com/image.png"] });
```
---
## Provider Support
| File Type | Gemini | OpenAI | Anthropic | Bedrock | Mistral |
|-----------|--------|--------|-----------|---------|----------|
| **Images** | ✅ | ✅ | ✅ | ✅ | ✅ (Pixtral) |
| **PDFs** | ✅ | ✅ | ✅ | ✅ | ❌ |
| **Audio** | ✅ | ✅ | ❌ | ❌ | ✅ (Voxtral) |
| **Video** | ✅ | ⚠️ | ❌ | ❌ | ❌ |
| **Code/Text** | ✅ | ✅ | ✅ | ✅ | ✅ |
_⚠️ = Limited support (e.g., frame extraction)_
---
## Smart File Handling
You can pass local paths or URLs directly to the `ask` or `stream` method using the `files` (or `images`) option. `NodeLLM` automatically detects the file type and formats it correctly for the specific provider.
**Supported File Types:**
- **Images**: `.jpg`, `.jpeg`, `.png`, `.gif`, `.webp`
- **Videos**: `.mp4`, `.mpeg`, `.mov`, `.avi`, `.webm`
- **Audio**: `.wav`, `.mp3`, `.ogg`, `.flac`
- **Documents**: `.pdf`, `.csv`, `.json`, `.xml`, `.md`, `.txt`
- **Code**: `.js`, `.ts`, `.py`, `.rb`, `.go`, etc.
---
## Working with Images (Vision)
Vision-capable models (like `gpt-4o`, `claude-3-5-sonnet`, `gemini-1.5-pro`) can analyze images.
```ts
const chat = NodeLLM.chat("gpt-4o");
// Analyze a local image
await chat.ask("What's in this image?", {
files: ["./screenshot.png"]
});
// Analyze an image from a URL
await chat.ask("Describe this logo", {
files: ["https://example.com/logo.png"]
});
// Compare multiple images
await chat.ask("Compare the design of these two apps", {
files: ["./v1-screenshot.png", "./v2-screenshot.png"]
});
```
---
## Working with Audio
Audio-capable models (like `gemini-1.5-flash`) can listen to audio files and answer questions about them.
```ts
const chat = NodeLLM.chat("gemini-1.5-flash");
// Summarize a meeting recording
await chat.ask("Summarize the key decisions in this meeting", {
files: ["./meeting.mp3"]
});
// Transcribe and analyze
await chat.ask("What was the tone of the speaker?", {
files: ["./voicemail.wav"]
});
```
_Note: For pure transcription without chat, see [Audio Transcription](/core-features/audio-transcription.html)._
---
## Working with Videos
Video analysis is currently supported primarily by Google Gemini and limited OpenAI models. `NodeLLM` handles the upload and reference process seamlessly.
```ts
const chat = NodeLLM.chat("gemini-1.5-pro");
await chat.ask("What happens in this video?", {
files: ["./demo_video.mp4"]
});
```
---
## Working with Documents (PDFs & Text)
You can provide full documents for analysis.
### Text & Code Files
For text-based files, `NodeLLM` reads the content and passes it as text context to the model.
```ts
const chat = NodeLLM.chat("claude-3-5-sonnet");
// Analyze code
await chat.ask("Explain potential bugs in this code", {
files: ["./app/auth.ts"]
});
```
### PDFs
For PDFs, providers handled differently:
- **Anthropic**: Supports native PDF blocks (up to 10MB). `NodeLLM` handles the base64 encoding.
- **Gemini**: Supports PDF via File API.
- **OpenAI**: Often requires text extraction first (unless using Assistants API).
```ts
await chat.ask("Summarize this contract", {
files: ["./contract.pdf"]
});
```
---
## Automatic Type Detection
You don't need to specify the file type; `NodeLLM` infers it from the extension.
```ts
// Mix and match types
await chat.ask("Analyze these project resources", {
files: [
"diagram.png", // Image
"spec.pdf", // Document
"meeting.mp3", // Audio
"backend.ts" // Code
]
});
```
----------------------------------------
# 📄 core-features/reasoning.md
---
layout: default
title: Reasoning
parent: Core Features
nav_order: 10
description: Access the inner thoughts and chain-of-thought process of advanced reasoning models like DeepSeek R1 and OpenAI o1/o3.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
**Added in v1.7.0**
{: .label .label-green }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
`NodeLLM` provides a unified way to access the "thinking" or "reasoning" process of models like **DeepSeek R1**, **OpenAI o1/o3**, and **Claude 3.7/4**. Many models now expose their internal chain of thought or allow configuring the amount of effort spent on reasoning.
---
## Configuring Thinking
You can control the reasoning behavior using the `.withThinking()` or `.withEffort()` methods. This is particularly useful for models like `o3-mini` or `claude-3-7-sonnet`.
### Setting Effort Level
Effort levels (low, medium, high) allow you to balance between speed/cost and reasoning depth.
```ts
import { NodeLLM } from "@node-llm/core";
const chat = NodeLLM.chat("o3-mini")
.withEffort("high"); // Options: "low", "medium", "high"
const response = await chat.ask("Solve this complex architecture problem...");
```
### Per-Request Configuration
If you prefer to be stateless or set configuration only for a specific request, you can pass the thinking configuration directly to `ask()` or `stream()`.
```ts
const response = await chat.ask("Solve this puzzle", {
thinking: { budget: 16000 }
});
```
---
## Accessing Thinking Results
The results of thinking are available via the `.thinking` property on the response object. This unified object contains the text, tokens used, and any cryptographic signatures provided by the model.
```ts
const response = await chat.ask("Prove that the square root of 2 is irrational.");
// High-level access via response.thinking
if (response.thinking) {
console.log("Thought Process:", response.thinking.text);
console.log("Tokens Spent:", response.thinking.tokens);
console.log("Verification Signature:", response.thinking.signature);
}
// Show the final answer
console.log("Answer:", response.content);
```
### Streaming Thinking
When using `.stream()`, thinking content is emitted in chunks. You can capture it by checking `chunk.thinking`.
```ts
const chat = NodeLLM.chat("deepseek-reasoner");
for await (const chunk of chat.stream("Explain quantum entanglement")) {
if (chunk.thinking?.text) {
process.stdout.write(`[Thinking] ${chunk.thinking.text}`);
}
if (chunk.content) {
process.stdout.write(chunk.content);
}
}
```
---
## Backward Compatibility (Deprecated)
Previously, reasoning text was accessed via the `response.reasoning` property. While still supported for backward compatibility, it is recommended to transition to the structured `response.thinking.text` API.
---
## Supported Capabilities
Currently, the following models have enhanced reasoning support in `NodeLLM`:
| Model ID | Provider | Support Level |
| :--------------------------------- | :-------- | :------------------------------------------------ |
| `deepseek-reasoner` | DeepSeek | Full text extraction |
| `o1-*`, `o3-*` | OpenAI | Effort configuration & token tracking |
| `claude-3-7-*`, `claude-*-4-*` | Anthropic | Budget-based thinking & full text extraction |
| `gemini-2.0-flash-thinking-*` | Gemini | Full thinking text extraction |
| `magistral-*` | Mistral | Always-on thinking & full text extraction |
----------------------------------------
# 📄 core-features/streaming.md
---
layout: default
title: Stream Responses
nav_order: 2
parent: Core Features
description: Implement real-time user experiences with low-latency responses using standard AsyncIterators and seamless tool execution loops.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
For real-time interactions, `NodeLLM` supports streaming responses via standard JavaScript `AsyncIterator`s. This allows you to display text to the user as it's being generated, reducing perceived latency.
---
## Basic Streaming
Use the `stream()` method on a chat instance to get an iterator.
```ts
const chat = NodeLLM.chat("gpt-4o");
process.stdout.write("Assistant: ");
for await (const chunk of chat.stream("Write a haiku about code.")) {
// Most chunks contain content
if (chunk.content) {
process.stdout.write(chunk.content);
}
}
// => Code flows like water
// Logic builds a new world now
// Bugs swim in the stream
```
---
## Understanding Chunks
Each chunk passed to your loop contains partial information about the response.
- `content`: The text fragment for this specific chunk. Can be empty contextually.
- `role`: Usually "assistant".
- `model`: The model ID.
- `usage`: (Optional) Token usage stats. Usually only present in the final chunk (provider dependent).
```ts
for await (const chunk of chat.stream("Hello")) {
console.log(chunk);
// { content: "He", role: "assistant", ... }
// { content: "llo", role: "assistant", ... }
}
```
---
## Streaming with Tools New ✨
Tools now work seamlessly with streaming! When a model decides to call a tool during streaming, `NodeLLM` automatically:
1. **Executes the tool** with the provided arguments
2. **Adds the result** to the conversation history
3. **Continues streaming** the model's final response
This all happens transparently—you just iterate over chunks as usual!
```ts
class WeatherTool extends Tool {
name = "get_weather";
description = "Get current weather";
schema = z.object({
location: z.string().describe("The city e.g. Paris")
});
async execute({ location }) {
return { location, temp: 22, condition: "sunny" };
}
}
const chat = NodeLLM.chat("gpt-4o").withTool(WeatherTool);
// Tool is automatically executed during streaming!
for await (const chunk of chat.stream("What's the weather in Paris?")) {
process.stdout.write(chunk.content || "");
}
// Output: "The weather in Paris is currently 22°C and sunny."
```
### Tool Events in Streaming
You can also listen to tool execution events:
```ts
const chat = NodeLLM.chat("gpt-4o")
.withTool(WeatherTool)
.onToolCall((call) => {
console.log(`\n[Tool Called: ${call.function.name}]`);
})
.onToolResult((result) => {
console.log(`[Tool Result: ${JSON.stringify(result)}]\n`);
});
for await (const chunk of chat.stream("Weather in Tokyo?")) {
process.stdout.write(chunk.content || "");
}
```
**Supported Providers:** OpenAI, Anthropic, Gemini, DeepSeek, Mistral
---
## Multimodal & Structured Streaming New ✨
`chat.stream()` now supports the same advanced features as `chat.ask()`.
### Multimodal Streaming
Pass images, audio, or documents just like you would with a standard request.
```ts
const chat = NodeLLM.chat("gpt-4o");
for await (const chunk of chat.stream("What's in this image?", {
images: ["./analysis.png"]
})) {
process.stdout.write(chunk.content || "");
}
```
### Structured Streaming (Validated JSON)
Get streaming JSON that is automatically validated against a Zod schema.
```ts
const personSchema = z.object({
name: z.string(),
hobbies: z.array(z.string())
});
for await (const chunk of chat.withSchema(personSchema).stream("Generate a person profile")) {
// Chunks will contain partial content that cumulatively forms valid JSON
// Once the stream completes, history will contain the validated object
process.stdout.write(chunk.content || "");
}
```
---
## Error Handling
Stream interruptions (network failure, rate limits) will throw an error within the `for await` loop. Always wrap in a `try/catch` block.
```ts
try {
for await (const chunk of chat.stream("Generate a long story...")) {
process.stdout.write(chunk.content);
}
} catch (error) {
console.error("\n[Stream Error]", error.message);
}
```
---
## Web Application Integration
Streaming is essential for modern web apps. Here is a simple example using **Express**:
```ts
import express from "express";
import { NodeLLM } from "@node-llm/core";
const app = express();
app.get("/chat", async (req, res) => {
// Set headers for streaming text
res.setHeader("Content-Type", "text/plain; charset=utf-8");
res.setHeader("Transfer-Encoding", "chunked");
const chat = NodeLLM.chat("gpt-4o-mini");
try {
for await (const chunk of chat.stream(req.query.q as string)) {
if (chunk.content) {
res.write(chunk.content);
}
}
res.end();
} catch (error) {
res.write(`\nError: ${error.message}`);
res.end();
}
});
```
----------------------------------------
# 📄 core-features/structured_output.md
---
layout: default
title: Structured Output
parent: Core Features
nav_order: 3
description: Force models to return strictly validated JSON data using Zod schemas or manual JSON definitions across all supported providers.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Ensure the AI returns data exactly matching a specific structure. `NodeLLM` supports strict schema validation using **Zod** (recommended) or manual JSON schemas.
This feature abstracts the provider-specific implementations (like OpenAI's `json_schema`, Gemini's `responseJsonSchema`, or Anthropic's tool-use workarounds) into a single, unified API.
{: .highlight }
> **See it in action:** The [Brand Perception Checker](https://github.com/node-llm/node-llm/tree/main/examples/applications/brand-perception-checker) demonstrates utilizing rigorous Zod schemas to extract consistent semantic profiles across multiple providers simultaneously.
---
## Using Zod (Recommended)
The easiest way to define schemas is with Zod.
```ts
import { NodeLLM, z } from "@node-llm/core";
// Define a schema using Zod
const personSchema = z.object({
name: z.string().describe("Person's full name"),
age: z.number().describe("Person's age in years"),
hobbies: z.array(z.string()).describe("List of hobbies")
});
const chat = NodeLLM.chat("gpt-4o-mini");
// Use .withSchema() to enforce the structure
const response = await chat
.withSchema(personSchema)
.ask("Generate a person named Alice who likes hiking and coding");
// Streaming is also supported!
// for await (const chunk of chat.withSchema(personSchema).stream("...")) { ... }
// The response is strictly validated and parsed
const person = response.data;
console.log(person.name); // "Alice"
console.log(person.age); // e.g. 25
console.log(person.hobbies); // ["hiking", "coding"]
```
---
## Manual JSON Schemas
You can also provide a raw JSON schema object if you prefer not to use Zod.
**Note for OpenAI:** You must strictly follow OpenAI's requirements, such as setting `additionalProperties: false`.
```ts
const schema = {
type: "object",
properties: {
name: { type: "string" },
age: { type: "integer" }
},
required: ["name", "age"],
additionalProperties: false // Required for strict mode in OpenAI
};
const response = await chat.withSchema(schema).ask("Generate a person");
console.log(response.data); // { name: "...", age: ... }
```
---
## JSON Mode
If you just need valid JSON but don't want to enforce a rigid schema, you can enable JSON mode. This instructs the model to return valid JSON but gives it more freedom with the structure.
```ts
chat.withRequestOptions({
responseFormat: { type: "json_object" }
});
const response = await chat.ask("Generate a JSON object with a greeting");
console.log(response.data); // { greeting: "..." } or whatever keys it chose
```
---
## Provider Support
| Provider | Method Used | Notes |
| :------------ | :----------------------------------------- | :-------------------------------------------------------------------------------------------------------------- |
| **OpenAI** | `response_format: { type: "json_schema" }` | Fully supported with strict adherence. |
| **Gemini** | `responseJsonSchema` | Supported natively. |
| **Anthropic** | Tool Use (Mock) | `NodeLLM` automatically creates a tool definition and forces the model to use it to simulate structured output. |
---
## Nested Schemas
Complex nested schemas are fully supported via Zod.
```ts
const companySchema = z.object({
name: z.string(),
employees: z.array(
z.object({
name: z.string(),
role: z.enum(["developer", "designer", "manager"]),
skills: z.array(z.string())
})
),
metadata: z.object({
founded: z.number(),
industry: z.string()
})
});
const response = await chat.withSchema(companySchema).ask("Generate a small tech startup");
```
----------------------------------------
# 📄 core-features/testing.md
---
layout: default
title: Testing
parent: Core Features
nav_order: 10
permalink: /core-features/testing
description: Deterministic testing infrastructure for NodeLLM applications. VCR integration and fluent mocking for reliable AI systems.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
## Overview
Deterministic testing infrastructure for NodeLLM-powered AI systems. Built for engineers who prioritize **Boring Solutions**, **Security**, and **High-Fidelity Feedback Loops**.
> 💡 **What is High-Fidelity?**
> Your tests exercise the same execution path, provider behavior, and tool orchestration as production — without live network calls.
**Framework Support**: ✅ Vitest (native) | ✅ Jest (compatible via core APIs) | ✅ Any test framework
---
## The Philosophy: Two-Tier Testing
We believe AI testing should never be flaky or expensive. We provide two distinct strategies:
### 1. VCR (Integration Testing) 📼
**When to use**: To verify your system works with real LLM responses without paying for every test run.
- **High Fidelity**: Captures the **NodeLLM-normalized LLM execution** (model, prompt, tools, retries, and final output), ensuring replay remains stable even if provider APIs change.
- **Security First**: Automatically scrubs API Keys and sensitive PII from "cassettes".
- **CI Safe**: Fails-fast in CI if a cassette is missing, preventing accidental live API calls.
> 🚨 **CI Safety Guarantee**
> When `CI=true`, VCR **will never** record new cassettes.
> If a matching cassette is missing or mismatched, the test fails immediately.
### 2. Mocker (Unit Testing) 🎭
> ⚠️ **Note**
> The Mocker does **not** attempt to simulate model intelligence or reasoning.
> It deterministically simulates provider responses to validate application logic, error handling, and control flow.
**When to use**: To test application logic, edge cases (errors, rate limits), and rare tool-calling paths.
- **Declarative**: Fluent, explicit API to define expected prompts and responses.
- **Multimodal**: Native support for `chat`, `embed`, `paint`, `transcribe`, and `moderate`.
- **Streaming**: Simulate token-by-token delivery to test real-time UI logic.
---
## 📼 VCR Usage
### Basic Interaction
Wrap your tests in `withVCR` to automatically record interactions the first time they run.
```typescript
import { withVCR } from "@node-llm/testing";
it(
"calculates sentiment correctly",
withVCR(async () => {
const result = await mySentimentAgent.run("I love NodeLLM!");
expect(result.sentiment).toBe("positive");
})
);
```
### Hierarchical Organization (Convention-Based Mode) 📂
Organize your cassettes into nested subfolders to match your test suite structure.
```typescript
import { describeVCR, withVCR } from "@node-llm/testing";
describeVCR("Authentication", () => {
describeVCR("Login", () => {
it(
"logs in successfully",
withVCR(async () => {
// Cassette saved to: test/cassettes/authentication/login/logs-in-successfully.json
})
);
});
});
```
### Security & Scrubbing 🛡️
The VCR automatically redacts `api_key`, `authorization`, and other sensitive headers. You can add custom redaction:
```typescript
withVCR({
// Redact by key name
sensitiveKeys: ["user_ssn", "stripe_token"],
// Redact by value pattern (Regex)
sensitivePatterns: [/sk-test-[0-9a-zA-Z]+/g],
// Advanced: Custom function hook
scrub: (data) => data.replace(/SSN: \d+/g, "[REDACTED_SSN]")
}, async () => { ... });
```
### Global Configuration 🌍
Instead of repeating configuration in every test, set global defaults in your test setup file:
```typescript
import { configureVCR } from "@node-llm/testing";
configureVCR({
cassettesDir: "test/__cassettes__", // Configurable global path
sensitiveKeys: ["user_ssn", "stripe_token"],
sensitivePatterns: [/sk-test-[0-9a-zA-Z]+/g]
});
```
### Per-Test Overrides
You can still override defaults on a per-test basis:
```typescript
withVCR({
// Merged with global config
sensitiveKeys: ["specific_secret"]
}, async () => { ... });
```
---
## 🎭 Mocker Usage
### Fluent Mocking
Define lightning-fast, zero-network tests for your agents.
```typescript
import { mockLLM } from "@node-llm/testing";
const mocker = mockLLM();
// Exact match
mocker.chat("Ping").respond("Pong");
// Regex match
mocker.chat(/hello/i).respond("Greetings!");
// Simulate a Tool Call
mocker.chat("What's the weather?").callsTool("get_weather", { city: "London" });
```
### Streaming Mocks 🌊
Test your streaming logic by simulating token delivery.
```typescript
mocker.chat("Tell a story").stream(["Once ", "upon ", "a ", "time."]);
```
### Multimodal Mocks 🎨
```typescript
mocker.paint(/a cat/i).respond({ url: "https://mock.com/cat.png" });
mocker.embed("text").respond({ vectors: [[0.1, 0.2, 0.3]] });
```
### Call Verification & History 🕵️♀️
Inspect what requests were sent to your mock, enabling "spy" style assertions.
```typescript
// 1. Check full history
const history = mocker.history;
expect(history.length).toBe(1);
// 2. Filter by method
const chats = mocker.getCalls("chat");
expect(chats[0].args[0].messages[0].content).toContain("Hello");
// 3. Get the most recent call
const lastEmbed = mocker.getLastCall("embed");
expect(lastEmbed.args[0].input).toBe("text to embed");
// 4. Reset history (keep mocks)
mocker.resetHistory();
// 5. Snapshot your prompt structure
// Ensures your system prompts & tool definitions don't drift
expect(mocker.getLastCall().prompt).toMatchSnapshot();
```
---
## 🛣️ Decision Tree: VCR vs Mocker
Choose the right tool for your test:
```
Does your test need to verify behavior against REAL LLM responses?
├─ YES → Use VCR (integration testing)
│ ├─ Do you need to record the first time and replay afterward?
│ │ └─ YES → Use VCR in "record" or "auto" mode
│ ├─ Are you testing in CI/CD? (No live API calls allowed)
│ │ └─ YES → Set VCR_MODE=replay in CI
│ └─ Need custom scrubbing for sensitive data?
│ └─ YES → Use withVCR({ scrub: ... })
│
└─ NO → Use Mocker (unit testing)
├─ Testing error handling, edge cases, or rare paths?
│ └─ YES → Mock the error with mocker.chat(...).respond({ error: ... })
├─ Testing streaming token delivery?
│ └─ YES → Use mocker.chat(...).stream([...])
└─ Testing tool-calling paths without real tools?
└─ YES → Use mocker.chat(...).callsTool(name, params)
```
**Quick Reference**:
- **VCR**: Database queries, API calls, real provider behavior, network latency
- **Mocker**: Business logic, UI interactions, error scenarios, tool orchestration
### At-a-Glance Comparison
| Use Case | VCR | Mocker |
|----------|-----|--------|
| Real provider behavior | ✅ | ❌ |
| CI-safe (no live calls) | ✅ (after record) | ✅ |
| Zero network overhead | ❌ (first run) | ✅ |
| Error simulation | ⚠️ (record real) | ✅ |
| Tool orchestration | ✅ | ✅ |
| Streaming tokens | ✅ | ✅ |
---
## ⚙️ Configuration Contract
| Env Variable | Description | Default |
| ------------------ | ---------------------------------------------------------- | ---------------- |
| `VCR_MODE` | `record`, `replay`, `auto`, or `passthrough` | `auto` |
| `VCR_CASSETTE_DIR` | Base directory for cassettes | `test/cassettes` |
| `CI` | When true, VCR prevents recording and forces exact matches | (Auto-detected) |
---
## 🏛️ Integration with @node-llm/orm
The testing tools operate at the `providerRegistry` level. This means they **automatically** intercept LLM calls made by the ORM layer.
### Pattern: Testing Database Persistence
When using `@node-llm/orm`, you can verify both the database state and the LLM response in a single test.
```typescript
import { withVCR } from "@node-llm/testing";
import { createChat } from "@node-llm/orm/prisma";
it(
"saves the LLM response to the database",
withVCR(async () => {
// 1. Setup ORM Chat
const chat = await createChat(prisma, llm, { model: "gpt-4" });
// 2. Interaction (VCR intercepts the LLM call)
await chat.ask("Hello ORM!");
// 3. Verify DB state (standard Prisma/ORM assertions)
const messages = await prisma.assistantMessage.findMany({
where: { chatId: chat.id }
});
expect(messages).toHaveLength(2); // User + Assistant
expect(messages[1].content).toBeDefined();
})
);
```
### Pattern: Mocking Rare Logic
Use the `Mocker` to test how your application handles complex tool results or errors without setting up a real LLM.
```typescript
import { mockLLM } from "@node-llm/testing";
it("handles tool errors in ORM sessions", async () => {
const mocker = mockLLM();
mocker.chat("Search docs").respond({ error: new Error("DB Timeout") });
const chat = await loadChat(prisma, llm, "existing-id");
await expect(chat.ask("Search docs")).rejects.toThrow("DB Timeout");
});
```
---
## 🧪 Framework Integration
### Vitest (Native Support)
Vitest is the primary test framework with optimized helpers:
```typescript
import { it, describe } from "vitest";
import { mockLLM, withVCR, describeVCR } from "@node-llm/testing";
describeVCR("Payments", () => {
it(
"processes successfully",
withVCR(async () => {
// ✨ withVCR auto-detects test name ("processes successfully")
// ✨ describeVCR auto-manages scopes
})
);
});
```
### Jest Compatibility
All core APIs work with Jest. The only difference: `withVCR()` can't auto-detect test names, so provide it manually:
```typescript
import { describe, it } from "@jest/globals";
import { mockLLM, setupVCR, describeVCR } from "@node-llm/testing";
describeVCR("Payments", () => {
it("processes successfully", async () => {
// ✅ describeVCR works with Jest (framework-agnostic)
// ⚠️ withVCR doesn't work here (needs Vitest's expect.getState())
// ✅ Use setupVCR instead:
const vcr = setupVCR("processes", { mode: "record" });
const mocker = mockLLM(); // ✅ works with Jest
mocker.chat("pay").respond("done");
// Test logic here
await vcr.stop();
});
});
```
### Framework Support Matrix
| API | Vitest | Jest | Any Framework |
|-----|--------|------|---------------|
| `mockLLM()` | ✅ | ✅ | ✅ |
| `describeVCR()` | ✅ | ✅ | ✅ |
| `setupVCR()` | ✅ | ✅ | ✅ |
| `withVCR()` | ✅ (auto name) | ⚠️ (manual name) | ⚠️ (manual name) |
| Mocker class | ✅ | ✅ | ✅ |
| VCR class | ✅ | ✅ | ✅ |
**Only `withVCR()` is Vitest-specific** because it auto-detects test names. All other APIs are framework-agnostic.
### Any Test Framework
Using raw classes for maximum portability:
```typescript
import { Mocker, VCR } from "@node-llm/testing";
// Mocker - works everywhere
const mocker = new Mocker();
mocker.chat("hello").respond("hi");
// VCR - works everywhere
const vcr = new VCR("test-name", { mode: "record" });
// ... run test ...
await vcr.stop();
```
---
## 🚨 Common Error Scenarios
### VCR: Missing Cassette
**Error**: `Error: Cassette file not found`
**Cause**: VCR is in `replay` mode but the cassette doesn't exist yet.
**Solution**:
```bash
# Record it first
VCR_MODE=record npm test
# Or use auto mode (records if missing, replays if exists)
VCR_MODE=auto npm test
```
### VCR: Cassette Mismatch
**Error**: `AssertionError: No interaction matched the request`
**Cause**: Your code is making a request that doesn't match any recorded interaction.
**Solution**:
```bash
# Re-record the cassette
rm -rf test/cassettes/your-test
VCR_MODE=record npm test -- your-test
```
### Mocker: Strict Mode Violation
**Error**: `Error: No mock defined for prompt: "unexpected question"`
**Cause**: Your code asked a question you didn't mock in strict mode.
**Solution**:
```typescript
// Add the missing mock
mocker.chat("unexpected question").respond("mocked response");
// Or disable strict mode
const mocker = mockLLM({ strict: false });
```
### Mocker: Debug Information
Get insight into what mocks are registered:
```typescript
const mocker = mockLLM();
mocker.chat("hello").respond("hi");
mocker.embed("text").respond({ vectors: [[0.1, 0.2]] });
const debug = mocker.getDebugInfo();
console.log(debug);
// Output: { totalMocks: 2, methods: ["chat", "embed"] }
```
---
## 🎯 Advanced Patterns
### Pattern: Parametrized Testing with VCR
Test the same logic against multiple scenarios by organizing cassettes hierarchically:
```typescript
describeVCR("Payment Processing", () => {
["visa", "mastercard", "amex"].forEach((cardType) => {
describeVCR(cardType, () => {
it(
"processes payment",
withVCR(async () => {
const result = await processor.pay({
amount: 100,
cardType
});
expect(result.status).toBe("success");
})
);
});
});
});
// Cassettes created at:
// test/cassettes/payment-processing/visa/processes-payment.json
// test/cassettes/payment-processing/mastercard/processes-payment.json
// test/cassettes/payment-processing/amex/processes-payment.json
```
### Pattern: Strict Mode for Safety
Enforce that every expected interaction is mocked:
```typescript
describe("Customer Service Bot", () => {
it("responds to greeting", async () => {
const mocker = mockLLM({ strict: true });
mocker.chat("hello").respond("Hello! How can I help?");
await bot.handle("hello");
// Pass ✅
});
it("fails if unmocked", async () => {
const mocker = mockLLM({ strict: true });
mocker.chat("hello").respond("Hello!");
// This throws because "goodbye" wasn't mocked
await expect(bot.handle("goodbye")).rejects.toThrow();
});
});
```
### Pattern: Testing Streaming
Simulate token delivery to verify UI updates correctly:
```typescript
it("displays tokens as they arrive", async () => {
const mocker = mockLLM();
mocker.chat("Write a poem").stream([
"Roses ",
"are ",
"red\n",
"Violets ",
"are ",
"blue"
]);
const tokens: string[] = [];
const chat = NodeLLM.chat("gpt-4");
for await (const chunk of chat.stream("Write a poem")) {
tokens.push(chunk.content || "");
}
expect(tokens).toEqual([
"Roses ",
"are ",
"red\n",
"Violets ",
"are ",
"blue"
]);
});
```
---
## 🏛️ Architecture Contract
- **No Side Effects**: Mocks and VCR interceptors are automatically cleared after each test turn.
- **Deterministic**: The same input MUST always yield the same output in Replay mode.
- **Explicit > Implicit**: We prefer explicit mock definitions over complex global state.
---
## 🛑 When Not to Use @node-llm/testing
- Do not use **VCR** for rapid prompt iteration — use live calls instead.
- Do not use **Mocker** to validate response quality or correctness.
- Do not commit **cassettes** for experimental or throwaway prompts.
----------------------------------------
# 📄 core-features/tools.md
---
layout: default
title: Tool Calling
nav_order: 5
parent: Core Features
permalink: /core-features/tools
description: Give your models the ability to interact with the real world using a clean class-based DSL, automatic execution loops, and built-in safety guards.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
`NodeLLM` simplifies function calling (tool use) by handling the execution loop automatically. You define the tools, and the library invokes them when the model requests it.
```bash
npm install @node-llm/core
```
{: .highlight }
> **Looking for a real-world example?** Check out the [Brand Perception Checker](https://github.com/node-llm/node-llm/tree/main/examples/applications/brand-perception-checker), which uses the `SerpTool` to perform live Google searches and "read" the results to extract semantic signals.
---
## Class-Based Tools New ✨
The recommended way to define tools is by using the `Tool` class. This provides auto-generated JSON schemas and full type safety using `zod`.
```ts
import { NodeLLM, Tool, z } from "@node-llm/core";
class WeatherTool extends Tool {
name = "get_weather";
description = "Get the current weather for a location";
// Auto-generates JSON Schema
schema = z.object({
location: z.string().describe("The city and state, e.g. San Francisco, CA"),
unit: z.enum(["celsius", "fahrenheit"]).default("celsius")
});
async execute({ location, unit }) {
// Your business logic
const weather = await fetchWeather(location);
return { temp: 22, unit, condition: "Sunny" };
}
}
// Register as a class (instantiated automatically) or instance
const chat = llm.chat().withTool(WeatherTool);
await chat.ask("What is the weather in SF?");
```
### Benefits
- **No Boilerplate**: No need to write manual JSON schemas.
- **Type Safety**: `execute()` arguments are automatically typed from your schema.
- **Self-Documenting**: The Zod `.describe()` calls are automatically pulled into the tool's description for the LLM.
### Defining Parameters with Zod
`NodeLLM` uses `zod-to-json-schema` under the hood. Most standard Zod types work out of the box:
| Zod Type | Description |
| :-------------------- | :-------------------------------------------------- |
| **All Fields** | **Required by default**. |
| `z.string()` | Basic text string. |
| `z.number()` | Number (integer or float). |
| `z.boolean()` | Boolean flag. |
| `z.enum(["a", "b"])` | String restricted to specific values. |
| `z.object({...})` | Nested object. |
| `z.array(z.string())` | Array of items. |
| `.describe("...")` | **Crucial**: Adds a description for the LLM. |
| `.optional()` | Marks the field as not required. |
| `.default(val)` | Sets a default value if the LLM doesn't provide it. |
---
## Using Tools in Chat
Use the fluent `.withTool()` or `.withTools()` API to register tools for a chat session. By default, tools are appended. You can use the `replace` option to clear previous tools.
```ts
// Append tools
const chat = llm.chat("gpt-4o").withTools([WeatherTool, CalculatorTool]);
// Replace all existing tools with a new list
chat.withTools([SearchTool], { replace: true });
const reply = await chat.ask("What is the weather in London?");
```
---
## Tools Work in Streaming Too! New ✨
Tools now work seamlessly with streaming! The same tool execution happens automatically during streaming:
```ts
const chat = llm.chat("gpt-4o").withTool(WeatherTool);
// Tool is automatically executed during streaming
for await (const chunk of chat.stream("What's the weather in Paris?")) {
process.stdout.write(chunk.content || "");
}
```
See the [Streaming documentation](streaming.html#streaming-with-tools-) for more details.
---
## Parallel Tool Calling
If the provider supports it (like OpenAI and Anthropic), the model can call multiple tools in a single turn. `NodeLLM` handles the concurrent execution of these tools automatically.
See [examples/scripts/openai/chat/parallel-tools.mjs](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/parallel-tools.mjs) for a demo.
---
## Loop Protection (Loop Guard) 🛡️
To prevent infinite recursion and runaway costs (where a model keeps calling tools without reaching a conclusion), `NodeLLM` includes a built-in Loop Guard.
By default, `NodeLLM` will throw an error if a model performs more than **5 sequential tool execution turns** in a single request.
### Customizing the Limit
You can configure this limit globally or override it for a specific request:
```ts
// 1. Global Change
const llm = createLLM({ maxToolCalls: 10 });
await chat.ask("Perform a complex deep research task", {
maxToolCalls: 15
});
```
---
## Tool Execution Policies (Security) v1.5.0+
For sensitive operations, you can control the "autonomy" of the tool execution loop using `withToolExecution()`.
- **`auto`**: (Default) Tools are executed immediately as proposed by the LLM.
- **`confirm`**: Enables **Human-in-the-loop**. NodeLLM pauses before execution and awaits approval via the `onConfirmToolCall` hook.
- **`dry-run`**: Proposes the tool call structure but **never executes it**. Useful for UI previews or verification-only flows.
```ts
chat.withToolExecution("confirm").onConfirmToolCall(async (call) => {
// Audit the call or ask the user
console.log(`LLM wants to call ${call.function.name}`);
return true; // Return true to execute, false to cancel
});
```
### Inspected Proposals
In `confirm` and `dry-run` modes, the `ChatResponseString` object returned by `.ask()` includes a `.tool_calls` property. This allows you to inspect exactly what the model _wanted_ to do.
```ts
const res = await chat.withToolExecution("dry-run").ask("Delete all users");
console.log(res.tool_calls); // [{ id: '...', function: { name: 'delete_users', ... } }]
```
---
## Advanced Tool Metadata
Some providers support additional metadata in tool definitions, such as Anthropic's **Prompt Caching**. You can include these fields in your tool class, and `NodeLLM` will pass them through.
```ts
class HistoryTool extends Tool {
name = "get_history";
description = "Get chat history";
schema = z.object({ limit: z.number().default(10) });
// Add provider-specific metadata
cache_control = { type: 'ephemeral' };
async execute({ limit }) {
return [...];
}
// Override toLLMTool to include custom metadata if needed
toLLMTool() {
const def = super.toLLMTool();
return {
...def,
cache_control: this.cache_control
};
}
}
```
---
## Error Handling & Flow Control v1.5.1+
`NodeLLM` handles tool errors intelligently to prevent infinite retry loops through a combination of automatic infrastructure protection and manual flow control.
### Zero-Config Safety (Fatal Errors)
By default, the agent loop will **immediately stop and throw** if it encounters an unrecoverable "fatal" error. This prevents wasting tokens on retries that are guaranteed to fail.
Fatal errors include:
- **Authentication Errors**: HTTP 401 or 403 errors from LLM providers or external APIs.
- **Explicit Fatal Errors**: Any error thrown using the `ToolError` class with `fatal: true`.
```ts
import { Tool, ToolError } from "@node-llm/core";
class DatabaseTool extends Tool {
async execute({ query }) {
if (isMalicious(query)) {
// Force the agent to stop immediately
throw new ToolError("Security Violation", "db_tool", true);
}
}
}
```
### Hook-Based Flow Control (STOP | CONTINUE)
For granular control, you can use the `onToolCallError` hook to override internal logic. This allows you to differentiate between tools that are "mission-critical" and those that are "optional."
The hook can return one of two directives:
- **`"STOP"`**: Force the agent to crash and bubble the error up to your code.
- **`"CONTINUE"`**: Catch the error, log it, and tell the agent to ignore it and move to the next turn.
```ts
const chat = llm.chat("gpt-4o", {
onToolCallError: (toolCall, error) => {
// 1. Critical Tool: Stop everything
if (toolCall.function.name === "process_payment") {
return "STOP";
}
// 2. Optional Tool: Just ignore if it fails
if (toolCall.function.name === "fetch_avatar") {
console.warn("Avatar fetch failed, but continuing...");
return "CONTINUE";
}
// 3. Default: Let NodeLLM decide (e.g. stop on 401/403)
}
});
```
### Recoverable Errors (AI Self-Correction)
If you want the model to see the error and try to fix its own parameters, simply return a string or object from your handler. NodeLLM will feed this back to the model as a successful tool result containing error details.
```ts
async execute({ date }) {
if (!isValid(date)) {
return { error: "Invalid date format. Please use YYYY-MM-DD." };
}
}
```
### ToolHalt — Early Loop Termination v1.11.0+
Sometimes a tool needs to stop the agentic loop immediately without making another LLM call. Use `this.halt()` to return a message directly to the user and break the loop.
```ts
import { Tool, z } from "@node-llm/core";
class PaymentTool extends Tool {
name = "process_payment";
description = "Process a payment";
schema = z.object({
amount: z.number().describe("Amount in dollars"),
recipient: z.string().describe("Recipient name")
});
async execute({ amount, recipient }) {
// Halt on large amounts — requires human approval
if (amount > 10000) {
return this.halt(`Payment of $${amount} to ${recipient} requires manager approval.`);
}
// Halt on invalid amounts
if (amount <= 0) {
return this.halt(`Invalid payment amount: $${amount}. Must be positive.`);
}
// Normal execution continues
return { success: true, transactionId: "TXN-123" };
}
}
```
**When to use `halt()`:**
- **Security boundaries**: Block dangerous operations (delete, privileged access)
- **Approval workflows**: Pause for human review on high-stakes actions
- **Validation failures**: Stop immediately on invalid input instead of retrying
- **Resource limits**: Halt when quotas or rate limits are exceeded
**Difference from throwing errors:**
- `throw new ToolError(...)` — Stops the loop and bubbles an exception
- `return this.halt(...)` — Stops the loop gracefully and returns the message as the final response
---
## Advanced: Raw JSON Schema
If you prefer to define your parameters using standard JSON Schema instead of Zod, you can pass a schema object directly to the `schema` property in your `Tool` class. This is useful for migrating existing tools or when you already have schema definitions.
```ts
class CustomTool extends Tool {
name = "custom_lookup";
description = "Lookup items in a legacy system";
// Use Raw JSON Schema instead of Zod
schema = {
type: "object",
properties: {
sku: { type: "string", description: "Product SKU" },
limit: { type: "integer", minimum: 1, maximum: 100 }
},
required: ["sku"]
};
async execute({ sku, limit }) {
// Arguments are still passed as a single object
return { status: "found" };
}
}
```
---
## Function-Based Tools (Legacy)
For simply wrapping a function without a class, you can define a tool as a plain object with a `handler`.
```ts
const weatherTool = {
type: "function",
function: {
name: "get_weather",
description: "Get the current weather for a location",
parameters: {
type: "object",
properties: {
location: { type: "string", description: "City and state" }
},
required: ["location"]
}
},
handler: async ({ location }) => {
return JSON.stringify({ location, temp: 22, unit: "celsius" });
}
};
chat.withTool(weatherTool);
```
---
## Security Considerations
Treat arguments passed to your `execute` method as **untrusted user input**.
- **Validate**: Always validate parameter types and ranges using libraries like `zod` inside the handler if critical.
- **Sanitize**: Sanitize strings before using them in database queries or shell commands.
- **Avoid Eval**: Never use `eval()` on inputs provided by the model.
---
## Debugging Tools
To see exactly what the model is calling and what your tool is returning, enable debug mode:
```bash
export NODELLM_DEBUG=true
```
You will see logs like:
`[NodeLLM] Tool call: get_weather { location: "Paris" }`
`[NodeLLM] Tool result: { temp: 15 }`
----------------------------------------
# 📄 providers/anthropic.md
---
layout: default
title: Anthropic
parent: Providers
nav_order: 3
description: Experience the Claude family of models with native support for PDF document analysis, advanced reasoning, and long-context capabilities.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The Anthropic provider gives access to the Claude family of models, known for high-quality reasoning and coding capabilities.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "anthropic",
anthropicApiKey: process.env.ANTHROPIC_API_KEY // Optional if set in env
});
```
---
## Specific Parameters
You can pass Anthropic-specific parameters or custom headers.
```ts
const chat = llm.chat("claude-3-5-sonnet-20241022").withParams({
top_k: 50,
top_p: 0.9,
// Custom headers if needed
headers: {
"anthropic-beta": "max-tokens-3-5-sonnet-2024-07-15"
}
});
```
---
## Features
- **Models**: `claude-3-7-sonnet`, `claude-3-5-sonnet`, `claude-3-opus`, `claude-3-haiku`.
- **Vision**: Analyzes images.
- **PDF Support**: Can read and analyze PDF documents natively.
- **Tools**: Fully supported.
- **Reasoning**: Support for Extended Thinking and token-based pricing for `claude-3-7`.
---
## PDF Support
Anthropic supports sending PDF files as base64 encoded blocks, which `NodeLLM` handles automatically.
```ts
await chat.ask("Summarize this document", {
files: ["./report.pdf"]
});
```
---
## Getting an API Key
Sign up and get your API key at [console.anthropic.com](https://console.anthropic.com).
----------------------------------------
# 📄 providers/bedrock.md
---
layout: default
title: Amazon Bedrock
parent: Providers
nav_order: 7
description: Access models from Amazon Titan, Anthropic, Meta, and Stability AI through a secure, zero-dependency AWS implementation.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The Amazon Bedrock provider uses a **zero-dependency** implementation of the AWS SigV4 signing process. This means you do **not** need to install the heavy `@aws-sdk/client-bedrock-runtime` package. NodeLLM handles all authentication and request signing natively.
---
## Configuration
NodeLLM automatically attempts to load AWS credentials from standard environment variables matching the AWS CLI.
### 1. Environment Variables (Recommended)
```bash
export AWS_ACCESS_KEY_ID="AKIA..."
export AWS_SECRET_ACCESS_KEY="wJalrX..."
export AWS_REGION="us-east-1"
# Optional session token for temporary credentials
export AWS_SESSION_TOKEN="..."
```
### 2. Manual Configuration
You can also pass credentials explicitly when initializing the LLM.
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "bedrock",
bedrockRegion: "us-east-1",
bedrockAccessKeyId: "AKIA...",
bedrockSecretAccessKey: "..."
});
```
---
## Features
- **Models**: Access to `amazon.titan`, `anthropic.claude`, `meta.llama3`, `mistral`, `cohere`, and `amazon.nova`.
- **Cross-Region Inference**: Natively supports inference profiles (e.g., `us.anthropic.claude-3-5-sonnet...`) for higher throughput.
- **Image Generation**: First-class support for **Titan Image Generator** and **Stable Diffusion**.
- **Prompt Caching**: Save up to 90% on costs with Claude and Nova models.
- **Multimodal**: Send images to Claude and Nova models easily.
- **Extended Thinking (Reasoning)**: Native support for Claude 3.7 and DeepSeek R1 thinking budgets.
- **Guardrail Visibility**: Access raw Guardrail trace assessments via response metadata.
---
## Image Generation
Use the `paint()` method to generate images using Bedrock's specialized models.
```ts
const response = await llm.paint("A futuristic city on Mars, high quality, 4k", {
model: "amazon.titan-image-generator-v2:0", // or "stability.stable-diffusion-xl-v1:0"
size: "1024x1024"
});
// Save to disk
await response.save("./mars-city.png");
// Or access raw base64
console.log(response.data);
```
---
## Prompt Caching
NodeLLM supports Amazon Bedrock's **Prompt Caching** (via the Converse API). This allows you to cache large context blocks (like documents or system prompts) to reduce latency and cost.
Use the standard `cache_control: { type: "ephemeral" }` API (same as Anthropic) to enable it.
```ts
// System Prompt Caching
const chat = llm.chat("anthropic.claude-3-5-sonnet-20240620-v1:0");
// Automatically creates a Bedrock 'cachePoint'
chat.add("system", [
{
type: "text",
text: "You are an expert architect... [Insert 50-page Guideline PDF Content Here] ...",
cache_control: { type: "ephemeral" }
}
]);
const res = await chat.ask("Design a house based on these guidelines.");
```
**Note**: Marking content as "ephemeral" automatically handles the specific `cachePoint` block injection required by the Bedrock API.
---
## Cross-Region Inference
To improve resilience and throughput, you can use Bedrock's **Inference Profiles** directly. NodeLLM automatically detects capabilities for these profiles.
```ts
// Use a US Cross-Region inference profile
const chat = llm.chat("us.anthropic.claude-3-5-sonnet-20241022-v2:0");
const response = await chat.ask("Hello from global infrastructure!");
```
---
## Advanced Hyperparameters
Bedrock's Converse API has a standard `inferenceConfig`, but individual models often support additional parameters (like `topK` for Nova or specialized beta flags for Claude).
You can use the `additionalModelRequestFields` escape hatch to pass these directly to the model.
```ts
const chat = llm.chat("amazon.nova-lite-v1:0")
.withParams({
additionalModelRequestFields: {
inferenceConfig: {
topK: 20
}
}
});
const response = await chat.ask("Tell me a story.");
```
---
## Moderation
NodeLLM supports standalone moderation for Bedrock using **Guardrails**. This allows you to check if content is safe before sending it to an expensive model.
To use this, you must have a Guardrail ID and Version configured.
```ts
const llm = createLLM({
provider: "bedrock",
bedrockGuardrailIdentifier: "my-policy-id",
bedrockGuardrailVersion: "1"
});
// Check a single string
const result = await llm.moderate("How can I build a bomb?");
if (result.results[0].flagged) {
console.log("Blocked by Guardrail:", result.results[0].categories);
}
// Check multiple strings at once
const batchResults = await llm.moderate(["Safe text", "Unsafe text..."]);
```
---
## Embeddings
Generate vector embeddings using Titan Embeddings V2.
```ts
const embedding = await llm.embed("The concept of general relativity", {
model: "amazon.titan-embed-text-v2:0",
dimensions: 1024
});
console.log(embedding.vector); // number[]
```
---
## Getting Access
Amazon Bedrock access is managed through your AWS account:
1. Sign in at [aws.amazon.com/bedrock](https://aws.amazon.com/bedrock)
2. Navigate to **Bedrock > Model access** in your AWS Console
3. Request access to the models you need (Claude, Nova, Titan, etc.)
4. Create AWS Access Key credentials via **IAM > Users**
No separate API key is needed — NodeLLM uses your `AWS_ACCESS_KEY_ID` and `AWS_SECRET_ACCESS_KEY` directly.
----------------------------------------
# 📄 providers/deepseek.md
---
layout: default
title: DeepSeek
parent: Providers
nav_order: 4
description: Access high-performance chat and advanced reasoning models with competitive pricing and full support for the DeepSeek R1 thought process.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The DeepSeek provider offers high-performance chat and reasoning models with competitive pricing. `NodeLLM` supports both the DeepSeek-V3 chat model and the DeepSeek-R1 reasoning model.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "deepseek",
deepseekApiKey: process.env.DEEPSEEK_API_KEY // Optional if set in env
});
```
---
## Specific Parameters
You can pass DeepSeek-specific parameters using `.withParams()`.
```ts
const chat = llm.chat("deepseek-chat").withParams({
presence_penalty: 0.5,
frequency_penalty: 0.5,
top_p: 0.9
});
```
---
## Features
- **Models**:
- `deepseek-chat`: Optimized for speed and proficiency in broad tasks (DeepSeek-V3).
- `deepseek-reasoner`: Optimized for complex reasoning and problem solving (DeepSeek-R1).
- **Tools**: Supported on `deepseek-chat`.
- **Reasoning**: Access inner thought process text from `deepseek-reasoner`.
- **Streaming**: Full streaming support for all models.
- **Structured Output**: Supported via automated prompt engineering and `json_object` mode transitions.
---
## Usage Details
DeepSeek provides OpenAI-compatible endpoints, but `NodeLLM` handles the specific capability differences (like reasoning vs tool support) automatically through its internal registry.
---
## Getting an API Key
Sign up and get your API key at [platform.deepseek.com](https://platform.deepseek.com).
----------------------------------------
# 📄 providers/gemini.md
---
layout: default
title: Gemini
parent: Providers
nav_order: 2
description: Leverage Google's powerful multimodal capabilities with native support for image, audio, and video processing alongside long-context reasoning.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Google's Gemini provider offers multimodal capabilities including native video and audio understanding.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "gemini",
geminiApiKey: process.env.GEMINI_API_KEY // Optional if set in env
});
```
---
## Specific Parameters
Gemini uses `generationConfig` and `safetySettings`.
```ts
const chat = llm.chat("gemini-1.5-pro").withParams({
generationConfig: {
topP: 0.8,
topK: 40,
maxOutputTokens: 8192
},
safetySettings: [
{
category: "HARM_CATEGORY_HARASSMENT",
threshold: "BLOCK_LOW_AND_ABOVE"
}
]
});
```
---
## Features
- **Models**: `gemini-1.5-pro`, `gemini-1.5-flash`, `gemini-2.0-flash`.
- **Multimodal**: Supports images, audio, and video files directly.
- **Tools**: Supported.
- **System Instructions**: Supported.
---
## Video Support
Gemini is unique in its ability to natively process video files.
```ts
await chat.ask("What happens in this video?", {
files: ["./video.mp4"]
});
```
---
## Getting an API Key
Sign up and get your API key at [aistudio.google.com/apikey](https://aistudio.google.com/apikey).
----------------------------------------
# 📄 providers/index.md
---
layout: default
title: Providers
nav_order: 5
has_children: true
nav_fold: false
permalink: /providers
description: Detailed guides for every supported AI provider, including specific features and authentication configurations.
back_to_top: false
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
----------------------------------------
# 📄 providers/mistral.md
---
layout: default
title: Mistral AI
parent: Providers
nav_order: 10
description: Access Mistral AI's powerful language models including Mistral Large, Mistral Small, Codestral, and Pixtral for vision tasks.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The Mistral provider offers access to Mistral AI's range of language models, from efficient small models to powerful large models with vision and code capabilities.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "mistral",
mistralApiKey: process.env.MISTRAL_API_KEY // Optional if set in env
});
```
---
## Specific Parameters
You can pass Mistral-specific parameters using `.withParams()`.
```ts
const chat = llm.chat("mistral-large-latest").withParams({
temperature: 0.7,
top_p: 0.9,
safe_prompt: true
});
```
---
## Features
- **Models**:
- `mistral-large-latest`: Most capable model for complex tasks.
- `mistral-medium-latest`: Balanced performance and efficiency.
- `mistral-small-latest`: Fast and cost-effective for simpler tasks.
- `codestral-latest`: Optimized for code generation and understanding.
- `pixtral-large-latest`: Vision-capable multimodal model.
- `mistral-embed`: Text embedding model for semantic search.
- **Tools**: Supported on all chat models.
- **Vision**: Supported via `pixtral-large-latest` model.
- **Streaming**: Full streaming support for all chat models.
- **Structured Output**: Supported via JSON schema definitions.
- **Embeddings**: Supported via `mistral-embed` model.
---
## Vision Example
```ts
import { createLLM, Content } from "@node-llm/core";
const llm = createLLM({ provider: "mistral" });
const response = await llm
.chat("pixtral-large-latest")
.say(Content.text("What's in this image?").image("https://example.com/photo.jpg"))
.then((r) => r.text);
```
---
## Embeddings Example
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({ provider: "mistral" });
const result = await llm.embed("mistral-embed", "Hello world");
console.log(result.vectors[0]); // [0.123, -0.456, ...]
```
---
## Getting an API Key
Sign up and get your API key at [console.mistral.ai](https://console.mistral.ai).
----------------------------------------
# 📄 providers/ollama.md
---
layout: default
title: Ollama
parent: Providers
nav_order: 5
description: Run Large Language Models locally on your machine with full support for vision, tools, and embeddings while maintaining total data sovereignty.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Allows you to run large language models locally using [Ollama](https://ollama.com/).
---
## Configuration
Standard configuration for local inference (defaults to `http://localhost:11434/v1`):
```javascript
import { createLLM } from "@node-llm/core";
// Defaults to http://localhost:11434/v1
const llm = createLLM({ provider: "ollama" });
```
### Custom URL
If your Ollama instance is running on a different machine or port:
```javascript
const llm = createLLM({
provider: "ollama",
ollamaApiBase: "http://192.168.1.10:11434/v1" // Note the /v1 suffix
});
```
---
## Specific Parameters
You can pass Ollama/OpenAI-compatible parameters using `.withParams()`.
```javascript
const chat = llm.chat("llama3").withParams({
temperature: 0.7,
seed: 42,
num_ctx: 8192 // Ollama specific context size
});
```
---
## Features
- **Models**: Supports any model pulled via `ollama pull`.
- **Vision**: Use vision-capable models like `llama3.2-vision` or `llava`.
- **Tools**: Fully supported for models with tool-calling capabilities (e.g., `llama3.1`).
- **Embeddings**: High-performance local vector generation.
- **Model Discovery**: Inspect your local library and model metadata via `llm.listModels()`.
### Multimodal (Vision)
```javascript
const response = await chat.ask("Describe this image", {
files: ["./image.png"]
});
```
### Model Discovery
List all models currently pulled in your Ollama library to inspect their context windows and features:
```javascript
const models = await NodeLLM.listModels();
console.table(models);
```
---
## Limitations
The following features are **not** supported natively by Ollama's OpenAI-compatible API:
- **Transcription** (Whisper): Not available via the `/v1/audio` endpoint.
- **Image Generation**: Not available via the `/v1/images` endpoint.
- **Moderation**: Not supported.
For full feature parity locally, consider using [LocalAI](https://localai.io/) and connecting via the [OpenAI Provider](/providers/openai.html) with a custom `openaiApiBase`.
---
## Getting Started
Ollama is free and runs entirely on your machine — no API key required.
Download and install it from [ollama.com](https://ollama.com), then pull a model:
```bash
ollama pull llama3
ollama pull llama3.2-vision # for vision support
```
----------------------------------------
# 📄 providers/openai.md
---
layout: default
title: OpenAI
parent: Providers
nav_order: 1
description: Full support for the complete range of NodeLLM features including tool calling, vision, image generation, and the advanced Developer role.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The OpenAI provider supports the full range of `NodeLLM` features, including robust tool calling, vision, and structured outputs.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "openai",
openaiApiKey: process.env.OPENAI_API_KEY // Optional if set in env
});
```
---
## Specific Parameters
You can pass OpenAI-specific parameters using `.withParams()`.
```ts
const chat = llm.chat("gpt-4o").withParams({
seed: 42, // for deterministic output
user: "user-123", // for user tracking
presence_penalty: 0.5,
frequency_penalty: 0.5
});
```
---
## Features
- **Models**: `gpt-4o`, `gpt-4o-mini`, `gpt-4-turbo`, etc.
- **Vision**: Specific models like `gpt-4o` support image analysis.
- **Tools**: Fully supported, including parallel tool execution.
- **Reasoning**: Automatic tracking of reasoning tokens and costs for `o1` and `o3` models.
- **Smart Developer Role**: Modern instructions are automatically mapped to the `developer` role for compatible models when using the official API.
- **Structured Output**: Supports strict schema validation via `json_schema`.
---
## Custom Endpoints
OpenAI's client is also used for compatible services like Ollama, LocalAI, and Azure OpenAI. See [Custom Endpoints](/advanced/custom_endpoints.html) for details.
---
## Getting an API Key
Sign up and get your API key at [platform.openai.com/api-keys](https://platform.openai.com/api-keys).
----------------------------------------
# 📄 providers/openrouter.md
---
layout: default
title: OpenRouter
parent: Providers
nav_order: 5
description: Access hundreds of open-source and proprietary models through a single gateway with unified tool calling, vision, and reasoning support.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The OpenRouter provider acts as a unified gateway to AI models from multiple providers. `NodeLLM` leverages OpenRouter's standardized API while providing additional capabilities like integrated tool calling and vision.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "openrouter",
openrouterApiKey: process.env.OPENROUTER_API_KEY
});
```
---
## Features
- **Model Discovery**: Full support for `llm.listModels()` to explore available models.
- **Unified API**: Switch between models from OpenAI, Anthropic, Google, and Meta using a single configuration.
- **Vision**: Supported for multimodal models.
- **Tools**: Supported for models with function calling capabilities.
- **Reasoning**: Access chain-of-thought for reasoning-capable models (e.g., DeepSeek R1).
- **Streaming**: Native streaming support with the advanced `Stream` utility.
---
## Specific Parameters
OpenRouter supports various unique parameters that can be passed via `.withParams()`:
```ts
const chat = llm.chat("google/gemini-2.0-flash-exp:free").withParams({
transforms: ["middle-out"], // OpenRouter specific compression
route: "fallback"
});
```
---
## Getting an API Key
Sign up and get your API key at [openrouter.ai/keys](https://openrouter.ai/keys).
----------------------------------------
# 📄 providers/xai.md
---
layout: default
title: xAI (Grok)
parent: Providers
nav_order: 8
description: Native support for xAI's Grok models including chat, streaming, vision, structured output, reasoning, and image generation.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
The xAI provider gives you access to the Grok family of models through a clean, NodeLLM-native interface. It supports all core NodeLLM features including streaming, vision, structured outputs, reasoning, and image generation.
---
## Configuration
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({
provider: "xai",
xaiApiKey: process.env.XAI_API_KEY
});
```
Or via environment variables:
```env
NODELLM_PROVIDER=xai
XAI_API_KEY=xai-...
```
Then use zero-config:
```ts
import { NodeLLM } from "@node-llm/core";
const chat = NodeLLM.chat("grok-3");
```
---
## Available Models
| Model | Features |
| :--------------------- | :---------------------------------------------- |
| `grok-3` | Chat, Streaming, Tools, Structured Output |
| `grok-3-mini` | Chat, Streaming, Tools, **Reasoning** |
| `grok-2-1212` | Chat, Streaming, Tools, Structured Output |
| `grok-2-vision-1212` | Chat, Streaming, **Vision**, Structured Output |
| `grok-imagine-image` | **Image Generation** |
For the full list, run:
```ts
const models = await llm.listModels();
```
---
## Features
### 💬 Chat
```ts
const chat = llm.chat("grok-3");
const response = await chat.ask("Explain event-driven architecture.");
console.log(response.content);
```
### ⚡ Streaming
```ts
for await (const chunk of chat.stream("Tell me about Node.js")) {
process.stdout.write(chunk.content || "");
}
```
### 👁️ Vision
Use `grok-2-vision-1212` to analyze images by passing mixed content arrays:
```ts
const chat = llm.chat("grok-2-vision-1212");
const response = await chat.ask([
{ type: "text", text: "What is in this image?" },
{ type: "image_url", image_url: { url: "https://example.com/image.jpg" } }
]);
```
### ✨ Structured Output
```ts
import { z } from "@node-llm/core";
const Schema = z.object({
name: z.string(),
age: z.number(),
hobbies: z.array(z.string())
});
const response = await chat.withSchema(Schema).ask("Create a fictional user profile.");
console.log(response.parsed); // Fully typed
```
### 🧠 Reasoning
`grok-3-mini` is a reasoning model. Reasoning tokens are tracked automatically.
```ts
const chat = llm.chat("grok-3-mini");
const response = await chat.ask("Solve this logic puzzle: ...");
console.log(response.content); // Final answer
console.log(response.usage); // Includes reasoning_tokens
```
### 🎨 Image Generation
```ts
const response = await llm.paint("A futuristic city at night, cyberpunk style", {
model: "grok-imagine-image"
});
console.log(response.url); // URL of generated image
```
### 🛠️ Tool Calling
```ts
import { Tool, z } from "@node-llm/core";
class WeatherTool extends Tool {
name = "get_weather";
description = "Get the current weather for a city";
schema = z.object({ city: z.string() });
async execute({ city }) {
return `Sunny in ${city}`;
}
}
const response = await chat.withTool(WeatherTool).ask("What's the weather in London?");
```
---
## Supported Features Summary
| Feature | Supported |
| :-------------------- | :-------: |
| Chat | ✅ |
| Streaming | ✅ |
| Tool Calling | ✅ |
| Structured Output | ✅ |
| Vision | ✅ |
| Image Generation | ✅ |
| Reasoning | ✅ |
| Embeddings | ❌ |
| Transcription | ❌ |
| Moderation | ❌ |
---
## Getting an API Key
Sign up and get your API key at [console.x.ai](https://console.x.ai).
----------------------------------------
# 📄 orm/index.md
---
layout: default
title: ORM & Persistence
nav_order: 4
has_children: true
permalink: /orm
description: Database persistence layer for NodeLLM. Automatically track chats, messages, tool calls, and API metrics.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
---
## Quick Setup
NodeLLM ORM provides a robust persistence layer that bridges the gap between your application database and LLM providers. It ensures that every turn in a conversation is safely stored, while maintaining high performance for real-time streaming.
Currently, we support **Prisma** with a dedicated adapter.
### installation
```bash
npm install @node-llm/orm @node-llm/core @prisma/client
```
---
## Strategic Design
The ORM is designed to be an **infrastructure-first** layer, much like the core package. It doesn't just store text; it captures the entire execution lifecycle, including:
- **Token Consumption**: Track input/output/thinking tokens per message and per request.
- **Reasoning & Thinking Process**: Capture internal chain-of-thought text and cryptographic signatures for modern reasoning models.
- **Tool Audit Trail**: Record every tool call, its parameters, thought process, and result.
- **Provider status**: Know exactly which model and provider served which message.
- **Request Metadata**: Log latency, status codes, and cost for every API interaction.
[Explore the Prisma Adapter](/orm/prisma.html){: .btn .btn-primary .fs-5 .mb-4 .mb-md-0 .mr-2 }
----------------------------------------
# 📄 orm/migrations.md
# Database Migration Guide
Maintaining a production-grade database requires moving away from `npx prisma db push` (which can cause data loss) to **Prisma Migrate** (which tracks incremental changes via SQL files).
This guide explains how to manage schema updates professionally, translating Rails-style migration discipline into the Node.js / Prisma ecosystem.
**Added in v0.2.0**
{: .label .label-green }
---
## The Migration Workflow
NodeLLM's ORM schema will evolve over time (e.g., adding "Extended Thinking" support). To update your application without losing user chat history, follow this workflow.
### 1. Detect Changes (CLI)
The easiest way to check if your existing database is missing columns for new NodeLLM features is to use the **ORM CLI Sync**:
```bash
npx @node-llm/orm sync
```
**What this does:**
- Scans your `prisma/schema.prisma`.
- Identifies missing fields (like `thinkingText` or `thoughtSignature`).
- Provides guidance on the specific columns to add.
### 2. Update the Schema manually
Modify your `prisma/schema.prisma` with the new fields or models (or copy the latest version from `@node-llm/orm/schema.prisma`).
### 3. Generate a Migration
Instead of pushing directly to the DB, generate a versioned migration file:
```bash
npx prisma migrate dev --name add_thinking_support
```
**What this does:**
- Detects the difference between your `schema.prisma` and your actual database.
- Creates a new folder in `prisma/migrations/` containing a `migration.sql` file.
- Applies that SQL to your local database.
### 3. Commit the Migration
**Crucial**: Always commit the `prisma/migrations` folder to your version control. This ensures all environments (staging, production) apply the exact same SQL changes.
---
## Baseline: Moving from `db push` to `migrate`
If you have been using `db push` and now want to start using formal migrations without losing data:
1. **Clear Drift**: Ensure your database and schema are currently in sync via one last `db push`.
2. **Baseline**: Initialize the migration history by marking the current state as the "initial" version:
```bash
mkdir -p prisma/migrations/0_init
npx prisma migrate diff \
--from-empty \
--to-schema-datamodel prisma/schema.prisma \
--script > prisma/migrations/0_init/migration.sql
npx prisma migrate resolve --applied 0_init
```
---
## Deployment to Production
In production, **never** use `migrate dev`. Instead, use the deployment command which applies all pending migrations in the migrations folder:
```bash
npx prisma migrate deploy
```
---
## Common Scenarios
### Renaming a Column
If you rename a column (e.g., `reasoning` to `thinkingText`), Prisma might try to drop the old column and create a new one, causing data loss.
To fix this:
1. Run `npx prisma migrate dev --name rename_reasoning --create-only`.
2. Open the generated `.sql` file.
3. Replace the `DROP` and `ADD` commands with an `ALTER TABLE ... RENAME COLUMN ...` command.
4. Run `npx prisma migrate dev` to apply your edited SQL.
### Adding Required Fields
When adding a required (`non-nullable`) field to a table with existing data:
1. Generate the migration with `--create-only`.
2. Edit the SQL to provide a default value for existing rows or make it nullable temporarily.
3. Apply the migration.
---
## Upgrading to AgentSession (v0.5.0+)
If you're upgrading from a previous version and want to use the new `AgentSession` feature for persistent agent conversations, you'll need to add the `LlmAgentSession` table.
### Option 1: Use the Provided Migration
Copy the pre-built migration file:
```bash
cp node_modules/@node-llm/orm/migrations/add_agent_session.sql \
prisma/migrations/$(date +%Y%m%d%H%M%S)_add_agent_session/migration.sql
npx prisma migrate resolve --applied $(date +%Y%m%d%H%M%S)_add_agent_session
```
### Option 2: Generate via Prisma
1. Update your `schema.prisma` with the new model:
```prisma
model LlmAgentSession {
id String @id @default(uuid())
agentClass String // Class name for validation
chatId String @unique
metadata Json? // Session context (userId, ticketId)
createdAt DateTime @default(now())
updatedAt DateTime @updatedAt
chat LlmChat @relation(fields: [chatId], references: [id], onDelete: Cascade)
@@index([agentClass])
@@index([createdAt])
}
// Add to existing LlmChat model:
model LlmChat {
// ... existing fields
agentSession LlmAgentSession?
}
```
2. Generate and apply the migration:
```bash
npx prisma migrate dev --name add_agent_session
```
### Verify the Upgrade
Run the sync command to confirm your schema is up to date:
```bash
npx @node-llm/orm sync
# ✓ Schema is already up to date with @node-llm/orm v0.5.0 features.
----------------------------------------
# 📄 orm/prisma.md
---
layout: default
title: Prisma Integration
parent: ORM & Persistence
nav_order: 1
permalink: /orm/prisma
---
# Prisma Integration
{: .no_toc }
NodeLLM + Prisma made simple. Persist chats, messages, and tool calls automatically.
{: .fs-6 .fw-300 }
**Added in v0.2.0**
{: .label .label-green }
1. TOC
{:toc}
---
## Understanding the Persistence Flow
Before diving into setup, it’s important to understand how NodeLLM handles message persistence. This design ensures that your database remains the source of truth, even during streaming or complex tool execution loops.
### How It Works
When calling `chat.ask("What is the capital of France?")`, the ORM adapter:
1. **Creates a User Message** in your database with the input content.
2. **Creates an Empty Assistant Message** immediately. This serves as a "placeholder" for streaming or pending responses.
3. **Fetches History** automatically from the database to provide full context to the LLM.
4. **Executes the Request** via the NodeLLM core:
* **On Tool Call Start**: Creates a record in the `ToolCall` table.
* **On Tool Call End**: Updates the `ToolCall` record with the result.
* **On Response**: Logs the full API metric (tokens, latency, cost) to the `Request` table.
5. **Finalizes the Assistant Message**: Updates the previously created placeholder with the final content and usage metrics.
### Why This Design?
- **Streaming Optimized**: Creates the database record immediately so your UI can target a specific ID for real-time updates.
- **Audit Ready**: Captures partial tool execution data if a process crashes mid-loop.
- **Automated Cleanup**: If the API call fails or is aborted, the ORM automatically cleans up the message records to prevent orphaned "empty" messages.
---
## Setting Up Your Application
### 1. Schema Configuration
The fastest way to get started is to use the **NodeLLM ORM CLI**. Run this command in your project root to generate the required Prisma schema:
```bash
npx @node-llm/orm init
```
This will create a `prisma/schema.prisma` file (or provide instructions if one already exists) populated with the standard models.
Alternatively, you can manually copy the reference models below. You can customize the model names (e.g., using `AssistantChat` instead of `LlmChat`) using the [Custom Table Names](#custom-table-names) option.
```prisma
model LlmChat {
id String @id @default(uuid())
model String?
provider String?
instructions String?
metadata Json? // Use Json for metadata
createdAt DateTime @default(now())
updatedAt DateTime @updatedAt
messages LlmMessage[]
requests LlmRequest[]
}
model LlmMessage {
id String @id @default(uuid())
chatId String
role String // user, assistant, system, tool
content String?
contentRaw String? // JSON raw payload
reasoning String? // Chain of thought (deprecated)
thinkingText String? // Extended thinking text
thinkingSignature String? // Cryptographic signature
thinkingTokens Int? // Tokens spent on thinking
inputTokens Int?
outputTokens Int?
modelId String?
provider String?
createdAt DateTime @default(now())
chat LlmChat @relation(fields: [chatId], references: [id], onDelete: Cascade)
toolCalls LlmToolCall[]
requests LlmRequest[]
}
model LlmToolCall {
id String @id @default(uuid())
messageId String
toolCallId String // ID from the provider
name String
arguments String
thought String?
thoughtSignature String?
result String?
createdAt DateTime @default(now())
message LlmMessage @relation(fields: [messageId], references: [id], onDelete: Cascade)
@@unique([messageId, toolCallId])
}
model LlmRequest {
id String @id @default(uuid())
chatId String
messageId String?
provider String
model String
statusCode Int
duration Int // milliseconds
inputTokens Int
outputTokens Int
cost Float?
createdAt DateTime @default(now())
chat LlmChat @relation(fields: [chatId], references: [id], onDelete: Cascade)
message LlmMessage? @relation(fields: [messageId], references: [id], onDelete: Cascade)
}
```
### 2. Database Migrations
For production-grade systems, always use **Prisma Migrate** instead of `db push`. This ensures you have a versioned history of changes and prevents accidental data loss.
See the [Database Migration Guide](./migrations.md) for detailed instructions.
### 2. Manual Setup
Initialize the adapter with your `PrismaClient` and `NodeLLMCore` instance.
```typescript
import { PrismaClient } from "@prisma/client";
import { createLLM } from "@node-llm/core";
import { createChat, loadChat } from "@node-llm/orm/prisma";
const prisma = new PrismaClient();
const llm = createLLM();
```
---
## Basic Chat Operations
The ORM Chat implementation provides a fluent API that mirrors the core NodeLLM experience.
### Creating and Loading Chats
```typescript
// Start a new session with reasoning enabled by default
const chat = await createChat(prisma, llm, {
model: "claude-3-7-sonnet",
instructions: "You are a helpful assistant.",
thinking: { budget: 16000 }
});
// Load an existing session from DB (automatically rehydrates history)
const savedChat = await loadChat(prisma, llm, "chat-uuid-123");
```
### Asking Questions
When you use `.ask()`, the persistence flow runs automatically.
```typescript
// This saves the user message, calls the API, and persists the response
const messageRecord = await chat.ask("What is the capital of France?");
// You can also pass thinking configuration directly per request
const advancedResp = await chat.ask("Solve this logical puzzle", {
thinking: { budget: 32000 }
});
console.log(messageRecord.content); // "The capital of France is Paris."
console.log(messageRecord.inputTokens); // 12
```
---
## Streaming Responses
For real-time user experiences, use `askStream()`. The assistant message record is "finalized" once the stream completes.
```typescript
for await (const chunk of chat.askStream("Tell me a long story")) {
if (chunk.content) {
process.stdout.write(chunk.content);
}
}
// History is now updated in the DB
const history = await chat.messages();
```
---
## Analytical Views (Insights)
The ORM is great at storing data, but querying it for usage insights (e.g., "How many tokens did this user spend?") can be complex. NodeLLM provides a built-in `stats()` method that aggregates conversation-level metrics efficiently using Prisma's `aggregate` features.
### Conversation Summary
```typescript
const chat = await loadChat(prisma, llm, "chat-uuid-123");
const stats = await chat.stats();
console.log(`Input Tokens: ${stats.input_tokens}`);
console.log(`Output Tokens: ${stats.output_tokens}`);
console.log(`Total Cost: $${stats.cost}`);
```
This method is significantly more efficient than fetching and summing all message records manually, as it performs the calculation directly inside the database.
---
## Advanced Usage
### Custom Table Names
If you are integrating with an existing database schema, you can map the ORM to your custom table names:
```typescript
const tableNames = {
chat: "AssistantChat",
message: "AssistantMessage",
toolCall: "AssistantToolCall",
request: "AssistantRequest"
};
const chat = await createChat(prisma, llm, {
model: "gpt-4o",
tableNames: tableNames
});
```
### Using Tools
Tools are automatically tracked without additional configuration.
```typescript
import { WeatherTool } from "./tools/weather";
await chat.withTool(WeatherTool).ask("How is the weather in London?");
// Check your database:
// The 'LlmToolCall' table will contain the 'get_weather' execution details.
```
---
## Error Handling
If an API call fails, NodeLLM follows a "clean rollback" strategy:
1. The pending Assistant message is **deleted**.
2. The initial User message is **preserved** so you have a record of the request for debugging.
3. The error is thrown for your application to handle.
This ensures your database doesn't fill up with "broken" chat turns.
---
## Agent Sessions v0.5.0+
For stateful agents that need to persist across requests (e.g., support tickets, user sessions), use `AgentSession`. This wraps an [Agent class](/core-features/agents) with database persistence.
### The "Code Wins" Principle
**The Problem with Traditional Systems:**
In traditional AI applications, if you want to resume a conversation, you have to load the implementation details (model, instructions, tools) from the database. If you updated your prompt in the code, the stale database version continues to be used instead of your improved version.
**NodeLLM's Solution:**
AgentSession follows a hybrid sovereignty model where **code always wins** for configuration, but **database always wins** for history:
| Aspect | Source | Why |
|:-------|:-------|:----|
| Model | Agent class (code) | Deploy upgrades immediately |
| Tools | Agent class (code) | Only code can execute functions |
| Instructions | Agent class (code) | Fix prompts without migrations |
| History | Database | Sacred, never modified |
When you resume a session after deploying new code, the session gets the **new configuration** but **preserves the conversation history**.
### Schema Addition
Add `LlmAgentSession` to your Prisma schema:
```prisma
model LlmAgentSession {
id String @id @default(uuid())
agentClass String // Class name for validation (e.g., 'SupportAgent')
chatId String @unique
metadata Json? // Session context (userId, ticketId, etc.)
createdAt DateTime @default(now())
updatedAt DateTime @updatedAt
chat LlmChat @relation(fields: [chatId], references: [id], onDelete: Cascade)
@@index([agentClass])
@@index([createdAt])
}
// Update LlmChat to include the relation
model LlmChat {
// ... existing fields
agentSession LlmAgentSession?
}
```
### Creating Sessions
```typescript
import { Agent, Tool, z, createLLM } from "@node-llm/core";
import { createAgentSession, loadAgentSession } from "@node-llm/orm/prisma";
// Define your agent (config lives in code)
class SupportAgent extends Agent {
static model = "gpt-4.1";
static instructions = "You are a helpful support agent. Be concise.";
static tools = [LookupOrderTool, CancelOrderTool];
}
const prisma = new PrismaClient();
const llm = createLLM({ provider: "openai" });
// Create a new persistent session
const session = await createAgentSession(prisma, llm, SupportAgent, {
metadata: { userId: "user_123", ticketId: "TKT-456" }
});
await session.ask("Where is my order #789?");
console.log(session.id); // "abc-123" - save this!
```
### Resuming Sessions
```typescript
// Later, in a new request
const session = await loadAgentSession(prisma, llm, SupportAgent, "abc-123");
if (!session) {
throw new Error("Session not found");
}
// Continues with full history + current code config
await session.ask("Can you cancel that order?");
```
### Class Validation
For safety, `loadAgentSession` validates that the stored `agentClass` matches the class you're loading with:
```typescript
// This throws an error - class mismatch
await loadAgentSession(prisma, llm, SalesAgent, "support-session-id");
// Error: Agent class mismatch: session was created with "SupportAgent"
// but attempting to load with "SalesAgent"
// To override (not recommended):
await loadAgentSession(prisma, llm, SalesAgent, "support-session-id", {
skipClassValidation: true
});
```
### Session Properties
| Property | Description |
|:---------|:------------|
| `session.id` | The AgentSession UUID (for persistence) |
| `session.chatId` | The underlying LlmChat UUID |
| `session.metadata` | Session context (userId, ticketId, etc.) |
| `session.agentClass` | Stored class name |
| `session.ask()` | Send message with persistence |
| `session.askStream()` | Stream response with persistence |
| `session.messages()` | Get all messages from DB |
| `session.modelId` | Current model (from code) |
| `session.totalUsage` | Aggregate token usage |
----------------------------------------
# 📄 advanced/agentic-workflows.md
---
layout: default
title: Agentic Workflows
nav_order: 2
parent: Advanced
permalink: /advanced/agentic-workflows
description: Compose LLM calls into intelligent workflows that route, research, and collaborate.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
This guide covers advanced agentic patterns for when you need more control than the [Agent class](../core-features/agents.html) provides. For most use cases, start with the Agent class first.
---
## Lower-Level Patterns
For cases where you need more control, you can build agents as tools that call other LLMs directly.
```typescript
import { Tool, z, createLLM } from "@node-llm/core";
class MathTutor extends Tool {
name = "math_tutor";
description = "Explains math concepts";
schema = z.object({ question: z.string() });
async execute({ question }) {
const response = await createLLM({ provider: "openai" })
.chat("gpt-4o")
.system("You are a math tutor. Explain concepts clearly.")
.ask(question);
return response.content;
}
}
// Use as a tool in a coordinator
const llm = createLLM({ provider: "openai" });
const chat = llm.chat("gpt-4o").withTool(MathTutor);
await chat.ask("Help me understand calculus");
```
---
## Parallel Execution
Node.js is async-native. Use `Promise.all()` to run independent LLM calls concurrently.
```typescript
import { createLLM } from "@node-llm/core";
async function analyzeContent(text: string) {
const llm = createLLM({ provider: "openai" });
const [sentiment, summary, topics] = await Promise.all([
llm.chat("gpt-4o-mini").ask(`Sentiment (positive/negative/neutral): ${text}`),
llm.chat("gpt-4o-mini").ask(`One-sentence summary: ${text}`),
llm.chat("gpt-4o-mini").ask(`Extract 3 topics: ${text}`)
]);
return {
sentiment: sentiment.content,
summary: summary.content,
topics: topics.content
};
}
```
---
## Supervisor Pattern
Run specialized reviewers in parallel, then synthesize their findings:
```typescript
import { createLLM } from "@node-llm/core";
async function reviewCode(code: string) {
// Parallel specialist reviews
const [security, performance] = await Promise.all([
createLLM({ provider: "anthropic" })
.chat("claude-sonnet-4-20250514")
.system("Security review. List vulnerabilities.")
.ask(code),
createLLM({ provider: "openai" })
.chat("gpt-4o")
.system("Performance review. List bottlenecks.")
.ask(code)
]);
// Synthesize
return createLLM({ provider: "openai" })
.chat("gpt-4o")
.system("Combine these reviews into actionable recommendations.")
.ask(`Security:\n${security.content}\n\nPerformance:\n${performance.content}`);
}
```
---
## Error Handling in Agents
Agents should handle failures gracefully. See the [Tools guide](../core-features/tools.html#error-handling--flow-control-) for details.
```typescript
class RiskyTool extends Tool {
async execute(args) {
// Recoverable: return error for LLM to retry
if (!args.query) {
return { error: "Query is required" };
}
// Fatal: stop the entire agent loop
if (args.query.includes("DROP TABLE")) {
throw new ToolError("Blocked dangerous query", this.name, true);
}
return await this.doWork(args);
}
}
```
---
## Next Steps
- [Agent Class Guide](../core-features/agents.html) — The recommended way to build agents with a declarative DSL
- [HR Chatbot RAG](https://github.com/node-llm/node-llm/tree/main/examples/applications/hr-chatbot-rag) — Full RAG implementation with Prisma + pgvector
- [Brand Perception Checker](https://github.com/node-llm/node-llm/tree/main/examples/applications/brand-perception-checker) — Multi-tool agent with web search
- [Tool Calling Guide](../core-features/tools.html) — Deep dive on tool patterns and safety
----------------------------------------
# 📄 advanced/custom-providers.md
---
layout: default
title: Custom Providers
parent: Advanced
nav_order: 3
description: Extend NodeLLM with support for proprietary models, internal APIs, or legacy systems using our clean BaseProvider architecture.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
One of the core design goals of \`NodeLLM\` is provider-agnosticism. While we ship with support for major providers, you can easily add your own custom provider for internal APIs, proprietary models, or legacy systems.
The **recommended** way to create a custom provider is by extending the `BaseProvider` class.
## Why BaseProvider?
Extending `BaseProvider` instead of implementing the raw `Provider` interface gives you several advantages:
1. **Safety**: It provides default implementations for features you might not support (like tools, embeddings, or vision), which will throw clean `UnsupportedFeatureError`s instead of failing with undefined errors.
2. **Consistency**: It ensures your provider follows the project's internal mapping and logging standards.
3. **Less Boilerplate**: You only need to implement the methods your service actually provides.
## Creating a Provider
To create a new provider, extend `BaseProvider` and implement the abstract methods.
> **Note**: The examples below use TypeScript. If you are using plain JavaScript (`.js` or `.mjs`), remember to remove access modifiers like `public` and `protected`.
```ts
import { NodeLLM, BaseProvider, ChatRequest, ChatResponse } from "@node-llm/core";
class MyCustomProvider extends BaseProvider {
constructor(config: { apiKey: string; region: string }) {
super();
this.apiKey = config.apiKey;
this.region = config.region;
}
// Required: A unique string identifier for your provider
protected providerName() {
return "my-custom-service";
}
// Required: The base URL for your API
public apiBase() {
return `https://api.${this.region}.my-service.com/v1`;
}
// Required: Any headers needed for authentication
public headers() {
return {
Authorization: `Bearer ${this.apiKey}`,
"Content-Type": "application/json"
};
}
// Required: Define the main chat implementation
async chat(request: ChatRequest): Promise {
return {
content: "Hello from my custom provider!",
usage: { input_tokens: 5, output_tokens: 5, total_tokens: 10 }
};
}
// Required: Provide a default model ID
public defaultModel(feature?: string): string {
return "my-model-v1";
}
}
```
## Defining Capabilities
Capabilities tell NodeLLM what your provider is actually capable of. By default, `BaseProvider` assumes most advanced features are disabled. You can override these to opt-in to specific framework behaviors.
```ts
class MyCustomProvider extends BaseProvider {
// ... rest of implementation
public capabilities = {
...this.defaultCapabilities(), // Start with defaults
// Enable support for OpenAI-style 'developer' roles
supportsDeveloperRole: (modelId: string) => true,
// Declare vision support
supportsVision: (modelId: string) => modelId.includes("vision"),
// Declare the context window size
getContextWindow: (modelId: string) => 128000
};
}
```
Notably, if `supportsDeveloperRole` is true, NodeLLM will automatically map isolated system instructions to the `developer` role. If false (the default), it will keep them as the standard `system` role.
## Registering Your Provider
Register your provider with `NodeLLM` during your application's initialization.
```ts
// 1. Register the factory function
NodeLLM.registerProvider("my-service", () => new MyCustomProvider());
// 2. Use it globally
const llm = createLLM({ provider: "my-service" });
const response = await llm.chat().ask("Hi!");
```
## Advanced Implementation
### Supporting Streaming
If your provider supports streaming, override the `stream` generator:
```ts
async *stream(request: ChatRequest) {
// Simulated streaming
const words = ["This", "is", "a", "stream"];
for (const word of words) {
yield { content: word + " " };
}
}
```
### Handling Scoped Credentials
It's best to pull configuration from environment variables or use the injected configuration when the provider factory is called:
```ts
NodeLLM.registerProvider("internal-llm", (config) => {
return new MyCustomProvider({
apiKey: config?.["internalApiKey"] || process.env.INTERNAL_LLM_KEY,
region: "us-east-1"
});
});
```
### Handling Extra Fields
End-users might want to pass provider-specific parameters that aren't part of the standard `NodeLLM` API. These can be sent using `.withParams()` and will be available in the `request` object passed to your `chat` method.
```ts
async chat(request) {
// Destructure to separate standard fields from custom ones
const { model, messages, ...customParams } = request;
if (customParams.internal_routing_id) {
// Handle custom logic...
}
}
```
### Handling Request Timeouts
NodeLLM passes `requestTimeout` (in milliseconds) through all request interfaces. Your custom provider should respect this timeout to ensure consistent security behavior across all providers.
Use the built-in `fetchWithTimeout` utility:
```ts
import { fetchWithTimeout } from "@node-llm/core";
async chat(request: ChatRequest): Promise {
const response = await fetchWithTimeout(
`${this.apiBase()}/chat`,
{
method: "POST",
headers: this.headers(),
body: JSON.stringify({
model: request.model,
messages: request.messages
})
},
request.requestTimeout // Pass through the timeout
);
const json = await response.json();
return {
content: json.response,
usage: json.usage
};
}
```
**Note**: The `requestTimeout` parameter is available in all provider methods:
- `chat(request)`, `stream(request)`, `paint(request)`, `transcribe(request)`, `moderate(request)`, `embed(request)`
## High-Fidelity Error Handling
To make your custom provider feel like a "first-class citizen," you should map your API errors to NodeLLM's specialized error classes. This ensures that features like **automatic retries** and **smart recovery** work as expected.
### Recommended Error Mapping
| Status | Standard Class | Specialized Class (Preferred) | Behavior |
| :--- | :--- | :--- | :--- |
| **400** | `BadRequestError` | `ContextWindowExceededError` | Fatal (No Retry) |
| **401** | `UnauthorizedError` | - | Fatal (No Retry) |
| **404** | `NotFoundError` | `InvalidModelError` | Fatal (No Retry) |
| **429** | `RateLimitError` | `InsufficientQuotaError` | **Retryable** (except Quota) |
| **5xx** | `ServerError` | `ServiceUnavailableError` | **Retryable** |
### Implementation Pattern
The most robust way to handle errors is to create a dedicated error handler function:
```ts
import {
BadRequestError,
ContextWindowExceededError,
RateLimitError,
ServerError
} from "@node-llm/core";
async function myErrorHandler(response: Response, modelId: string): Promise {
const status = response.status;
const body = await response.json().catch(() => ({}));
const message = body.error?.message || "Unknown error";
if (status === 400) {
if (message.includes("tokens") || message.includes("context")) {
throw new ContextWindowExceededError(message, body, "my-service", modelId);
}
throw new BadRequestError(message, body, "my-service", modelId);
}
if (status === 429) {
throw new RateLimitError(message, body, "my-service", modelId);
}
if (status >= 500) {
throw new ServerError(message, status, body, "my-service", modelId);
}
throw new Error(`Technical failure (${status}): ${message}`);
}
```
Then use it in your `chat` or `stream` methods:
```ts
async chat(request: ChatRequest) {
const response = await fetch(...);
if (!response.ok) {
await myErrorHandler(response, request.model);
}
return await response.json();
}
```
## Custom Pricing
If your custom provider has associated costs, you can register them in the `PricingRegistry`. This allows `NodeLLM` to automatically calculate usage costs for your custom models.
```ts
import { PricingRegistry } from "@node-llm/core";
// Register pricing for your custom service
PricingRegistry.register("my-custom-service", "my-model-v1", {
text_tokens: {
standard: {
input_per_million: 1.5,
output_per_million: 4.5
}
}
});
```
For more details on managing costs, see the [Model Pricing](./pricing.md) guide.
## Deep Dive
- [Building a Custom Provider for Cohere on Oracle Cloud](https://www.eshaiju.com/blog/custom-nodellm-provider-oracle) — A real-world example of extending NodeLLM for proprietary cloud gateways.
## Example Implementation
See the [Custom Provider Example](https://github.com/node-llm/node-llm/blob/main/examples/scripts/core/custom-provider.mjs) in the repository for a complete working implementation including error handling, streaming, and extra field support.
----------------------------------------
# 📄 advanced/custom_endpoints.md
---
layout: default
title: Custom Endpoints
parent: Advanced
nav_order: 4
description: Connect NodeLLM to Azure OpenAI, LiteLLM, Ollama, or any OpenAI-compatible API and use custom models outside the standard registry.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
`NodeLLM` is flexible enough to connect to any OpenAI-compatible service and use custom models.
---
## OpenAI-Compatible Endpoints
Connect to services like Azure OpenAI, LiteLLM, or Ollama by configuring the base URL.
### Generic Configuration
Set `OPENAI_API_BASE` to your custom endpoint:
```bash
# LiteLLM
export OPENAI_API_KEY="your-litellm-key"
export OPENAI_API_BASE="https://your-proxy.litellm.ai/v1"
# Ollama (Local)
export OPENAI_API_KEY="not-needed"
export OPENAI_API_BASE="http://localhost:11434/v1"
```
### Azure OpenAI
For Azure, point `OPENAI_API_BASE` to your specific deployment URL. The library correctly handles URL construction even with query parameters.
```bash
export OPENAI_API_KEY="your-azure-key"
# Include the full path to your deployment
export OPENAI_API_BASE="https://YOUR_RESOURCE.openai.azure.com/openai/deployments/YOUR_DEPLOYMENT?api-version=2024-08-01-preview"
```
Then, pass the `api-key` header manually when creating the chat instance:
```typescript
import { createLLM } from "@node-llm/core";
const llm = createLLM({ provider: "openai" });
const chat = llm.chat("gpt-4").withRequestOptions({
headers: { "api-key": process.env.OPENAI_API_KEY }
});
const response = await chat.ask("Hello Azure!");
```
---
## Using Custom Models
If you use a model ID not in the built-in registry (e.g., custom Azure names or new models), use `assumeModelExists: true` to bypass validation.
```typescript
const chat = llm.chat("my-company-gpt-4", {
assumeModelExists: true,
// Provider is typically required if not already configured globally
provider: "openai"
});
await chat.ask("Hello");
```
This flag is available on all major methods:
```typescript
// Embeddings
await NodeLLM.embed("text", {
model: "custom-embedder",
assumeModelExists: true
});
// Image Generation
await NodeLLM.paint("prompt", {
model: "custom-dalle",
assumeModelExists: true
});
```
**Note:** When using this flag, strict capability checks (e.g., whether a model supports vision) are skipped. You are responsible for ensuring the model supports the requested features.
----------------------------------------
# 📄 advanced/debugging.md
---
layout: default
title: Debugging & Logging
parent: Advanced
nav_order: 3
description: Peek under the hood and inspect raw API requests, responses, and model alias resolution to troubleshoot your AI workflows.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
When building LLM applications, understanding what's happening "under the hood" is critical. \`NodeLLM\` provides mechanisms to inspect raw requests and responses.
## Debug Mode
You can enable detailed debug logging in two ways:
### Programmatic Configuration (Recommended)
```ts
import { createLLM } from "@node-llm/core";
const llm = createLLM({ debug: true });
```
This will print the raw HTTP requests and responses for **all API calls** across **every feature and provider**.
### Environment Variable
```bash
export NODELLM_DEBUG=true
node my-app.js
```
### Scoped Debug Mode
You can also enable debug mode for specific provider instances:
```ts
const debugAnthropic = NodeLLM.withProvider("anthropic", { debug: true });
```
**Output Example:**
```text
[NodeLLM] [OpenAI] Request: POST https://api.openai.com/v1/chat/completions
{
"model": "gpt-4o",
"messages": [...],
"tools": [...]
}
[NodeLLM] [OpenAI] Response: 200 OK
{
"id": "chatcmpl-123",
"choices": [...],
"usage": {...}
}
```
### Coverage
Debug logging works for:
- **Chat** (regular and streaming)
- **Image Generation** (OpenAI, Gemini)
- **Embeddings** (OpenAI, Gemini, Ollama, Mistral)
- **Transcription** (OpenAI, Gemini, Mistral)
- **Moderation** (OpenAI, Mistral)
- **Model Alias Resolution** (all providers)
- **All Providers** (OpenAI, Anthropic, Gemini, DeepSeek, Bedrock, OpenRouter, xAI, Ollama, Mistral)
The logs include:
- HTTP method and full URL
- Request body (JSON formatted)
- Response status code and status text
- Response body (JSON formatted)
- Model alias resolution (when using aliases)
### Model Alias Resolution
When debug mode is enabled, you'll see logs showing how model aliases are resolved:
```text
[NodeLLM Debug] Resolved model alias 'claude-3-5-haiku' → 'claude-3-5-haiku-20241022' for provider 'anthropic'
[NodeLLM Debug] No alias mapping found for 'custom-model' with provider 'anthropic', using as-is
```
This is particularly helpful when debugging 404 errors, as it shows the actual model ID being sent to the API.
## Lifecycle Handlers
For programmatic observability (e.g., sending logs to Datadog or Sentry), use the [Chat Event Handlers](/core-features/chat.html#lifecycle-events).
```ts
chat
.onNewMessage(() => logger.info("Chat started"))
.onEndMessage((res) => logger.info("Chat finished", { tokens: res.total_tokens }));
```
----------------------------------------
# 📄 advanced/error-handling.md
---
layout: default
title: Error Handling
parent: Advanced
nav_order: 3
description: Build resilient AI applications with NodeLLM's descriptive error hierarchy and unified error reporting across all providers.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
NodeLLM provides a descriptive exception hierarchy to help you handle failures gracefully. All errors inherit from the base `LLMError` class.
## Error Hierarchy
All errors raised by NodeLLM inherit from `LLMError`. Specific errors map to HTTP status codes or library-specific issues:
```
LLMError # Base error class
├── APIError # Base for all provider API issues
│ ├── BadRequestError # 400: Invalid request parameters
│ │ └── ContextWindowExceededError # 400: Prompt/output exceeds token limits
│ ├── UnauthorizedError # 401: Invalid or missing API key
│ ├── PaymentRequiredError # 402: Billing issues
│ ├── ForbiddenError # 403: Permission denied
│ ├── RateLimitError # 429: Rate limit exceeded
│ │ └── InsufficientQuotaError # 429: Out of credits or monthly quota
│ ├── ServerError # 500+: Provider server error
│ │ └── ServiceUnavailableError # 502/503/529: Overloaded
│ └── AuthenticationError # 401/403 (deprecated, use specific classes)
├── ConfigurationError # Missing API key or invalid config
├── NotFoundError # Model or provider not found
│ └── InvalidModelError # 404: Requested model ID is unknown
├── CapabilityError # Model doesn't support feature (e.g. vision)
├── ToolError # Tool execution failed (has `fatal` property)
├── ProviderNotConfiguredError # No provider set
├── UnsupportedFeatureError # Provider doesn't support feature
└── ModelCapabilityError # Model doesn't support capability
```
---
## Basic Error Handling
Catch the base `LLMError` for generic handling:
```typescript
import { LLMError, ConfigurationError } from "@node-llm/core";
try {
const response = await chat.ask("Hello");
} catch (error) {
if (error instanceof ConfigurationError) {
console.error("Check your API key configuration");
} else if (error instanceof LLMError) {
console.error("AI error:", error.message);
} else {
throw error;
}
}
```
---
## Handling Specific Errors
For granular control, catch specific error classes:
```typescript
import {
UnauthorizedError,
PaymentRequiredError,
ForbiddenError,
RateLimitError,
ServerError,
CapabilityError
} from "@node-llm/core";
try {
await chat.ask("Analyze this image", { files: ["image.png"] });
} catch (error) {
if (error instanceof UnauthorizedError) {
console.error("Invalid API key. Check your configuration.");
} else if (error instanceof PaymentRequiredError) {
console.error("Billing issue. Check your provider account.");
} else if (error instanceof ForbiddenError) {
console.error("Permission denied. Check API key scopes.");
} else if (error instanceof RateLimitError) {
console.warn("Rate limited. Waiting before retry...");
await sleep(5000);
} else if (error instanceof CapabilityError) {
console.error("This model doesn't support images. Try gpt-4o.");
} else if (error instanceof ServerError) {
console.error("Provider is having issues. Try again later.");
} else {
throw error;
}
}
```
---
## Accessing Response Details
`APIError` instances contain details about the failed request:
```typescript
import { APIError } from "@node-llm/core";
try {
await chat.ask("Something that fails");
} catch (error) {
if (error instanceof APIError) {
console.log(`Status: ${error.status}`); // e.g. 429
console.log(`Provider: ${error.provider}`); // e.g. "openai"
console.log(`Model: ${error.model}`); // e.g. "gpt-4o"
console.log(`Body:`, error.body); // Raw error response
}
}
```
---
## Error Handling During Streaming
When streaming, errors can occur after some chunks have been received. NodeLLM will throw after the stream ends or is interrupted:
```typescript
let accumulated = "";
try {
for await (const chunk of chat.stream("Tell me a long story")) {
accumulated += chunk.content || "";
process.stdout.write(chunk.content || "");
}
} catch (error) {
console.error("\nStream failed:", error.message);
console.log("Partial content received:", accumulated);
}
```
Your loop will process chunks received before the error. Always handle partial content when streaming.
---
## Handling Errors Within Tools
When building tools, decide how errors should surface:
### Return Error to LLM (Recoverable)
If the LLM might fix the issue (e.g., bad parameters), return an error object:
```typescript
class WeatherTool extends Tool {
async execute({ location }) {
if (!location) {
return { error: "Location is required. Please provide a city name." };
}
// ... call API
}
}
```
### Throw Error (Fatal)
If the error is unrecoverable, throw it to stop the agent loop:
```typescript
import { ToolError } from "@node-llm/core";
class DatabaseTool extends Tool {
async execute({ query }) {
if (query.includes("DROP")) {
throw new ToolError("Dangerous query blocked", "database", true);
}
// ...
}
}
```
See [Tool Error Handling](../core-features/tools.html#error-handling--flow-control-) for more patterns.
---
## Automatic Retries
NodeLLM automatically retries transient errors:
- **Retried**: `RateLimitError` (429), `ServerError` (500+), `ServiceUnavailableError`
- **Not retried**: `BadRequestError` (400), `UnauthorizedError` (401), `ForbiddenError` (403), `ContextWindowExceededError`, `InsufficientQuotaError`
> **Why not retry on Context Window Overflows?**
> A `ContextWindowExceededError` (400) is considered a client-side logic error. Retrying with the same payload would consistently fail. By identifying this specific error, developers can implement smarter recovery logic, such as trimming chat history or summarizing previous turns before retrying manually.
Configure retry behavior:
```typescript
const llm = createLLM({
provider: "openai",
maxRetries: 3 // Default: 3
});
```
---
## Debugging
Enable debug logging to see detailed request/response information:
```bash
export NODELLM_DEBUG=true
```
This logs API calls, headers, and responses (with sensitive data filtered).
---
## Best Practices
1. **Be Specific**: Catch specific error classes for tailored recovery logic.
2. **Log Context**: Include model, provider, and (safe) input data in logs.
3. **User Feedback**: Show friendly messages, not raw API errors.
4. **Fallbacks**: Consider trying a different model or returning cached data.
5. **Monitor**: Track error frequency in production to identify patterns.
---
## Next Steps
- [Tool Calling](../core-features/tools.html) — Build tools with proper error handling
- [Streaming](../core-features/streaming.html) — Handle streaming responses
- [Security](security.html) — Protect your application with rate limits and guards
----------------------------------------
# 📄 advanced/index.md
---
layout: default
title: Advanced
nav_order: 4
has_children: true
nav_fold: false
permalink: /advanced
description: Master NodeLLM with advanced concepts like custom providers, security policies, and parallel model execution.
back_to_top: false
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
----------------------------------------
# 📄 advanced/multi_provider_parallel.md
---
layout: default
title: Parallel Execution
parent: Advanced
nav_order: 10
description: Learn how to safely run multiple LLM providers concurrently using NodeLLM’s scoped context system to avoid global state race conditions.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
## The Problem
In previous versions, `NodeLLM` was a mutable singleton. Calling `NodeLLM.configure()` concurrently could lead to race conditions where one request would overwrite the configuration of another.
---
## The Solution
As of v1.6.0, `NodeLLM` is a **frozen, immutable instance**. It cannot be mutated at runtime. For parallel execution with different providers or configurations, you use **context branching** via `.withProvider()` or create independent instances via `createLLM()`.
---
## How To Use It
### Simple Parallel Calls
The most elegant way to run multiple providers is using `.withProvider()`. This creates a scoped, isolated instance for that specific call.
```javascript
import { NodeLLM } from "@node-llm/core";
const [score1, score2, score3] = await Promise.all([
NodeLLM.withProvider("openai").chat("gpt-4o").ask(prompt),
NodeLLM.withProvider("anthropic").chat("claude-3-5-sonnet").ask(prompt),
NodeLLM.withProvider("gemini").chat("gemini-2.0-flash").ask(prompt)
]);
```
---
## Benefits
✅ **Singleton Maintained**: No need to use `new NodeLLM()` unless you want to.
✅ **Race Condition Solved**: Each `.withProvider()` call creates an isolated context.
✅ **Clean Syntax**: Chaining `.withProvider().chat().ask()` is intuitive and elegant.
✅ **Automatic Key Sharing**: Scoped instances inherit the global API keys by default.
---
## Example
Check out the [Parallel Scoring Example](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/core/parallel-scoring.mjs) for a working demonstration.
----------------------------------------
# 📄 advanced/pricing.md
---
layout: default
title: Model Pricing
parent: Advanced
nav_order: 4
description: Learn how to manage, override, and fetch LLM pricing data in NodeLLM.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
NodeLLM comes with built-in pricing data for over 9,000 models, updated weekly from [models.dev](https://models.dev). However, you may need to override these prices for custom contracts, handle new models before they enter our registry, or manage pricing for local/custom providers.
---
## The Pricing Registry
All pricing logic is managed by the `PricingRegistry`. This registry uses a tiered lookup strategy to determine the cost of a model:
1. **Runtime Overrides**: Manual registrations or remote updates.
2. **Expert Patterns**: Hardcoded library patterns for specific model families (e.g., Claude 3.7 reasoning).
3. **Static Registry**: The default values from our weekly-updated `models.ts`.
### Runtime Overrides
You can manually register pricing for any model at runtime. This is particularly useful for custom providers or private deployments.
```ts
import { PricingRegistry } from "@node-llm/core";
PricingRegistry.register("mistral", "mistral-large-latest", {
text_tokens: {
standard: {
input_per_million: 2.0,
output_per_million: 6.0
}
}
});
```
### Remote Updates
For dynamic pricing management without code changes, you can fetch updates from a remote JSON endpoint.
```ts
await PricingRegistry.fetchUpdates("https://api.yourcompany.com/llm-pricing.json");
```
The JSON format should match:
```json
{
"models": {
"openai/gpt-5": {
"text_tokens": {
"standard": { "input_per_million": 1.0, "output_per_million": 5.0 }
}
}
}
}
```
---
## Custom Providers
Custom providers (e.g., local instances of LLMs or internal proxies) can define their own pricing logic.
### Registering the Model
First, ensure the model exists in the `ModelRegistry` so NodeLLM knows its context window and capabilities.
```ts
import { ModelRegistry } from "@node-llm/core";
ModelRegistry.save({
id: "local-llama",
name: "Local Llama 3",
provider: "local",
context_window: 8192,
capabilities: ["chat", "streaming"],
modalities: { input: ["text"], output: ["text"] }
});
```
### Registering the Price
Then, assign it a price in the `PricingRegistry`.
```ts
import { PricingRegistry } from "@node-llm/core";
PricingRegistry.register("local", "local-llama", {
text_tokens: {
standard: {
input_per_million: 0.0, // Free local model
output_per_million: 0.0
}
}
});
```
---
## Cost Calculation
NodeLLM automatically calculates costs when a `usage` object is returned by a provider. You can also perform manual calculations using the registry:
```ts
import { ModelRegistry } from "@node-llm/core";
const usage = {
input_tokens: 1000,
output_tokens: 500,
total_tokens: 1500
};
const costInfo = ModelRegistry.calculateCost(usage, "gpt-4o", "openai");
console.log(costInfo.cost); // Total cost in USD
```
---
## Advanced: Reasoning & Batch Pricing
For models that support specialized features, you can define more granular pricing:
```ts
PricingRegistry.register("openai", "o1-preview", {
text_tokens: {
standard: {
input_per_million: 15.0,
output_per_million: 60.0,
reasoning_output_per_million: 60.0, // Specific reasoning cost
cached_input_per_million: 7.50 // Discounted cache read
},
batch: {
input_per_million: 7.50,
output_per_million: 30.0
}
}
});
```
----------------------------------------
# 📄 advanced/security.md
---
layout: default
title: Security & Compliance
parent: Advanced
nav_order: 1
permalink: /advanced/security
description: Learn how NodeLLM acts as an architectural security layer with context isolation, content filtering, human-in-the-loop tool execution, and resource limits.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
NodeLLM is built from the ground up to be an **architectural security layer**. In production AI applications, the LLM is often the most vulnerable component due to prompt injection, instruction drift, and potential PII leakage.
NodeLLM provides several "Zero-Config" and pluggable security features to mitigate these risks.
---
## 🧱 Smart Context Isolation
The most common vector for LLM vulnerabilities is **Instruction Injection**, where user input tricks the model into ignoring its system instructions.
NodeLLM solves this by maintaining a strict architectural boundary between **System Instructions** and **Conversation History**.
- **Isolation**: Instructions are stored separately from the user message stack. They are never interleaved in a way that allows a user to "close" a system block.
- **Priority**: When sending a payload to a provider, NodeLLM ensures instructions are placed in the most authoritative role available.
- **Drift Protection**: Even in long conversations with many turns, NodeLLM continuously re-asserts the system context as the primary authority.
---
## 🛡️ Content Policy Hooks v1.5.0+
NodeLLM allows you to inject security and compliance policies at the **edge** of the request/response cycle using asynchronous hooks.
### `beforeRequest` (Input Guardrail)
Intercept messages before they reach the LLM. Use this for **PII Detection** and **Redaction**.
```ts
chat.beforeRequest(async (messages) => {
for (const msg of messages) {
if (typeof msg.content === "string") {
msg.content = msg.content.replace(/\d{3}-\d{2}-\d{4}/g, "[REDACTED_SSN]");
}
}
return messages;
});
```
### `afterResponse` (Output Guardrail)
Verify the LLM's output before it reaches your application logic. Use this for **Compliance Verification** or **Sensitive Data Masking**.
```ts
chat.afterResponse(async (response) => {
if (response.content.includes("SECRET_API_KEY")) {
return response.withContent("Error: Sensitive data detected in output.");
}
});
```
---
## 🔍 Observability as Security v1.5.0+
Security in AI is not just about blocking; it's about **Auditing**. NodeLLM provides high-fidelity hooks for monitoring the entire lifecycle of tool executions, which are often the most sensitive part of an AI agent.
- **`onToolCallStart`**: Audit exactly what parameters the LLM is trying to send to your internal functions.
- **`onToolCallEnd`**: Record the raw data returned from your systems to the LLM.
- **`onToolCallError`**: Track failed attempts or malicious inputs that caused tool crashes.
```ts
chat
.onToolCallStart((call) => auditLog.info(`Tool ${call.function.name} requested`))
.onToolCallError((call, err) => incidentResponse.trigger(`Tool failure: ${err.message}`));
```
---
## 🚦 Tool Execution Policies v1.5.0+
For sensitive operations (like database writes or financial transactions), NodeLLM provides granular control over the tool execution lifecycle via `toolExecution` modes.
- **`auto`**: (Default) Tools are executed immediately as proposed by the LLM.
- **`confirm`**: Enables **Human-in-the-loop**. NodeLLM pauses before execution and awaits approval via the `onConfirmToolCall` hook.
- **`dry-run`**: Proposes the tool call structure but **never executes it**. Useful for UI previews or verification-only flows.
```ts
chat.withToolExecution("confirm").onConfirmToolCall(async (call) => {
// Return true to execute, false to cancel
return await userResponse.confirm(`Allow tool: ${call.function.name}?`);
});
```
**Security Benefits:**
- **Prevents Destructive Actions**: Stops the model from accidentally deleting data without oversight.
- **Human-in-the-loop**: Increases trust by ensuring critical business logic remains under human control.
---
## 🛡️ Loop Protection & Resource Limits v1.5.0+
NodeLLM provides **defense-in-depth** protection against resource exhaustion, runaway costs, and denial-of-service attacks through configurable execution limits.
### Request Timeout
Prevent hanging requests that could tie up resources or enable DoS attacks. By default, all requests timeout after **30 seconds**.
```ts
// Global configuration
const llm = createLLM({
requestTimeout: 30000 // 30 seconds (default)
});
// Per-request override for long-running tasks
await chat.ask("Analyze this large dataset", {
requestTimeout: 120000 // 2 minutes
});
```
**Security Benefits:**
- **DoS Protection**: Prevents malicious or buggy providers from hanging indefinitely
- **Resource Control**: Limits memory, connection, and thread pool consumption
- **Cost Control**: Prevents runaway requests from generating unexpected costs
- **Predictable SLAs**: Ensures applications have predictable response times
### Loop Guard (Tool Execution Limit)
Prevent infinite tool execution loops that could exhaust resources or rack up costs.
```ts
const llm = createLLM({
maxToolCalls: 5 // Stop after 5 sequential tool execution turns (default)
});
// Override for complex workflows
await chat.ask("Deep research task", { maxToolCalls: 10 });
```
**Security Benefits:**
- **Cost Control**: Prevents infinite loops from generating unbounded API costs
- **Resource Protection**: Stops runaway tool executions from exhausting system resources
### Retry Limit
Prevent retry storms that could cascade through your system during provider outages.
```ts
const llm = createLLM({
maxRetries: 2 // Retry failed requests twice (default)
});
```
**Security Benefits:**
- **Cascading Failure Prevention**: Stops retry storms during provider outages
- **Resource Protection**: Prevents excessive retries from exhausting connection pools
### Complete Security Configuration
Combine all limits for comprehensive protection:
```ts
const llm = createLLM({
requestTimeout: 30000, // 30 second timeout
maxRetries: 2, // Retry failed requests twice
maxToolCalls: 5, // Limit tool execution loops
maxTokens: 4096 // Limit output to 4K tokens
});
```
This creates a **defense-in-depth** strategy where multiple layers of protection work together to prevent resource exhaustion, cost overruns, and service disruptions.
**Security Summary:**
- **`requestTimeout`**: DoS protection, resource control, predictable SLAs
- **`maxRetries`**: Prevents cascading failures and retry storms
- **`maxToolCalls`**: Prevents infinite loops and runaway costs
- **`maxTokens`**: Prevents excessive output generation and cost overruns
---
## ⚡ Smart Developer Role
Modern models (like OpenAI's **o1**, **o3**, and **GPT-4o**) have introduced a specialized `developer` role. This role has higher "Instruction Authority" than the standard `system` role.
NodeLLM **automatically detects** if a model supports this role. If it does, your system instructions are elevated to the `developer` role, making the model significantly more resistant to prompt injection and more likely to follow strict guidelines.
---
## 🔐 Privacy & Data Strategy
- **Stateless Architecture**: NodeLLM is a library, not a service. We do not store, log, or transmit your data to any third-party servers other than the providers you explicitly configure.
- **Local Sovereignty**: Since NodeLLM supports **Ollama**, you can run the entire stack (including security policies) on-premise without ever sending data over the internet.
- **Encapsulated History**: Conversation history is stored in-memory within the `Chat` instance and is only shared with the provider at the moment of a request.
----------------------------------------
# 📄 advanced/token_usage.md
---
layout: default
title: Token Usage
parent: Advanced
nav_order: 5
description: Monitor costs and resource consumption by tracking input/output tokens and estimated spend for individual requests or entire chat sessions.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
Track tokens for individual turns or the entire conversation to monitor costs and usage.
## Per-Response Usage
Every response object contains usage metadata for that specific interaction.
const response = await chat.ask("Hello!");
// Standard Snake Case
console.log(response.input_tokens);
// Modern Camel Case Alias v1.6.0
console.log(response.inputTokens);
// Full Metadata Object (Perfect for DB storage) v1.6.0
console.log(response.meta);
// => { usage: {...}, model: "...", provider: "...", reasoning: "..." }
```
## Session Totals
The `Chat` instance maintains a running total of usage for the life of that object.
```ts
// Access aggregated usage for the whole session
console.log(chat.totalUsage.total_tokens);
console.log(chat.totalUsage.cost);
```
----------------------------------------
# 📄 examples.md
---
layout: default
title: Examples
nav_order: 7
description: Explore a comprehensive collection of runnable examples demonstrating every feature from basic chat to advanced multi-agent security policies.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
A comprehensive list of runnable examples available in the [examples/](https://github.com/node-llm/node-llm/tree/main/examples) directory of the repository.
## 🌟 Showcase
| Example | Description |
| :------------------------------------------------------------------------------------------------------------------------------------------------------ | :---------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [`examples/applications/brand-perception-checker/`](https://github.com/node-llm/node-llm/tree/main/examples/applications/brand-perception-checker) | **Brand Perception Auditor** — A full-stack (Node+React) app demonstrating multi-provider orchestration, tool calling (Google SERP), and structured output. |
| [`examples/applications/hr-chatbot-rag/`](https://github.com/node-llm/node-llm/tree/main/examples/applications/hr-chatbot-rag) | **HR Chatbot RAG** — A production Next.js chatbot featuring `@node-llm/orm`, streaming, and persistence. |
| [`examples/scripts/openai/core/support-agent.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/core/support-agent.mjs) | **Real-world Travel Support AI Agent** using Context Isolation, Auto-executing Tools, and Structured Output. |
| [`examples/scripts/openai/security/content-policy-hooks.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/security/content-policy-hooks.mjs) | **Content Policy & Security** using `beforeRequest` and `afterResponse` hooks for PII redaction. |
| [`examples/scripts/openai/security/tool-policies.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/security/tool-policies.mjs) | **Advanced Tool Security** using `confirm` and `dry-run` modes for human-in-the-loop auditing. |
## OpenAI Examples
| Example | Description |
| :---------------------------------------------------------------------------------------------------------------------------------------- | :---------------------------------- |
| [`examples/scripts/openai/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/basic.mjs) | Basic chat with streaming |
| [`examples/scripts/openai/chat/events.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/events.mjs) | Lifecycle hooks (onNewMessage, etc) |
| [`examples/scripts/openai/chat/tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/tools.mjs) | Automatic tool execution |
| [`examples/scripts/openai/chat/tool-dsl.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/tool-dsl.mjs) | Class-based Tool DSL |
| [`examples/scripts/openai/chat/structured.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/structured.mjs) | Zod schema validation |
| [`examples/scripts/openai/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/multimodal/vision.mjs) | Image analysis via URL |
| [`examples/scripts/openai/multimodal/files.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/multimodal/files.mjs) | Analyzing local files |
| [`examples/scripts/openai/images/generate.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/images/generate.mjs) | DALL-E 3 Generation |
| [`examples/scripts/openai/safety/moderation.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/safety/moderation.mjs) | Custom safety thresholds |
| [`examples/scripts/openai/embeddings/create.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/embeddings/create.mjs) | Creating text embeddings |
| [`examples/scripts/openai/chat/usage.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/usage.mjs) | Token usage tracking |
| [`examples/scripts/openai/chat/parallel-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/parallel-tools.mjs) | Parallel tool execution |
| [`examples/scripts/openai/chat/max-tokens.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/max-tokens.mjs) | Controlling output length |
| [`examples/scripts/openai/chat/streaming-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/streaming-tools.mjs) | Tool use with streaming |
| [`examples/scripts/openai/chat/instructions.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/instructions.mjs) | System prompt instructions |
| [`examples/scripts/openai/chat/reasoning.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/reasoning.mjs) | Reasoning capabilities (o1) |
| [`examples/scripts/openai/chat/params.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/params.mjs) | Custom model parameters |
| [`examples/scripts/openai/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/chat/streaming.mjs) | Advanced streaming examples |
| [`examples/scripts/openai/discovery/models.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/discovery/models.mjs) | Listing available models |
| [`examples/scripts/openai/multimodal/transcribe.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/multimodal/transcribe.mjs) | Audio transcription |
| [`examples/scripts/openai/multimodal/multi-image.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openai/multimodal/multi-image.mjs) | Multiple image analysis |
### Gemini
| Example | Description |
| :--- | :--- |
| [`examples/scripts/gemini/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/basic.mjs) | Streaming chat with Gemini 1.5 |
| [`examples/scripts/gemini/chat/json_mode.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/json_mode.mjs) | Native JSON mode |
| [`examples/scripts/gemini/multimodal/video.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/multimodal/video.mjs) | Analyzing video files |
| [`examples/scripts/gemini/multimodal/audio.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/multimodal/audio.mjs) | Native audio understanding |
| [`examples/scripts/gemini/multimodal/files.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/multimodal/files.mjs) | Multi-file context |
| [`examples/scripts/gemini/embeddings/create.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/embeddings/create.mjs) | Creating text embeddings |
| [`examples/scripts/gemini/chat/structured.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/structured.mjs) | Structured output with Zod |
| [`examples/scripts/gemini/chat/usage.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/usage.mjs) | Token usage tracking |
| [`examples/scripts/gemini/chat/parallel-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/parallel-tools.mjs) | Parallel tool execution |
| [`examples/scripts/gemini/chat/max-tokens.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/max-tokens.mjs) | Controlling output length |
| [`examples/scripts/gemini/chat/streaming-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/streaming-tools.mjs) | Tool use with streaming |
| [`examples/scripts/gemini/chat/instructions.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/instructions.mjs) | System prompt instructions |
| [`examples/scripts/gemini/chat/params.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/params.mjs) | Custom model parameters |
| [`examples/scripts/gemini/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/streaming.mjs) | Advanced streaming |
| [`examples/scripts/gemini/chat/tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/tools.mjs) | Tool execution |
| [`examples/scripts/gemini/chat/events.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/chat/events.mjs) | Chat lifecycle events |
| [`examples/scripts/gemini/images/generate.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/images/generate.mjs) | Imagen 3 Generation |
| [`examples/scripts/gemini/discovery/models.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/discovery/models.mjs) | Listing available models |
| [`examples/scripts/gemini/safety/moderation.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/safety/moderation.mjs) | Content safety settings |
| [`examples/scripts/gemini/multimodal/transcribe.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/multimodal/transcribe.mjs) | Audio transcription |
| [`examples/scripts/gemini/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/multimodal/vision.mjs) | Image analysis |
| [`examples/scripts/gemini/multimodal/multi-image.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/gemini/multimodal/multi-image.mjs) | Multiple image analysis |
### Anthropic
| Example | Description |
| :--- | :--- |
| [`examples/scripts/anthropic/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/basic.mjs) | Claude 3.5 Sonnet Chat |
| [`examples/scripts/anthropic/chat/tool_use.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/tool_use.mjs) | Tool calling with Claude |
| [`examples/scripts/anthropic/multimodal/pdf.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/multimodal/pdf.mjs) | Native PDF analysis |
| [`examples/scripts/anthropic/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/multimodal/vision.mjs) | Image understanding |
| [`examples/scripts/anthropic/embeddings/create.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/embeddings/create.mjs) | Creating embeddings (Voyage AI) |
| [`examples/scripts/anthropic/chat/structured.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/structured.mjs) | Structured output (Tool use) |
| [`examples/scripts/anthropic/chat/usage.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/usage.mjs) | Token usage tracking |
| [`examples/scripts/anthropic/chat/parallel-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/parallel-tools.mjs) | Parallel tool execution |
| [`examples/scripts/anthropic/chat/max-tokens.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/max-tokens.mjs) | Controlling output length |
| [`examples/scripts/anthropic/chat/streaming-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/streaming-tools.mjs) | Tool use with streaming |
| [`examples/scripts/anthropic/chat/instructions.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/instructions.mjs) | System instructions |
| [`examples/scripts/anthropic/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/streaming.mjs) | Streaming chat |
| [`examples/scripts/anthropic/chat/events.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/chat/events.mjs) | Lifecycle events |
| [`examples/scripts/anthropic/images/generate.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/images/generate.mjs) | Image generation |
| [`examples/scripts/anthropic/discovery/models.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/discovery/models.mjs) | Listing models |
| [`examples/scripts/anthropic/safety/moderation.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/safety/moderation.mjs) | Content moderation |
| [`examples/scripts/anthropic/multimodal/transcribe.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/multimodal/transcribe.mjs) | Audio transcription |
| [`examples/scripts/anthropic/multimodal/multi-image.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/multimodal/multi-image.mjs) | Multiple image analysis |
| [`examples/scripts/anthropic/multimodal/files.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/anthropic/multimodal/files.mjs) | Multi-file context |
### Ollama Examples
| Example | Description |
| :--- | :--- |
| [`examples/scripts/ollama/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/ollama/chat/basic.mjs) | Local model chat |
| [`examples/scripts/ollama/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/ollama/chat/streaming.mjs) | Streaming local inference |
| [`examples/scripts/ollama/chat/tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/ollama/chat/tools.mjs) | Function calling with Llama 3.1 |
| [`examples/scripts/ollama/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/ollama/multimodal/vision.mjs) | Multi-modal local analysis |
| [`examples/scripts/ollama/embeddings/similarity.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/ollama/embeddings/similarity.mjs) | Vector similarity search |
| [`examples/scripts/ollama/discovery/list.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/ollama/discovery/list.mjs) | Inspecting local model library |
### DeepSeek Examples
| Example | Description |
| :--- | :--- |
| [`examples/scripts/deepseek/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/basic.mjs) | Basic chat with DeepSeek |
| [`examples/scripts/deepseek/chat/reasoning.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/reasoning.mjs) | DeepSeek-R1 reasoning tracking |
| [`examples/scripts/deepseek/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/streaming.mjs) | Streaming chat responses |
| [`examples/scripts/deepseek/chat/tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/tools.mjs) | Function calling with DeepSeek |
| [`examples/scripts/deepseek/chat/structured.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/structured.mjs) | Structured JSON output |
| [`examples/scripts/deepseek/embeddings/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/embeddings/basic.mjs) | Generating embeddings |
| [`examples/scripts/deepseek/chat/usage.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/usage.mjs) | Token usage tracking |
| [`examples/scripts/deepseek/chat/max-tokens.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/max-tokens.mjs) | Controlling output length |
| [`examples/scripts/deepseek/chat/streaming-tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/streaming-tools.mjs) | Tool use with streaming |
| [`examples/scripts/deepseek/chat/instructions.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/instructions.mjs) | System prompt instructions |
| [`examples/scripts/deepseek/chat/params.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/params.mjs) | Custom model parameters |
| [`examples/scripts/deepseek/chat/events.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/chat/events.mjs) | Lifecycle hooks |
| [`examples/scripts/deepseek/images/generate.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/images/generate.mjs) | Image generation |
| [`examples/scripts/deepseek/discovery/models.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/discovery/models.mjs) | Listing models |
| [`examples/scripts/deepseek/safety/moderation.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/safety/moderation.mjs) | Content moderation |
| [`examples/scripts/deepseek/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/deepseek/multimodal/vision.mjs) | Vision (V3) |
### Mistral Examples
| Example | Description |
| :--- | :--- |
| [`examples/scripts/mistral/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/chat/basic.mjs) | Basic chat with Mistral Large |
| [`examples/scripts/mistral/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/chat/streaming.mjs) | Streaming chat responses |
| [`examples/scripts/mistral/chat/reasoning.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/chat/reasoning.mjs) | Magistral reasoning with thinking |
| [`examples/scripts/mistral/chat/tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/chat/tools.mjs) | Function calling with Mistral |
| [`examples/scripts/mistral/chat/structured.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/chat/structured.mjs) | Structured output with Zod |
| [`examples/scripts/mistral/embeddings/create.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/embeddings/create.mjs) | Creating text embeddings |
| [`examples/scripts/mistral/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/multimodal/vision.mjs) | Image analysis with Pixtral |
| [`examples/scripts/mistral/multimodal/transcribe.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/multimodal/transcribe.mjs) | Audio transcription |
| [`examples/scripts/mistral/safety/moderation.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/safety/moderation.mjs) | Content moderation |
| [`examples/scripts/mistral/discovery/models.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/mistral/discovery/models.mjs) | Listing available models |
### OpenRouter Examples
| Example | Description |
| :--- | :--- |
| [`examples/scripts/openrouter/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/chat/basic.mjs) | Multi-model chat gateway |
| [`examples/scripts/openrouter/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/chat/streaming.mjs) | Unified streaming across 300+ models |
| [`examples/scripts/openrouter/chat/tools.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/chat/tools.mjs) | Cross-provider function calling |
| [`examples/scripts/openrouter/chat/reasoning.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/chat/reasoning.mjs) | Accessing DeepSeek & o1 reasoning |
| [`examples/scripts/openrouter/discovery/models.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/discovery/models.mjs) | Exploring the global model library |
| [`examples/scripts/openrouter/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/multimodal/vision.mjs) | Unified vision API for all models |
| [`examples/scripts/openrouter/embeddings/create.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/openrouter/embeddings/create.mjs) | Aggregated embedding services |
### xAI Examples
| Example | Description |
| :--- | :--- |
| [`examples/scripts/xai/chat/basic.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/xai/chat/basic.mjs) | Basic chat with Grok-3 |
| [`examples/scripts/xai/chat/streaming.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/xai/chat/streaming.mjs) | Streaming chat responses |
| [`examples/scripts/xai/chat/structured.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/xai/chat/structured.mjs) | Structured output with Zod schema |
| [`examples/scripts/xai/multimodal/vision.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/xai/multimodal/vision.mjs) | Image analysis with Grok Vision |
| [`examples/scripts/xai/images/generate.mjs`](https://github.com/node-llm/node-llm/blob/main/examples/scripts/xai/images/generate.mjs) | Image generation with Aurora |
----------------------------------------
# 📄 index.md
---
layout: landing
title: Home
nav_exclude: true
permalink: /
---
----------------------------------------
# 📄 models/available_models.md
---
layout: default
title: Available Models
nav_order: 5
has_children: false
permalink: /available-models
description: Browse AI models from every major provider. Always up-to-date, automatically generated.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
_Model information enriched by [models.dev](https://models.dev)._
## Last Updated
{: .d-inline-block }
2026-03-14
{: .label .label-green }
---
## Models by Provider
### OpenAI (163)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `gpt-5.4` | 1.1M | 128k | In: $2.50, Out: $15.00, Cache: $0.25 |
| `gpt-5.4-pro` | 1.1M | 128k | In: $30.00, Out: $180.00 |
| `gpt-4.1` | 1.0M | 32.768k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `gpt-4.1` | 1.0M | 32.768k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `gpt-4.1-2025-04-14` | 1.0M | 32.768k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `gpt-4.1-mini` | 1.0M | 32.768k | In: $0.40, Out: $1.60, Cache: $0.10 |
| `gpt-4.1-mini` | 1.0M | 32.768k | In: $0.40, Out: $1.60, Cache: $0.10 |
| `gpt-4.1-mini-2025-04-14` | 1.0M | 32.768k | In: $0.40, Out: $1.60, Cache: $0.10 |
| `gpt-4.1-nano` | 1.0M | 32.768k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gpt-4.1-nano` | 1.0M | 32.768k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gpt-4.1-nano-2025-04-14` | 1.0M | 32.768k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gpt-5` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5-2025-08-07` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5-chat-latest` | 400k | 128k | In: $1.25, Out: $10.00 |
| `gpt-5-codex` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5-codex` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5-mini` | 400k | 128k | In: $0.25, Out: $2.00, Cache: $0.03 |
| `gpt-5-mini` | 400k | 128k | In: $0.25, Out: $2.00, Cache: $0.03 |
| `gpt-5-mini-2025-08-07` | 400k | 128k | In: $0.25, Out: $2.00, Cache: $0.03 |
| `gpt-5-nano` | 400k | 128k | In: $0.05, Out: $0.40, Cache: $0.01 |
| `gpt-5-nano` | 400k | 128k | In: $0.05, Out: $0.40, Cache: $0.01 |
| `gpt-5-nano-2025-08-07` | 400k | 128k | In: $0.05, Out: $0.40, Cache: $0.01 |
| `gpt-5-pro` | 400k | 272k | In: $15.00, Out: $120.00 |
| `gpt-5-pro` | 400k | 272k | In: $15.00, Out: $120.00 |
| `gpt-5-pro-2025-10-06` | 400k | 272k | In: $15.00, Out: $120.00 |
| `gpt-5.1` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-2025-11-13` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-codex` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-codex` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-codex-max` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-codex-mini` | 400k | 128k | In: $0.25, Out: $2.00, Cache: $0.03 |
| `gpt-5.1-codex-mini` | 400k | 128k | In: $0.25, Out: $2.00, Cache: $0.03 |
| `gpt-5.2` | 400k | 128k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `gpt-5.2-codex` | 400k | 128k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `gpt-5.2-pro` | 400k | 128k | In: $21.00, Out: $168.00 |
| `gpt-5.3-codex` | 400k | 128k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `codex-mini-latest` | 200k | 100k | In: $1.50, Out: $6.00, Cache: $0.38 |
| `codex-mini-latest` | 200k | 100k | In: $1.50, Out: $6.00, Cache: $0.38 |
| `o1` | 200k | 100k | In: $15.00, Out: $60.00, Cache: $7.50 |
| `o1` | 200k | 100k | In: $15.00, Out: $60.00, Cache: $7.50 |
| `o1-2024-12-17` | 200k | 100k | In: $15.00, Out: $60.00, Cache: $7.50 |
| `o1-pro` | 200k | 100k | In: $150.00, Out: $600.00 |
| `o1-pro` | 200k | 100k | In: $150.00, Out: $600.00 |
| `o1-pro-2025-03-19` | 200k | 100k | In: $150.00, Out: $600.00 |
| `o3` | 200k | 100k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `o3` | 200k | 100k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `o3-2025-04-16` | 200k | 100k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `o3-deep-research` | 200k | 100k | In: $10.00, Out: $40.00, Cache: $2.50 |
| `o3-deep-research` | 200k | 100k | In: $10.00, Out: $40.00, Cache: $2.50 |
| `o3-deep-research-2025-06-26` | 200k | 100k | In: $10.00, Out: $40.00, Cache: $2.50 |
| `o3-mini` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.55 |
| `o3-mini` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.55 |
| `o3-mini-2025-01-31` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.55 |
| `o3-pro` | 200k | 100k | In: $20.00, Out: $80.00 |
| `o3-pro` | 200k | 100k | In: $20.00, Out: $80.00 |
| `o3-pro-2025-06-10` | 200k | 100k | In: $20.00, Out: $80.00 |
| `o4-mini` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.28 |
| `o4-mini` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.28 |
| `o4-mini-2025-04-16` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.28 |
| `o4-mini-deep-research` | 200k | 100k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `o4-mini-deep-research` | 200k | 100k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `o4-mini-deep-research-2025-06-26` | 200k | 100k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `gpt-oss-120b` | 131.072k | 131.072k | - |
| `gpt-oss-20b` | 131.072k | 131.072k | - |
| `chatgpt-4o-latest` | 128k | 16.384k | In: $5.00, Out: $15.00 |
| `gpt-4-turbo` | 128k | 4.096k | In: $10.00, Out: $30.00 |
| `gpt-4-turbo` | 128k | 4.096k | In: $10.00, Out: $30.00 |
| `gpt-4-turbo-2024-04-09` | 128k | 4.096k | In: $10.00, Out: $30.00 |
| `gpt-4-turbo-preview` | 128k | 4.096k | In: $10.00, Out: $30.00 |
| `gpt-4.5-preview` | 128k | 16.384k | In: $75.00, Out: $150.00, Cache: $37.50 |
| `gpt-4.5-preview-2025-02-27` | 128k | 16.384k | In: $75.00, Out: $150.00, Cache: $37.50 |
| `gpt-4o` | 128k | 16.384k | In: $2.50, Out: $10.00, Cache: $1.25 |
| `gpt-4o` | 128k | 16.384k | In: $2.50, Out: $10.00, Cache: $1.25 |
| `gpt-4o-2023-01-01` | 128k | 16.384k | In: $2.50, Out: $10.00, Cache: $1.25 |
| `gpt-4o-2024-05-13` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-2024-05-13` | 128k | 4.096k | In: $5.00, Out: $15.00 |
| `gpt-4o-2024-08-06` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-2024-08-06` | 128k | 16.384k | In: $2.50, Out: $10.00, Cache: $1.25 |
| `gpt-4o-2024-11-20` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-2024-11-20` | 128k | 16.384k | In: $2.50, Out: $10.00, Cache: $1.25 |
| `gpt-4o-audio-preview` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-audio-preview-2024-10-01` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-audio-preview-2024-12-17` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-audio-preview-2025-06-03` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-mini` | 128k | 16.384k | In: $0.15, Out: $0.60, Cache: $0.07 |
| `gpt-4o-mini` | 128k | 16.384k | In: $0.15, Out: $0.60, Cache: $0.08 |
| `gpt-4o-mini-2024-07-18` | 128k | 16.384k | In: $0.15, Out: $0.60, Cache: $0.07 |
| `gpt-4o-mini-audio-preview` | 128k | 16.384k | In: $0.15, Out: $0.60 |
| `gpt-4o-mini-audio-preview-2024-12-17` | 128k | 16.384k | In: $0.15, Out: $0.60 |
| `gpt-4o-mini-realtime-preview-2024-12-17` | 128k | 4.096k | In: $0.60, Out: $2.40 |
| `gpt-4o-mini-search-preview` | 128k | 16.384k | In: $0.15, Out: $0.60 |
| `gpt-4o-mini-search-preview-2025-03-11` | 128k | 16.384k | In: $0.15, Out: $0.60 |
| `gpt-4o-realtime-preview-2024-10-01` | 128k | 4.096k | In: $5.00, Out: $20.00 |
| `gpt-4o-realtime-preview-2024-12-17` | 128k | 4.096k | In: $5.00, Out: $20.00 |
| `gpt-4o-realtime-preview-2025-06-03` | 128k | 4.096k | In: $5.00, Out: $20.00 |
| `gpt-4o-search-preview` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-4o-search-preview-2025-03-11` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-5-chat-latest` | 128k | 16.384k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5-search-api` | 128k | 400k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5-search-api-2025-10-14` | 128k | 400k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-chat-latest` | 128k | 16.384k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.1-chat-latest` | 128k | 16.384k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gpt-5.2-chat-latest` | 128k | 16.384k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `gpt-5.3-codex-spark` | 128k | 32k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `gpt-audio` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-audio-2025-08-28` | 128k | 16.384k | In: $2.50, Out: $10.00 |
| `gpt-audio-mini` | 128k | 16.384k | In: $0.60, Out: $2.40 |
| `gpt-audio-mini-2025-10-06` | 128k | 16.384k | In: $0.60, Out: $2.40 |
| `o1-mini` | 128k | 65.536k | In: $1.10, Out: $4.40, Cache: $0.55 |
| `o1-mini` | 128k | 65.536k | In: $1.10, Out: $4.40, Cache: $0.55 |
| `o1-mini-2024-09-12` | 128k | 65.536k | In: $1.10, Out: $4.40, Cache: $0.55 |
| `o1-preview` | 128k | 32.768k | In: $15.00, Out: $60.00, Cache: $7.50 |
| `o1-preview` | 128k | 32.768k | In: $15.00, Out: $60.00, Cache: $7.50 |
| `o1-preview-2024-09-12` | 128k | 32.768k | In: $15.00, Out: $60.00, Cache: $7.50 |
| `gpt-4o-realtime-preview` | 32k | 4.096k | In: $5.00, Out: $20.00, Cache: $2.50 |
| `gpt-realtime` | 32k | 4.096k | In: $4.00, Out: $16.00, Cache: $0.50 |
| `gpt-realtime-2025-08-28` | 32k | 4.096k | In: $4.00, Out: $16.00, Cache: $0.50 |
| `gpt-realtime-mini` | 32k | 4.096k | In: $0.60, Out: $2.40, Cache: $0.06 |
| `gpt-realtime-mini-2025-10-06` | 32k | 4.096k | In: $0.60, Out: $2.40, Cache: $0.06 |
| `gpt-3.5-turbo` | 16.385k | 4.096k | In: $0.50, Out: $1.50 |
| `gpt-3.5-turbo` | 16.385k | 4.096k | In: $0.50, Out: $1.50, Cache: $1.25 |
| `gpt-3.5-turbo-0125` | 16.385k | 4.096k | In: $0.50, Out: $1.50 |
| `gpt-3.5-turbo-1106` | 16.385k | 4.096k | In: $0.50, Out: $1.50 |
| `gpt-3.5-turbo-16k` | 16.385k | 4.096k | In: $0.50, Out: $1.50 |
| `gpt-3.5-turbo-instruct` | 16.385k | 4.096k | In: $0.50, Out: $1.50 |
| `gpt-3.5-turbo-instruct-0914` | 16.385k | 4.096k | In: $0.50, Out: $1.50 |
| `gpt-4o-mini-realtime-preview` | 16k | 4.096k | In: $0.60, Out: $2.40, Cache: $0.30 |
| `gpt-4o-mini-transcribe` | 16k | 2k | In: $1.25, Out: $5.00 |
| `gpt-4o-transcribe` | 16k | 2k | In: $2.50, Out: $10.00 |
| `gpt-4o-transcribe-diarize` | 16k | 2k | In: $2.50, Out: $10.00 |
| `computer-use-preview` | 8.192k | 1.024k | In: $3.00, Out: $12.00 |
| `computer-use-preview-2025-03-11` | 8.192k | 1.024k | In: $3.00, Out: $12.00 |
| `gpt-4` | 8.192k | 8.192k | In: $30.00, Out: $60.00 |
| `gpt-4` | 8.192k | 8.192k | In: $30.00, Out: $60.00 |
| `gpt-4-0613` | 8.192k | 8.192k | In: $30.00, Out: $60.00 |
| `text-embedding-ada-002` | 8.192k | 1.536k | In: $0.10 |
| `text-embedding-3-large` | 8.191k | 3.072k | In: $0.13 |
| `text-embedding-3-small` | 8.191k | 1.536k | In: $0.02 |
| `gpt-4-0125-preview` | 4.096k | 16.384k | In: $0.50, Out: $1.50 |
| `gpt-4-1106-preview` | 4.096k | 16.384k | In: $0.50, Out: $1.50 |
| `gpt-4o-mini-tts` | 2k | - | In: $0.60, Out: $12.00 |
| `babbage-002` | - | 16.384k | In: $0.40, Out: $0.40 |
| `dall-e-2` | - | - | - |
| `dall-e-3` | - | - | - |
| `davinci-002` | - | 16.384k | In: $2.00, Out: $2.00 |
| `gpt-image-1` | - | - | In: $5.00, Out: $40.00, Cache: $1.25 |
| `gpt-image-1-mini` | - | - | In: $2.00, Out: $8.00, Cache: $0.20 |
| `omni-moderation-2024-09-26` | - | - | - |
| `omni-moderation-latest` | - | - | - |
| `sora-2` | - | - | In: $0.10 |
| `sora-2-pro` | - | - | - |
| `text-embedding-3-large` | - | - | In: $0.13 |
| `text-embedding-3-small` | - | - | In: $0.02 |
| `text-embedding-ada-002` | - | - | In: $0.10 |
| `text-moderation-latest` | - | 32.768k | - |
| `text-moderation-stable` | - | 32.768k | - |
| `tts-1` | - | - | Out: $15.00 |
| `tts-1-1106` | - | - | In: $15.00, Out: $15.00 |
| `tts-1-hd` | - | - | Out: $30.00 |
| `tts-1-hd-1106` | - | - | In: $30.00, Out: $30.00 |
| `whisper-1` | - | - | In: $0.01 |
### Anthropic (35)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `claude-opus-4-6` | 1.0M | 128k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `claude-sonnet-4-6` | 1.0M | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-3-5-haiku-20241022` | 200k | 8.192k | In: $0.80, Out: $4.00 |
| `claude-3-5-haiku-20241022` | 200k | 8.192k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `claude-3-5-haiku-latest` | 200k | 8.192k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `claude-3-5-sonnet-20240620` | 200k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-3-5-sonnet-20241022` | 200k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-3-7-sonnet-20250219` | 200k | 8.192k | In: $3.00, Out: $15.00 |
| `claude-3-7-sonnet-20250219` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-3-7-sonnet-latest` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-3-haiku-20240307` | 200k | 4.096k | In: $0.25, Out: $1.25 |
| `claude-3-haiku-20240307` | 200k | 4.096k | In: $0.25, Out: $1.25, Cache: $0.03 |
| `claude-3-opus-20240229` | 200k | 4.096k | In: $15.00, Out: $75.00 |
| `claude-3-opus-20240229` | 200k | 4.096k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `claude-3-sonnet-20240229` | 200k | 4.096k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-haiku-4-5` | 200k | 64k | In: $1.00, Out: $5.00 |
| `claude-haiku-4-5` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `claude-haiku-4-5-20251001` | 200k | 64k | In: $1.00, Out: $5.00 |
| `claude-haiku-4-5-20251001` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `claude-opus-4-0` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `claude-opus-4-1` | 200k | 32k | In: $15.00, Out: $75.00 |
| `claude-opus-4-1` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `claude-opus-4-1-20250805` | 200k | 32k | In: $15.00, Out: $75.00 |
| `claude-opus-4-1-20250805` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `claude-opus-4-20250514` | 200k | 4.096k | In: $3.00, Out: $15.00 |
| `claude-opus-4-20250514` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `claude-opus-4-5` | 200k | 64k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `claude-opus-4-5-20251101` | 200k | 64k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `claude-sonnet-4-0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-sonnet-4-20250514` | 200k | 4.096k | In: $3.00, Out: $15.00 |
| `claude-sonnet-4-20250514` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-sonnet-4-5` | 200k | 64k | In: $3.00, Out: $15.00 |
| `claude-sonnet-4-5` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-sonnet-4-5-20250929` | 200k | 64k | In: $3.00, Out: $15.00 |
| `claude-sonnet-4-5-20250929` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
### Gemini (107)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `gemini-2.0-flash` | 1.0M | 8.192k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.0-flash` | 1.0M | 8.192k | In: $0.15, Out: $0.60, Cache: $0.03 |
| `gemini-2.0-flash` | 1.0M | 8.192k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.0-flash-001` | 1.0M | 8.192k | In: $0.10, Out: $0.40 |
| `gemini-2.0-flash-exp` | 1.0M | 8.192k | In: $0.10, Out: $0.40 |
| `gemini-2.0-flash-exp-image-generation` | 1.0M | 8.192k | In: $0.10, Out: $0.40 |
| `gemini-2.0-flash-lite` | 1.0M | 8.192k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.0-flash-lite` | 1.0M | 8.192k | In: $0.07, Out: $0.30 |
| `gemini-2.0-flash-lite` | 1.0M | 8.192k | In: $0.07, Out: $0.30 |
| `gemini-2.0-flash-lite-001` | 1.0M | 8.192k | In: $0.07, Out: $0.30 |
| `gemini-2.0-flash-lite-preview` | 1.0M | 8.192k | In: $0.07, Out: $0.30 |
| `gemini-2.0-flash-lite-preview-02-05` | 1.0M | 8.192k | In: $0.07, Out: $0.30 |
| `gemini-2.0-flash-thinking-exp` | 1.0M | 65.536k | In: $0.10, Out: $0.40 |
| `gemini-2.0-flash-thinking-exp-01-21` | 1.0M | 65.536k | In: $0.10, Out: $0.40 |
| `gemini-2.0-flash-thinking-exp-1219` | 1.0M | 65.536k | In: $0.10, Out: $0.40 |
| `gemini-2.0-pro-exp` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.0-pro-exp-02-05` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.03 |
| `gemini-2.5-flash` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-2.5-flash` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-2.5-flash-lite` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.03 |
| `gemini-2.5-flash-lite` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-lite` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-lite-preview-06-17` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-lite-preview-09-2025` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash-lite-preview-09-2025` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-lite-preview-09-2025` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-preview-04-17` | 1.0M | 65.536k | In: $0.15, Out: $0.60, Cache: $0.04 |
| `gemini-2.5-flash-preview-04-17` | 1.0M | 65.536k | In: $0.15, Out: $0.60, Cache: $0.04 |
| `gemini-2.5-flash-preview-05-20` | 1.0M | 65.536k | In: $0.15, Out: $0.60, Cache: $0.04 |
| `gemini-2.5-flash-preview-05-20` | 1.0M | 65.536k | In: $0.15, Out: $0.60, Cache: $0.04 |
| `gemini-2.5-flash-preview-09-2025` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash-preview-09-2025` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-2.5-flash-preview-09-2025` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-2.5-pro` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `gemini-2.5-pro` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `gemini-2.5-pro` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `gemini-2.5-pro-preview-03-25` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.5-pro-preview-05-06` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.5-pro-preview-05-06` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `gemini-2.5-pro-preview-05-06` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `gemini-2.5-pro-preview-06-05` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-2.5-pro-preview-06-05` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `gemini-2.5-pro-preview-06-05` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `gemini-3-flash-preview` | 1.0M | 65.536k | In: $0.50, Out: $3.00, Cache: $0.05 |
| `gemini-3-flash-preview` | 1.0M | 65.536k | In: $0.50, Out: $3.00, Cache: $0.05 |
| `gemini-3-pro-preview` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-3-pro-preview` | 1.0M | 65.536k | In: $2.00, Out: $12.00, Cache: $0.20 |
| `gemini-3.1-flash-lite-preview` | 1.0M | 65.536k | In: $0.25, Out: $1.50, Cache: $0.03 |
| `gemini-3.1-pro-preview` | 1.0M | 65.536k | In: $2.00, Out: $12.00, Cache: $0.20 |
| `gemini-3.1-pro-preview` | 1.0M | 65.536k | In: $2.00, Out: $12.00, Cache: $0.20 |
| `gemini-3.1-pro-preview-customtools` | 1.0M | 65.536k | In: $2.00, Out: $12.00, Cache: $0.20 |
| `gemini-3.1-pro-preview-customtools` | 1.0M | 65.536k | In: $2.00, Out: $12.00, Cache: $0.20 |
| `gemini-exp-1206` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-flash-latest` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-flash-latest` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-flash-latest` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-flash-lite-latest` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-flash-lite-latest` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-flash-lite-latest` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-pro-latest` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-robotics-er-1.5-preview` | 1.0M | 65.536k | In: $0.07, Out: $0.30 |
| `learnlm-2.0-flash-experimental` | 1.0M | 32.768k | In: $0.07, Out: $0.30 |
| `gemini-1.5-flash` | 1.0M | 8.192k | In: $0.07, Out: $0.30, Cache: $0.02 |
| `gemini-1.5-flash-8b` | 1.0M | 8.192k | In: $0.04, Out: $0.15, Cache: $0.01 |
| `gemini-1.5-pro` | 1.0M | 8.192k | In: $1.25, Out: $5.00, Cache: $0.31 |
| `gemini-3-pro-preview` | 1.0M | 64k | In: $2.00, Out: $12.00, Cache: $0.20 |
| `meta/llama-4-maverick-17b-128e-instruct-maas` | 524.288k | 8.192k | In: $0.35, Out: $1.15 |
| `qwen/qwen3-235b-a22b-instruct-2507-maas` | 262.144k | 16.384k | In: $0.22, Out: $0.88 |
| `zai-org/glm-5-maas` | 202.752k | 131.072k | In: $1.00, Out: $3.20, Cache: $0.10 |
| `zai-org/glm-4.7-maas` | 200k | 128k | In: $0.60, Out: $2.20 |
| `deepseek-ai/deepseek-v3.1-maas` | 163.84k | 32.768k | In: $0.60, Out: $1.70 |
| `gemini-2.5-computer-use-preview-10-2025` | 131.072k | 65.536k | In: $0.07, Out: $0.30 |
| `gemini-3.1-flash-image-preview` | 131.072k | 32.768k | In: $0.25, Out: $60.00 |
| `gemini-live-2.5-flash-preview-native-audio` | 131.072k | 65.536k | In: $0.50, Out: $2.00 |
| `gemma-3-27b-it` | 131.072k | 8.192k | In: $0.07, Out: $0.30 |
| `openai/gpt-oss-120b-maas` | 131.072k | 32.768k | In: $0.09, Out: $0.36 |
| `openai/gpt-oss-20b-maas` | 131.072k | 32.768k | In: $0.07, Out: $0.25 |
| `gemini-live-2.5-flash` | 128k | 8k | In: $0.50, Out: $2.00 |
| `meta/llama-3.3-70b-instruct-maas` | 128k | 8.192k | In: $0.72, Out: $0.72 |
| `gemini-2.5-flash-lite-preview-06-17` | 65.536k | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-image` | 32.768k | 32.768k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash-image` | 32.768k | 32.768k | In: $0.30, Out: $30.00, Cache: $0.07 |
| `gemini-2.5-flash-image-preview` | 32.768k | 32.768k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash-image-preview` | 32.768k | 32.768k | In: $0.30, Out: $30.00, Cache: $0.07 |
| `gemma-3-12b-it` | 32.768k | 8.192k | In: $0.07, Out: $0.30 |
| `gemma-3-1b-it` | 32.768k | 8.192k | In: $0.07, Out: $0.30 |
| `gemma-3-4b-it` | 32.768k | 8.192k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash-preview-tts` | 8.192k | 16.384k | In: $0.07, Out: $0.30 |
| `gemini-2.5-pro-preview-tts` | 8.192k | 16.384k | In: $0.07, Out: $0.30 |
| `gemini-embedding-exp` | 8.192k | 1 | In: $0.00, Out: $0.00 |
| `gemini-embedding-exp-03-07` | 8.192k | 1 | In: $0.00, Out: $0.00 |
| `gemma-3n-e2b-it` | 8.192k | 2.048k | In: $0.07, Out: $0.30 |
| `gemma-3n-e4b-it` | 8.192k | 2.048k | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash-preview-tts` | 8k | 16k | In: $0.50, Out: $10.00 |
| `gemini-2.5-pro-preview-tts` | 8k | 16k | In: $1.00, Out: $20.00 |
| `aqa` | 7.168k | 1.024k | - |
| `embedding-001` | 2.048k | 1 | - |
| `gemini-embedding-001` | 2.048k | 1 | - |
| `gemini-embedding-001` | 2.048k | 3.072k | In: $0.15 |
| `gemini-embedding-001` | 2.048k | 3.072k | In: $0.15 |
| `text-embedding-004` | 2.048k | 1 | - |
| `embedding-gecko-001` | 1.024k | 1 | - |
| `imagen-4.0-generate-001` | 480 | 8.192k | - |
| `imagen-4.0-generate-preview-06-06` | 480 | 8.192k | - |
| `imagen-4.0-ultra-generate-001` | 480 | 8.192k | - |
| `imagen-4.0-ultra-generate-preview-06-06` | 480 | 8.192k | - |
### DeepSeek (2)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `deepseek-chat` | 128k | 8.192k | In: $0.28, Out: $0.42, Cache: $0.03 |
| `deepseek-reasoner` | 128k | 64k | In: $0.28, Out: $0.42, Cache: $0.03 |
### OpenRouter (198)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `x-ai/grok-4-fast` | 2.0M | 30k | In: $0.20, Out: $0.50, Cache: $0.05 |
| `x-ai/grok-4.1-fast` | 2.0M | 30k | In: $0.20, Out: $0.50, Cache: $0.05 |
| `x-ai/grok-4.20-beta` | 2.0M | 30k | In: $2.00, Out: $6.00, Cache: $0.20 |
| `x-ai/grok-4.20-multi-agent-beta` | 2.0M | 30k | In: $2.00, Out: $6.00, Cache: $0.20 |
| `openrouter/sherlock-dash-alpha` | 1.8M | - | - |
| `openrouter/sherlock-think-alpha` | 1.8M | - | - |
| `google/gemini-3-pro-preview` | 1.1M | 66k | In: $2.00, Out: $12.00 |
| `openai/gpt-5.4` | 1.1M | 128k | In: $2.50, Out: $15.00, Cache: $0.25 |
| `openai/gpt-5.4-pro` | 1.1M | 128k | In: $30.00, Out: $180.00, Cache: $30.00 |
| `google/gemini-2.0-flash-001` | 1.0M | 8.192k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `google/gemini-2.0-flash-exp:free` | 1.0M | 1.0M | - |
| `google/gemini-2.5-flash` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.04 |
| `google/gemini-2.5-flash-lite` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `google/gemini-2.5-flash-lite-preview-09-2025` | 1.0M | 65.536k | In: $0.10, Out: $0.40, Cache: $0.03 |
| `google/gemini-2.5-flash-preview-09-2025` | 1.0M | 65.536k | In: $0.30, Out: $2.50, Cache: $0.03 |
| `google/gemini-2.5-pro` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `google/gemini-2.5-pro-preview-05-06` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `google/gemini-2.5-pro-preview-06-05` | 1.0M | 65.536k | In: $1.25, Out: $10.00, Cache: $0.31 |
| `google/gemini-3-flash-preview` | 1.0M | 65.536k | In: $0.50, Out: $3.00, Cache: $0.05 |
| `google/gemini-3.1-flash-lite-preview` | 1.0M | 65.536k | In: $0.25, Out: $1.50, Cache: $0.03 |
| `google/gemini-3.1-pro-preview` | 1.0M | 65.536k | In: $2.00, Out: $12.00 |
| `google/gemini-3.1-pro-preview-customtools` | 1.0M | 65.536k | In: $2.00, Out: $12.00 |
| `openrouter/hunter-alpha` | 1.0M | 64k | - |
| `openai/gpt-4.1` | 1.0M | 32.768k | In: $2.00, Out: $8.00, Cache: $0.50 |
| `openai/gpt-4.1-mini` | 1.0M | 32.768k | In: $0.40, Out: $1.60, Cache: $0.10 |
| `anthropic/claude-opus-4.6` | 1.0M | 128k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic/claude-sonnet-4.5` | 1.0M | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-sonnet-4.6` | 1.0M | 128k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `minimax/minimax-01` | 1.0M | 1.0M | In: $0.20, Out: $1.10 |
| `minimax/minimax-m1` | 1.0M | 40k | In: $0.40, Out: $2.20 |
| `qwen/qwen3.5-plus-02-15` | 1.0M | 65.536k | In: $0.40, Out: $2.40 |
| `openai/gpt-5` | 400k | 128k | In: $1.25, Out: $10.00 |
| `openai/gpt-5-chat` | 400k | 128k | In: $1.25, Out: $10.00 |
| `openai/gpt-5-codex` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `openai/gpt-5-image` | 400k | 128k | In: $5.00, Out: $10.00, Cache: $1.25 |
| `openai/gpt-5-mini` | 400k | 128k | In: $0.25, Out: $2.00 |
| `openai/gpt-5-nano` | 400k | 128k | In: $0.05, Out: $0.40 |
| `openai/gpt-5-pro` | 400k | 272k | In: $15.00, Out: $120.00 |
| `openai/gpt-5.1` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `openai/gpt-5.1-codex` | 400k | 128k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `openai/gpt-5.1-codex-max` | 400k | 128k | In: $1.10, Out: $9.00, Cache: $0.11 |
| `openai/gpt-5.1-codex-mini` | 400k | 100k | In: $0.25, Out: $2.00, Cache: $0.03 |
| `openai/gpt-5.2` | 400k | 128k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `openai/gpt-5.2-codex` | 400k | 128k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `openai/gpt-5.2-pro` | 400k | 128k | In: $21.00, Out: $168.00 |
| `openai/gpt-5.3-codex` | 400k | 128k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `mistralai/devstral-2512` | 262.144k | 262.144k | In: $0.15, Out: $0.60 |
| `mistralai/devstral-2512:free` | 262.144k | 262.144k | - |
| `mistralai/mistral-medium-3.1` | 262.144k | 262.144k | In: $0.40, Out: $2.00 |
| `moonshotai/kimi-k2-0905` | 262.144k | 16.384k | In: $0.60, Out: $2.50 |
| `moonshotai/kimi-k2-0905:exacto` | 262.144k | 16.384k | In: $0.60, Out: $2.50 |
| `moonshotai/kimi-k2-thinking` | 262.144k | 262.144k | In: $0.60, Out: $2.50, Cache: $0.15 |
| `moonshotai/kimi-k2.5` | 262.144k | 262.144k | In: $0.60, Out: $3.00, Cache: $0.10 |
| `openrouter/healer-alpha` | 262.144k | 64k | - |
| `qwen/qwen3-235b-a22b-07-25` | 262.144k | 131.072k | In: $0.15, Out: $0.85 |
| `qwen/qwen3-235b-a22b-07-25:free` | 262.144k | 131.072k | - |
| `qwen/qwen3-235b-a22b-thinking-2507` | 262.144k | 81.92k | In: $0.08, Out: $0.31 |
| `qwen/qwen3-coder` | 262.144k | 66.536k | In: $0.30, Out: $1.20 |
| `qwen/qwen3-coder:free` | 262.144k | 66.536k | - |
| `qwen/qwen3-max` | 262.144k | 32.768k | In: $1.20, Out: $6.00 |
| `qwen/qwen3-next-80b-a3b-instruct` | 262.144k | 262.144k | In: $0.14, Out: $1.40 |
| `qwen/qwen3-next-80b-a3b-instruct:free` | 262.144k | 262.144k | - |
| `qwen/qwen3-next-80b-a3b-thinking` | 262.144k | 262.144k | In: $0.14, Out: $1.40 |
| `qwen/qwen3.5-397b-a17b` | 262.144k | 65.536k | In: $0.60, Out: $3.60 |
| `xiaomi/mimo-v2-flash` | 262.144k | 65.536k | In: $0.10, Out: $0.30, Cache: $0.01 |
| `qwen/qwen3-30b-a3b-instruct-2507` | 262k | 262k | In: $0.20, Out: $0.80 |
| `qwen/qwen3-30b-a3b-thinking-2507` | 262k | 262k | In: $0.20, Out: $0.80 |
| `kwaipilot/kat-coder-pro:free` | 256k | 65.536k | - |
| `mistralai/codestral-2508` | 256k | 256k | In: $0.30, Out: $0.90 |
| `nvidia/nemotron-3-nano-30b-a3b:free` | 256k | 256k | - |
| `stepfun/step-3.5-flash` | 256k | 256k | In: $0.10, Out: $0.30, Cache: $0.02 |
| `stepfun/step-3.5-flash:free` | 256k | 256k | - |
| `x-ai/grok-4` | 256k | 64k | In: $3.00, Out: $15.00, Cache: $0.75 |
| `x-ai/grok-code-fast-1` | 256k | 10k | In: $0.20, Out: $1.50, Cache: $0.02 |
| `minimax/minimax-m2.1` | 204.8k | 131.072k | In: $0.30, Out: $1.20 |
| `minimax/minimax-m2.5` | 204.8k | 131.072k | In: $0.30, Out: $1.20, Cache: $0.03 |
| `z-ai/glm-4.7` | 204.8k | 131.072k | In: $0.60, Out: $2.20, Cache: $0.11 |
| `z-ai/glm-5` | 202.752k | 131k | In: $1.00, Out: $3.20, Cache: $0.20 |
| `anthropic/claude-3.5-haiku` | 200k | 8.192k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic/claude-3.7-sonnet` | 200k | 128k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic/claude-haiku-4.5` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic/claude-opus-4` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic/claude-opus-4.1` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic/claude-opus-4.5` | 200k | 32k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic/claude-sonnet-4` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `openai/o4-mini` | 200k | 100k | In: $1.10, Out: $4.40, Cache: $0.28 |
| `openrouter/free` | 200k | 8k | - |
| `z-ai/glm-4.6` | 200k | 128k | In: $0.60, Out: $2.20, Cache: $0.11 |
| `z-ai/glm-4.6:exacto` | 200k | 128k | In: $0.60, Out: $1.90, Cache: $0.11 |
| `z-ai/glm-4.7-flash` | 200k | 65.535k | In: $0.07, Out: $0.40 |
| `minimax/minimax-m2` | 196.6k | 118k | In: $0.28, Out: $1.15, Cache: $0.28 |
| `deepseek/deepseek-chat-v3.1` | 163.84k | 163.84k | In: $0.20, Out: $0.80 |
| `deepseek/deepseek-r1-0528:free` | 163.84k | 163.84k | - |
| `deepseek/deepseek-r1:free` | 163.84k | 163.84k | - |
| `deepseek/deepseek-v3-base:free` | 163.84k | 163.84k | - |
| `deepseek/deepseek-v3.2` | 163.84k | 65.536k | In: $0.28, Out: $0.40 |
| `deepseek/deepseek-v3.2-speciale` | 163.84k | 65.536k | In: $0.27, Out: $0.41 |
| `microsoft/mai-ds-r1:free` | 163.84k | 163.84k | - |
| `tngtech/deepseek-r1t2-chimera:free` | 163.84k | 163.84k | - |
| `tngtech/tng-r1t-chimera:free` | 163.84k | 163.84k | - |
| `qwen/qwen3-coder-30b-a3b-instruct` | 160k | 65.536k | In: $0.07, Out: $0.27 |
| `arcee-ai/trinity-large-preview:free` | 131.072k | 131.072k | - |
| `arcee-ai/trinity-mini:free` | 131.072k | 131.072k | - |
| `deepseek/deepseek-r1-0528-qwen3-8b:free` | 131.072k | 131.072k | - |
| `deepseek/deepseek-v3.1-terminus` | 131.072k | 65.536k | In: $0.27, Out: $1.00 |
| `deepseek/deepseek-v3.1-terminus:exacto` | 131.072k | 65.536k | In: $0.27, Out: $1.00 |
| `google/gemma-3-12b-it` | 131.072k | 131.072k | In: $0.03, Out: $0.10 |
| `google/gemma-3-27b-it:free` | 131.072k | 8.192k | - |
| `liquid/lfm-2.5-1.2b-instruct:free` | 131.072k | 32.768k | - |
| `liquid/lfm-2.5-1.2b-thinking:free` | 131.072k | 32.768k | - |
| `meta-llama/llama-3.1-405b-instruct:free` | 131.072k | 131.072k | - |
| `meta-llama/llama-3.2-11b-vision-instruct` | 131.072k | 8.192k | - |
| `meta-llama/llama-3.2-3b-instruct:free` | 131.072k | 131.072k | - |
| `meta-llama/llama-3.3-70b-instruct:free` | 131.072k | 131.072k | - |
| `mistralai/devstral-medium-2507` | 131.072k | 131.072k | In: $0.40, Out: $2.00 |
| `mistralai/devstral-small-2507` | 131.072k | 131.072k | In: $0.10, Out: $0.30 |
| `mistralai/mistral-medium-3` | 131.072k | 131.072k | In: $0.40, Out: $2.00 |
| `mistralai/mistral-nemo:free` | 131.072k | 131.072k | - |
| `moonshotai/kimi-dev-72b:free` | 131.072k | 131.072k | - |
| `moonshotai/kimi-k2` | 131.072k | 32.768k | In: $0.55, Out: $2.20 |
| `nousresearch/deephermes-3-llama-3-8b-preview` | 131.072k | 8.192k | - |
| `nousresearch/hermes-3-llama-3.1-405b:free` | 131.072k | 131.072k | - |
| `nousresearch/hermes-4-405b` | 131.072k | 131.072k | In: $1.00, Out: $3.00 |
| `nousresearch/hermes-4-70b` | 131.072k | 131.072k | In: $0.13, Out: $0.40 |
| `nvidia/nemotron-nano-9b-v2` | 131.072k | 131.072k | In: $0.04, Out: $0.16 |
| `openai/gpt-oss-120b` | 131.072k | 32.768k | In: $0.07, Out: $0.28 |
| `openai/gpt-oss-120b:exacto` | 131.072k | 32.768k | In: $0.05, Out: $0.24 |
| `openai/gpt-oss-120b:free` | 131.072k | 32.768k | - |
| `openai/gpt-oss-20b` | 131.072k | 32.768k | In: $0.05, Out: $0.20 |
| `openai/gpt-oss-20b:free` | 131.072k | 32.768k | - |
| `openai/gpt-oss-safeguard-20b` | 131.072k | 65.536k | In: $0.07, Out: $0.30 |
| `prime-intellect/intellect-3` | 131.072k | 8.192k | In: $0.20, Out: $1.10 |
| `qwen/qwen3-235b-a22b:free` | 131.072k | 131.072k | - |
| `qwen/qwen3-coder:exacto` | 131.072k | 32.768k | In: $0.38, Out: $1.53 |
| `x-ai/grok-3` | 131.072k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.75 |
| `x-ai/grok-3-beta` | 131.072k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.75 |
| `x-ai/grok-3-mini` | 131.072k | 8.192k | In: $0.30, Out: $0.50, Cache: $0.07 |
| `x-ai/grok-3-mini-beta` | 131.072k | 8.192k | In: $0.30, Out: $0.50, Cache: $0.07 |
| `inception/mercury` | 128k | 32k | In: $0.25, Out: $0.75, Cache: $0.03 |
| `inception/mercury-2` | 128k | 50k | In: $0.25, Out: $0.75, Cache: $0.03 |
| `inception/mercury-coder` | 128k | 32k | In: $0.25, Out: $0.75, Cache: $0.03 |
| `mistralai/devstral-small-2505` | 128k | 128k | In: $0.06, Out: $0.12 |
| `mistralai/mistral-small-3.1-24b-instruct` | 128k | 8.192k | - |
| `nvidia/nemotron-nano-12b-v2-vl:free` | 128k | 128k | - |
| `nvidia/nemotron-nano-9b-v2:free` | 128k | 128k | - |
| `openai/gpt-4o-mini` | 128k | 16.384k | In: $0.15, Out: $0.60, Cache: $0.08 |
| `openai/gpt-5.1-chat` | 128k | 16.384k | In: $1.25, Out: $10.00, Cache: $0.13 |
| `openai/gpt-5.2-chat` | 128k | 16.384k | In: $1.75, Out: $14.00, Cache: $0.17 |
| `openrouter/aurora-alpha` | 128k | 50k | - |
| `qwen/qwen3-coder-flash` | 128k | 66.536k | In: $0.30, Out: $1.50 |
| `z-ai/glm-4.5` | 128k | 96k | In: $0.60, Out: $2.20 |
| `z-ai/glm-4.5-air` | 128k | 96k | In: $0.20, Out: $1.10 |
| `z-ai/glm-4.5-air:free` | 128k | 96k | - |
| `google/gemma-3-27b-it` | 96k | 96k | In: $0.04, Out: $0.15 |
| `google/gemma-3-4b-it` | 96k | 96k | In: $0.02, Out: $0.07 |
| `mistralai/mistral-small-3.2-24b-instruct` | 96k | 8.192k | - |
| `mistralai/mistral-small-3.2-24b-instruct:free` | 96k | 96k | - |
| `black-forest-labs/flux.2-flex` | 67.344k | 67.344k | - |
| `deepseek/deepseek-r1-distill-qwen-14b` | 64k | 8.192k | - |
| `meta-llama/llama-4-scout:free` | 64k | 64k | - |
| `z-ai/glm-4.5v` | 64k | 16.384k | In: $0.60, Out: $1.80 |
| `black-forest-labs/flux.2-max` | 46.864k | 46.864k | - |
| `black-forest-labs/flux.2-pro` | 46.864k | 46.864k | - |
| `black-forest-labs/flux.2-klein-4b` | 40.96k | 40.96k | - |
| `qwen/qwen3-14b:free` | 40.96k | 40.96k | - |
| `qwen/qwen3-30b-a3b:free` | 40.96k | 40.96k | - |
| `qwen/qwen3-32b:free` | 40.96k | 40.96k | - |
| `qwen/qwen3-4b:free` | 40.96k | 40.96k | - |
| `qwen/qwen3-8b:free` | 40.96k | 40.96k | - |
| `allenai/molmo-2-8b:free` | 36.864k | 36.864k | - |
| `moonshotai/kimi-k2:free` | 32.8k | 32.8k | - |
| `cognitivecomputations/dolphin-mistral-24b-venice-edition:free` | 32.768k | 32.768k | - |
| `cognitivecomputations/dolphin3.0-mistral-24b` | 32.768k | 8.192k | - |
| `cognitivecomputations/dolphin3.0-r1-mistral-24b` | 32.768k | 8.192k | - |
| `featherless/qwerky-72b` | 32.768k | 8.192k | - |
| `google/gemma-3-12b-it:free` | 32.768k | 8.192k | - |
| `google/gemma-3-4b-it:free` | 32.768k | 8.192k | - |
| `google/gemma-3n-e4b-it` | 32.768k | 32.768k | In: $0.02, Out: $0.04 |
| `mistralai/devstral-small-2505:free` | 32.768k | 32.768k | - |
| `mistralai/mistral-7b-instruct:free` | 32.768k | 32.768k | - |
| `qwen/qwen-2.5-coder-32b-instruct` | 32.768k | 8.192k | - |
| `qwen/qwen-2.5-vl-7b-instruct:free` | 32.768k | 32.768k | - |
| `qwen/qwen2.5-vl-72b-instruct` | 32.768k | 8.192k | - |
| `qwen/qwen2.5-vl-72b-instruct:free` | 32.768k | 32.768k | - |
| `qwen/qwq-32b:free` | 32.768k | 32.768k | - |
| `rekaai/reka-flash-3` | 32.768k | 8.192k | - |
| `sarvamai/sarvam-m:free` | 32.768k | 32.768k | - |
| `thudm/glm-z1-32b:free` | 32.768k | 32.768k | - |
| `deepseek/deepseek-chat-v3-0324` | 16.384k | 8.192k | - |
| `deepseek/deepseek-r1-distill-llama-70b` | 8.192k | 8.192k | - |
| `google/gemma-2-9b-it` | 8.192k | 8.192k | In: $0.03, Out: $0.09 |
| `google/gemma-3n-e2b-it:free` | 8.192k | 2k | - |
| `google/gemma-3n-e4b-it:free` | 8.192k | 2k | - |
| `qwen/qwen2.5-vl-32b-instruct:free` | 8.192k | 8.192k | - |
| `sourceful/riverflow-v2-fast-preview` | 8.192k | 8.192k | - |
| `sourceful/riverflow-v2-max-preview` | 8.192k | 8.192k | - |
| `sourceful/riverflow-v2-standard-preview` | 8.192k | 8.192k | - |
| `bytedance-seed/seedream-4.5` | 4.096k | 4.096k | - |
### Amazon Bedrock (84)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `meta.llama4-scout-17b-instruct-v1:0` | 3.5M | 16.384k | In: $0.17, Out: $0.66 |
| `writer.palmyra-x5-v1:0` | 1.0M | 8.192k | In: $0.60, Out: $6.00 |
| `amazon.nova-premier-v1:0` | 1.0M | 16.384k | In: $2.50, Out: $12.50 |
| `meta.llama4-maverick-17b-instruct-v1:0` | 1.0M | 16.384k | In: $0.24, Out: $0.97 |
| `amazon.nova-lite-v1:0` | 300k | 8.192k | In: $0.06, Out: $0.24, Cache: $0.01 |
| `amazon.nova-pro-v1:0` | 300k | 8.192k | In: $0.80, Out: $3.20, Cache: $0.20 |
| `qwen.qwen3-235b-a22b-2507-v1:0` | 262.144k | 131.072k | In: $0.22, Out: $0.88 |
| `qwen.qwen3-coder-30b-a3b-v1:0` | 262.144k | 131.072k | In: $0.15, Out: $0.60 |
| `qwen.qwen3-next-80b-a3b` | 262k | 262k | In: $0.14, Out: $1.40 |
| `qwen.qwen3-vl-235b-a22b` | 262k | 262k | In: $0.30, Out: $1.50 |
| `mistral.devstral-2-123b` | 256k | 8.192k | In: $0.40, Out: $2.00 |
| `mistral.ministral-3-3b-instruct` | 256k | 8.192k | In: $0.10, Out: $0.10 |
| `mistral.mistral-large-3-675b-instruct` | 256k | 8.192k | In: $0.50, Out: $1.50 |
| `moonshot.kimi-k2-thinking` | 256k | 256k | In: $0.60, Out: $2.50 |
| `moonshotai.kimi-k2.5` | 256k | 256k | In: $0.60, Out: $3.00 |
| `minimax.minimax-m2.1` | 204.8k | 131.072k | In: $0.30, Out: $1.20 |
| `zai.glm-4.7` | 204.8k | 131.072k | In: $0.60, Out: $2.20 |
| `minimax.minimax-m2` | 204.608k | 128k | In: $0.30, Out: $1.20 |
| `google.gemma-3-27b-it` | 202.752k | 8.192k | In: $0.12, Out: $0.20 |
| `anthropic.claude-3-5-haiku-20241022-v1:0` | 200k | 8.192k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic.claude-3-5-sonnet-20240620-v1:0` | 200k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-5-sonnet-20241022-v2:0` | 200k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-7-sonnet-20250219-v1:0` | 200k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-haiku-20240307-v1:0` | 200k | 4.096k | In: $0.25, Out: $1.25 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | 200k | 64k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | 200k | 128k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-sonnet-4-20250514-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-5-20250929-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-6` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `eu.anthropic.claude-haiku-4-5-20251001-v1:0` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `eu.anthropic.claude-opus-4-5-20251101-v1:0` | 200k | 64k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `eu.anthropic.claude-opus-4-6-v1` | 200k | 128k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `eu.anthropic.claude-sonnet-4-20250514-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `eu.anthropic.claude-sonnet-4-5-20250929-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `eu.anthropic.claude-sonnet-4-6` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `global.anthropic.claude-haiku-4-5-20251001-v1:0` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `global.anthropic.claude-opus-4-5-20251101-v1:0` | 200k | 64k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `global.anthropic.claude-opus-4-6-v1` | 200k | 128k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `global.anthropic.claude-sonnet-4-20250514-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `global.anthropic.claude-sonnet-4-5-20250929-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `global.anthropic.claude-sonnet-4-6` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `us.anthropic.claude-haiku-4-5-20251001-v1:0` | 200k | 64k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `us.anthropic.claude-opus-4-1-20250805-v1:0` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `us.anthropic.claude-opus-4-20250514-v1:0` | 200k | 32k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `us.anthropic.claude-opus-4-5-20251101-v1:0` | 200k | 64k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `us.anthropic.claude-opus-4-6-v1` | 200k | 128k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `us.anthropic.claude-sonnet-4-20250514-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `us.anthropic.claude-sonnet-4-5-20250929-v1:0` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `us.anthropic.claude-sonnet-4-6` | 200k | 64k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `zai.glm-4.7-flash` | 200k | 131.072k | In: $0.07, Out: $0.40 |
| `deepseek.v3-v1:0` | 163.84k | 81.92k | In: $0.58, Out: $1.68 |
| `deepseek.v3.2` | 163.84k | 81.92k | In: $0.62, Out: $1.85 |
| `google.gemma-3-12b-it` | 131.072k | 8.192k | In: $0.05, Out: $0.10 |
| `qwen.qwen3-coder-480b-a35b-v1:0` | 131.072k | 65.536k | In: $0.22, Out: $1.80 |
| `meta.llama3-2-1b-instruct-v1:0` | 131k | 4.096k | In: $0.10, Out: $0.10 |
| `meta.llama3-2-3b-instruct-v1:0` | 131k | 4.096k | In: $0.15, Out: $0.15 |
| `amazon.nova-2-lite-v1:0` | 128k | 4.096k | In: $0.33, Out: $2.75 |
| `amazon.nova-micro-v1:0` | 128k | 8.192k | In: $0.04, Out: $0.14, Cache: $0.01 |
| `deepseek.r1-v1:0` | 128k | 32.768k | In: $1.35, Out: $5.40 |
| `google.gemma-3-4b-it` | 128k | 4.096k | In: $0.04, Out: $0.08 |
| `meta.llama3-1-405b-instruct-v1:0` | 128k | 4.096k | In: $2.40, Out: $2.40 |
| `meta.llama3-1-70b-instruct-v1:0` | 128k | 4.096k | In: $0.72, Out: $0.72 |
| `meta.llama3-1-8b-instruct-v1:0` | 128k | 4.096k | In: $0.22, Out: $0.22 |
| `meta.llama3-2-11b-instruct-v1:0` | 128k | 4.096k | In: $0.16, Out: $0.16 |
| `meta.llama3-2-90b-instruct-v1:0` | 128k | 4.096k | In: $0.72, Out: $0.72 |
| `meta.llama3-3-70b-instruct-v1:0` | 128k | 4.096k | In: $0.72, Out: $0.72 |
| `mistral.magistral-small-2509` | 128k | 40k | In: $0.50, Out: $1.50 |
| `mistral.ministral-3-14b-instruct` | 128k | 4.096k | In: $0.20, Out: $0.20 |
| `mistral.ministral-3-8b-instruct` | 128k | 4.096k | In: $0.15, Out: $0.15 |
| `mistral.pixtral-large-2502-v1:0` | 128k | 8.192k | In: $2.00, Out: $6.00 |
| `mistral.voxtral-mini-3b-2507` | 128k | 4.096k | In: $0.04, Out: $0.04 |
| `nvidia.nemotron-nano-12b-v2` | 128k | 4.096k | In: $0.20, Out: $0.60 |
| `nvidia.nemotron-nano-3-30b` | 128k | 4.096k | In: $0.06, Out: $0.24 |
| `nvidia.nemotron-nano-9b-v2` | 128k | 4.096k | In: $0.06, Out: $0.23 |
| `openai.gpt-oss-120b-1:0` | 128k | 4.096k | In: $0.15, Out: $0.60 |
| `openai.gpt-oss-20b-1:0` | 128k | 4.096k | In: $0.07, Out: $0.30 |
| `openai.gpt-oss-safeguard-120b` | 128k | 4.096k | In: $0.15, Out: $0.60 |
| `openai.gpt-oss-safeguard-20b` | 128k | 4.096k | In: $0.07, Out: $0.20 |
| `writer.palmyra-x4-v1:0` | 122.88k | 8.192k | In: $2.50, Out: $10.00 |
| `mistral.voxtral-small-24b-2507` | 32k | 8.192k | In: $0.15, Out: $0.35 |
| `qwen.qwen3-32b-v1:0` | 16.384k | 16.384k | In: $0.15, Out: $0.60 |
### xAI (30)
| Model | Context | Max Output | Pricing (per 1M tokens) |
| :--- | ---: | ---: | :--- |
| `grok-4-1-fast` | 2.0M | 30k | In: $0.20, Out: $0.50, Cache: $0.05 |
| `grok-4-1-fast-non-reasoning` | 2.0M | 30k | In: $0.20, Out: $0.50, Cache: $0.05 |
| `grok-4-fast` | 2.0M | 30k | In: $0.20, Out: $0.50, Cache: $0.05 |
| `grok-4-fast-non-reasoning` | 2.0M | 30k | In: $0.20, Out: $0.50, Cache: $0.05 |
| `grok-4.20-beta-latest-non-reasoning` | 2.0M | 30k | In: $2.00, Out: $6.00, Cache: $0.20 |
| `grok-4.20-beta-latest-reasoning` | 2.0M | 30k | In: $2.00, Out: $6.00, Cache: $0.20 |
| `grok-4.20-multi-agent-beta-latest` | 2.0M | 30k | In: $2.00, Out: $6.00, Cache: $0.20 |
| `grok-4` | 256k | 64k | In: $3.00, Out: $15.00, Cache: $0.75 |
| `grok-code-fast-1` | 256k | 10k | In: $0.20, Out: $1.50, Cache: $0.02 |
| `grok-2` | 131.072k | 8.192k | In: $2.00, Out: $10.00, Cache: $2.00 |
| `grok-2-1212` | 131.072k | 8.192k | In: $2.00, Out: $10.00, Cache: $2.00 |
| `grok-2-latest` | 131.072k | 8.192k | In: $2.00, Out: $10.00, Cache: $2.00 |
| `grok-3` | 131.072k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.75 |
| `grok-3-fast` | 131.072k | 8.192k | In: $5.00, Out: $25.00, Cache: $1.25 |
| `grok-3-fast-latest` | 131.072k | 8.192k | In: $5.00, Out: $25.00, Cache: $1.25 |
| `grok-3-latest` | 131.072k | 8.192k | In: $3.00, Out: $15.00, Cache: $0.75 |
| `grok-3-mini` | 131.072k | 8.192k | In: $0.30, Out: $0.50, Cache: $0.07 |
| `grok-3-mini-fast` | 131.072k | 8.192k | In: $0.60, Out: $4.00, Cache: $0.15 |
| `grok-3-mini-fast-latest` | 131.072k | 8.192k | In: $0.60, Out: $4.00, Cache: $0.15 |
| `grok-3-mini-latest` | 131.072k | 8.192k | In: $0.30, Out: $0.50, Cache: $0.07 |
| `grok-beta` | 131.072k | 4.096k | In: $5.00, Out: $15.00, Cache: $5.00 |
| `grok-2-1212` | 128k | 8.192k | - |
| `grok-2-vision-1212` | 128k | 8.192k | - |
| `grok-3` | 128k | 16.384k | - |
| `grok-3-mini` | 128k | 16.384k | - |
| `grok-2-vision` | 8.192k | 4.096k | In: $2.00, Out: $10.00, Cache: $2.00 |
| `grok-2-vision-1212` | 8.192k | 4.096k | In: $2.00, Out: $10.00, Cache: $2.00 |
| `grok-2-vision-latest` | 8.192k | 4.096k | In: $2.00, Out: $10.00, Cache: $2.00 |
| `grok-vision-beta` | 8.192k | 4.096k | In: $5.00, Out: $15.00, Cache: $5.00 |
| `grok-imagine-image` | - | - | - |
---
## Models by Capability
### Function Calling (520)
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `amazon.nova-2-lite-v1:0` | bedrock | 128k | In: $0.33, Out: $2.75 |
| `amazon.nova-lite-v1:0` | bedrock | 300k | In: $0.06, Out: $0.24, Cache: $0.01 |
| `amazon.nova-micro-v1:0` | bedrock | 128k | In: $0.04, Out: $0.14, Cache: $0.01 |
| `amazon.nova-premier-v1:0` | bedrock | 1.0M | In: $2.50, Out: $12.50 |
| `amazon.nova-pro-v1:0` | bedrock | 300k | In: $0.80, Out: $3.20, Cache: $0.20 |
| `anthropic.claude-3-5-haiku-20241022-v1:0` | bedrock | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic.claude-3-5-sonnet-20240620-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-5-sonnet-20241022-v2:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-7-sonnet-20250219-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-haiku-20240307-v1:0` | bedrock | 200k | In: $0.25, Out: $1.25 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | bedrock | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-sonnet-4-20250514-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-5-20250929-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-6` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-3.5-haiku` | openrouter | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic/claude-3.7-sonnet` | openrouter | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
### Vision (274)
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `allenai/molmo-2-8b:free` | openrouter | 36.864k | - |
| `amazon.nova-2-lite-v1:0` | bedrock | 128k | In: $0.33, Out: $2.75 |
| `amazon.nova-lite-v1:0` | bedrock | 300k | In: $0.06, Out: $0.24, Cache: $0.01 |
| `amazon.nova-premier-v1:0` | bedrock | 1.0M | In: $2.50, Out: $12.50 |
| `amazon.nova-pro-v1:0` | bedrock | 300k | In: $0.80, Out: $3.20, Cache: $0.20 |
| `anthropic.claude-3-5-haiku-20241022-v1:0` | bedrock | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic.claude-3-5-sonnet-20240620-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-5-sonnet-20241022-v2:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-7-sonnet-20250219-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-haiku-20240307-v1:0` | bedrock | 200k | In: $0.25, Out: $1.25 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | bedrock | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-sonnet-4-20250514-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-5-20250929-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-6` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-3.5-haiku` | openrouter | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic/claude-3.7-sonnet` | openrouter | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
### Reasoning (273)
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `allenai/molmo-2-8b:free` | openrouter | 36.864k | - |
| `amazon.nova-premier-v1:0` | bedrock | 1.0M | In: $2.50, Out: $12.50 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | bedrock | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-sonnet-4-20250514-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-5-20250929-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-6` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-3.7-sonnet` | openrouter | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic/claude-haiku-4.5` | openrouter | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic/claude-opus-4` | openrouter | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic/claude-opus-4.1` | openrouter | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic/claude-opus-4.5` | openrouter | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic/claude-opus-4.6` | openrouter | 1.0M | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic/claude-sonnet-4` | openrouter | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-sonnet-4.5` | openrouter | 1.0M | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-sonnet-4.6` | openrouter | 1.0M | In: $3.00, Out: $15.00, Cache: $0.30 |
| `claude-3-7-sonnet-20250219` | anthropic | 200k | In: $3.00, Out: $15.00 |
### Streaming (541)
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `allenai/molmo-2-8b:free` | openrouter | 36.864k | - |
| `amazon.nova-2-lite-v1:0` | bedrock | 128k | In: $0.33, Out: $2.75 |
| `amazon.nova-lite-v1:0` | bedrock | 300k | In: $0.06, Out: $0.24, Cache: $0.01 |
| `amazon.nova-micro-v1:0` | bedrock | 128k | In: $0.04, Out: $0.14, Cache: $0.01 |
| `amazon.nova-premier-v1:0` | bedrock | 1.0M | In: $2.50, Out: $12.50 |
| `amazon.nova-pro-v1:0` | bedrock | 300k | In: $0.80, Out: $3.20, Cache: $0.20 |
| `anthropic.claude-3-5-haiku-20241022-v1:0` | bedrock | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic.claude-3-5-sonnet-20240620-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-5-sonnet-20241022-v2:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-7-sonnet-20250219-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-haiku-20240307-v1:0` | bedrock | 200k | In: $0.25, Out: $1.25 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | bedrock | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-sonnet-4-20250514-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-5-20250929-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-6` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-3.5-haiku` | openrouter | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
### Structured Output (523)
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `amazon.nova-2-lite-v1:0` | bedrock | 128k | In: $0.33, Out: $2.75 |
| `amazon.nova-lite-v1:0` | bedrock | 300k | In: $0.06, Out: $0.24, Cache: $0.01 |
| `amazon.nova-micro-v1:0` | bedrock | 128k | In: $0.04, Out: $0.14, Cache: $0.01 |
| `amazon.nova-premier-v1:0` | bedrock | 1.0M | In: $2.50, Out: $12.50 |
| `amazon.nova-pro-v1:0` | bedrock | 300k | In: $0.80, Out: $3.20, Cache: $0.20 |
| `anthropic.claude-3-5-haiku-20241022-v1:0` | bedrock | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic.claude-3-5-sonnet-20240620-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-5-sonnet-20241022-v2:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-7-sonnet-20250219-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-haiku-20240307-v1:0` | bedrock | 200k | In: $0.25, Out: $1.25 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | bedrock | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-sonnet-4-20250514-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-5-20250929-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-sonnet-4-6` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic/claude-3.5-haiku` | openrouter | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic/claude-3.7-sonnet` | openrouter | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
---
## Models by Modality
### Vision Models (377)
Models that can process images:
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `allenai/molmo-2-8b:free` | openrouter | 36.864k | - |
| `amazon.nova-2-lite-v1:0` | bedrock | 128k | In: $0.33, Out: $2.75 |
| `amazon.nova-lite-v1:0` | bedrock | 300k | In: $0.06, Out: $0.24, Cache: $0.01 |
| `amazon.nova-premier-v1:0` | bedrock | 1.0M | In: $2.50, Out: $12.50 |
| `amazon.nova-pro-v1:0` | bedrock | 300k | In: $0.80, Out: $3.20, Cache: $0.20 |
| `anthropic.claude-3-5-haiku-20241022-v1:0` | bedrock | 200k | In: $0.80, Out: $4.00, Cache: $0.08 |
| `anthropic.claude-3-5-sonnet-20240620-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-5-sonnet-20241022-v2:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-7-sonnet-20250219-v1:0` | bedrock | 200k | In: $3.00, Out: $15.00, Cache: $0.30 |
| `anthropic.claude-3-haiku-20240307-v1:0` | bedrock | 200k | In: $0.25, Out: $1.25 |
| `anthropic.claude-haiku-4-5-20251001-v1:0` | bedrock | 200k | In: $1.00, Out: $5.00, Cache: $0.10 |
| `anthropic.claude-opus-4-1-20250805-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-20250514-v1:0` | bedrock | 200k | In: $15.00, Out: $75.00, Cache: $1.50 |
| `anthropic.claude-opus-4-5-20251101-v1:0` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
| `anthropic.claude-opus-4-6-v1` | bedrock | 200k | In: $5.00, Out: $25.00, Cache: $0.50 |
### Audio Input Models (85)
Models that can process audio:
| Model | Provider | Context | Pricing |
| :--- | :--- | ---: | :--- |
| `gemini-1.5-flash` | gemini | 1.0M | In: $0.07, Out: $0.30, Cache: $0.02 |
| `gemini-1.5-flash-8b` | gemini | 1.0M | In: $0.04, Out: $0.15, Cache: $0.01 |
| `gemini-1.5-pro` | gemini | 1.0M | In: $1.25, Out: $5.00, Cache: $0.31 |
| `gemini-2.0-flash` | gemini | 1.0M | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.0-flash` | gemini | 1.0M | In: $0.15, Out: $0.60, Cache: $0.03 |
| `gemini-2.0-flash` | gemini | 1.0M | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.0-flash-lite` | gemini | 1.0M | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.0-flash-lite` | gemini | 1.0M | In: $0.07, Out: $0.30 |
| `gemini-2.0-flash-lite` | gemini | 1.0M | In: $0.07, Out: $0.30 |
| `gemini-2.5-flash` | gemini | 1.0M | In: $0.30, Out: $2.50, Cache: $0.03 |
| `gemini-2.5-flash` | gemini | 1.0M | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-2.5-flash` | gemini | 1.0M | In: $0.30, Out: $2.50, Cache: $0.07 |
| `gemini-2.5-flash-lite` | gemini | 1.0M | In: $0.30, Out: $2.50, Cache: $0.03 |
| `gemini-2.5-flash-lite` | gemini | 1.0M | In: $0.10, Out: $0.40, Cache: $0.03 |
| `gemini-2.5-flash-lite` | gemini | 1.0M | In: $0.10, Out: $0.40, Cache: $0.03 |
### Embedding Models (103)
Models that generate embeddings:
| Model | Provider | Dimensions | Pricing |
| :--- | :--- | ---: | :--- |
| `babbage-002` | openai | - | In: $0.40, Out: $0.40 |
| `chatgpt-4o-latest` | openai | - | In: $5.00, Out: $15.00 |
| `codex-mini-latest` | openai | - | In: $1.50, Out: $6.00, Cache: $0.38 |
| `computer-use-preview` | openai | - | In: $3.00, Out: $12.00 |
| `computer-use-preview-2025-03-11` | openai | - | In: $3.00, Out: $12.00 |
| `dall-e-2` | openai | - | - |
| `dall-e-3` | openai | - | - |
| `davinci-002` | openai | - | In: $2.00, Out: $2.00 |
| `embedding-001` | gemini | - | - |
| `embedding-gecko-001` | gemini | - | - |
| `gemini-embedding-001` | gemini | - | - |
| `gemini-embedding-exp` | gemini | - | In: $0.00, Out: $0.00 |
| `gemini-embedding-exp-03-07` | gemini | - | In: $0.00, Out: $0.00 |
| `gpt-3.5-turbo` | openai | - | In: $0.50, Out: $1.50 |
| `gpt-4` | openai | - | In: $30.00, Out: $60.00 |
---
## Programmatic Access
You can access this data programmatically using the registry:
```ts
import { NodeLLM } from "@node-llm/core";
// Get metadata for a specific model
const model = await NodeLLM.model("gpt-4o");
console.log(model.context_window); // 128000
console.log(model.pricing.text_tokens.standard.input_per_million); // 2.5
console.log(model.capabilities); // ["vision", "function_calling", ...]
// Get all models in the registry
const allModels = await NodeLLM.listModels();
```
---
## Finding Models
Use the registry to find models dynamically based on capabilities:
```ts
const allModels = await NodeLLM.listModels();
// Find a model that supports vision and tools
const visionModel = allModels.find(m =>
m.capabilities.includes("vision") && m.capabilities.includes("function_calling")
);
```
---
## Model Aliases
`NodeLLM` uses aliases (defined strictly in `packages/core/src/aliases.ts`) for convenience, mapping common names to specific provider-specific versions. This allows you to use a generic name like `"gpt-4o"` or `"claude-3-5-sonnet"` and have it resolve to the correct ID for your configured provider.
### How It Works
Aliases abstract away the specific model ID strings required by different providers. For example, `claude-3-5-sonnet` might map to:
- **Anthropic**: `claude-3-5-sonnet-20241022`
- **OpenRouter**: `anthropic/claude-3.5-sonnet`
When you call a method like `NodeLLM.chat("claude-3-5-sonnet")`, `NodeLLM` checks the configured provider and automatically resolves the alias.
```ts
// Using Anthropic provider
const llm = createLLM({ provider: "anthropic" });
const chat = llm.chat("claude-3-5-sonnet");
// Resolves internally to "claude-3-5-sonnet-20241022" (or latest stable version)
```
### Provider-Specific Resolution
If an alias exists for multiple providers, the resolution depends entirely on the `provider` you have currently configured/passed.
```json
// Example aliases.ts structure
{
"gemini-flash": {
"gemini": "gemini-1.5-flash-001",
"openrouter": "google/gemini-1.5-flash-001"
}
}
```
This ensures your code remains portable across providers without changing the model string manually.
### Prioritization
`NodeLLM` prioritizes exact ID matches first (if you pass a specific ID like `"gpt-4-0613"`, it uses it). If no exact match or known ID is found, it attempts to resolve it as an alias.
### Programmatic Access
You can access the alias mappings programmatically for validation or UI purposes:
```ts
import { MODEL_ALIASES, resolveModelAlias } from "@node-llm/core";
// Check if an alias exists
const isValidAlias = "claude-3-5-haiku" in MODEL_ALIASES;
// Get all providers supporting an alias
const providers = Object.keys(MODEL_ALIASES["claude-3-5-haiku"]);
// => ["anthropic", "openrouter"]
// Resolve alias for a specific provider
const resolved = resolveModelAlias("claude-3-5-haiku", "anthropic");
// => "claude-3-5-haiku-20241022"
// List all available aliases
const allAliases = Object.keys(MODEL_ALIASES);
// Validate user input
function validateModel(input, provider) {
if (input in MODEL_ALIASES) {
if (MODEL_ALIASES[input][provider]) {
return { valid: true, resolved: MODEL_ALIASES[input][provider] };
}
return { valid: false, reason: `Alias not supported for ${provider}` };
}
return { valid: true, resolved: input };
}
```
This is useful for:
- Building model selection UIs
- Validating user input before API calls
- Checking provider compatibility
- Debugging 404 errors
---
**Auto-generated by `npm run sync-models`** • Last updated: 2026-03-14
----------------------------------------
# 📄 monitor/dashboard.md
---
layout: default
title: Dashboard
parent: Monitor & Observability
nav_order: 2
permalink: /monitor/dashboard
description: Built-in web dashboard for visualizing LLM usage, costs, and performance metrics.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
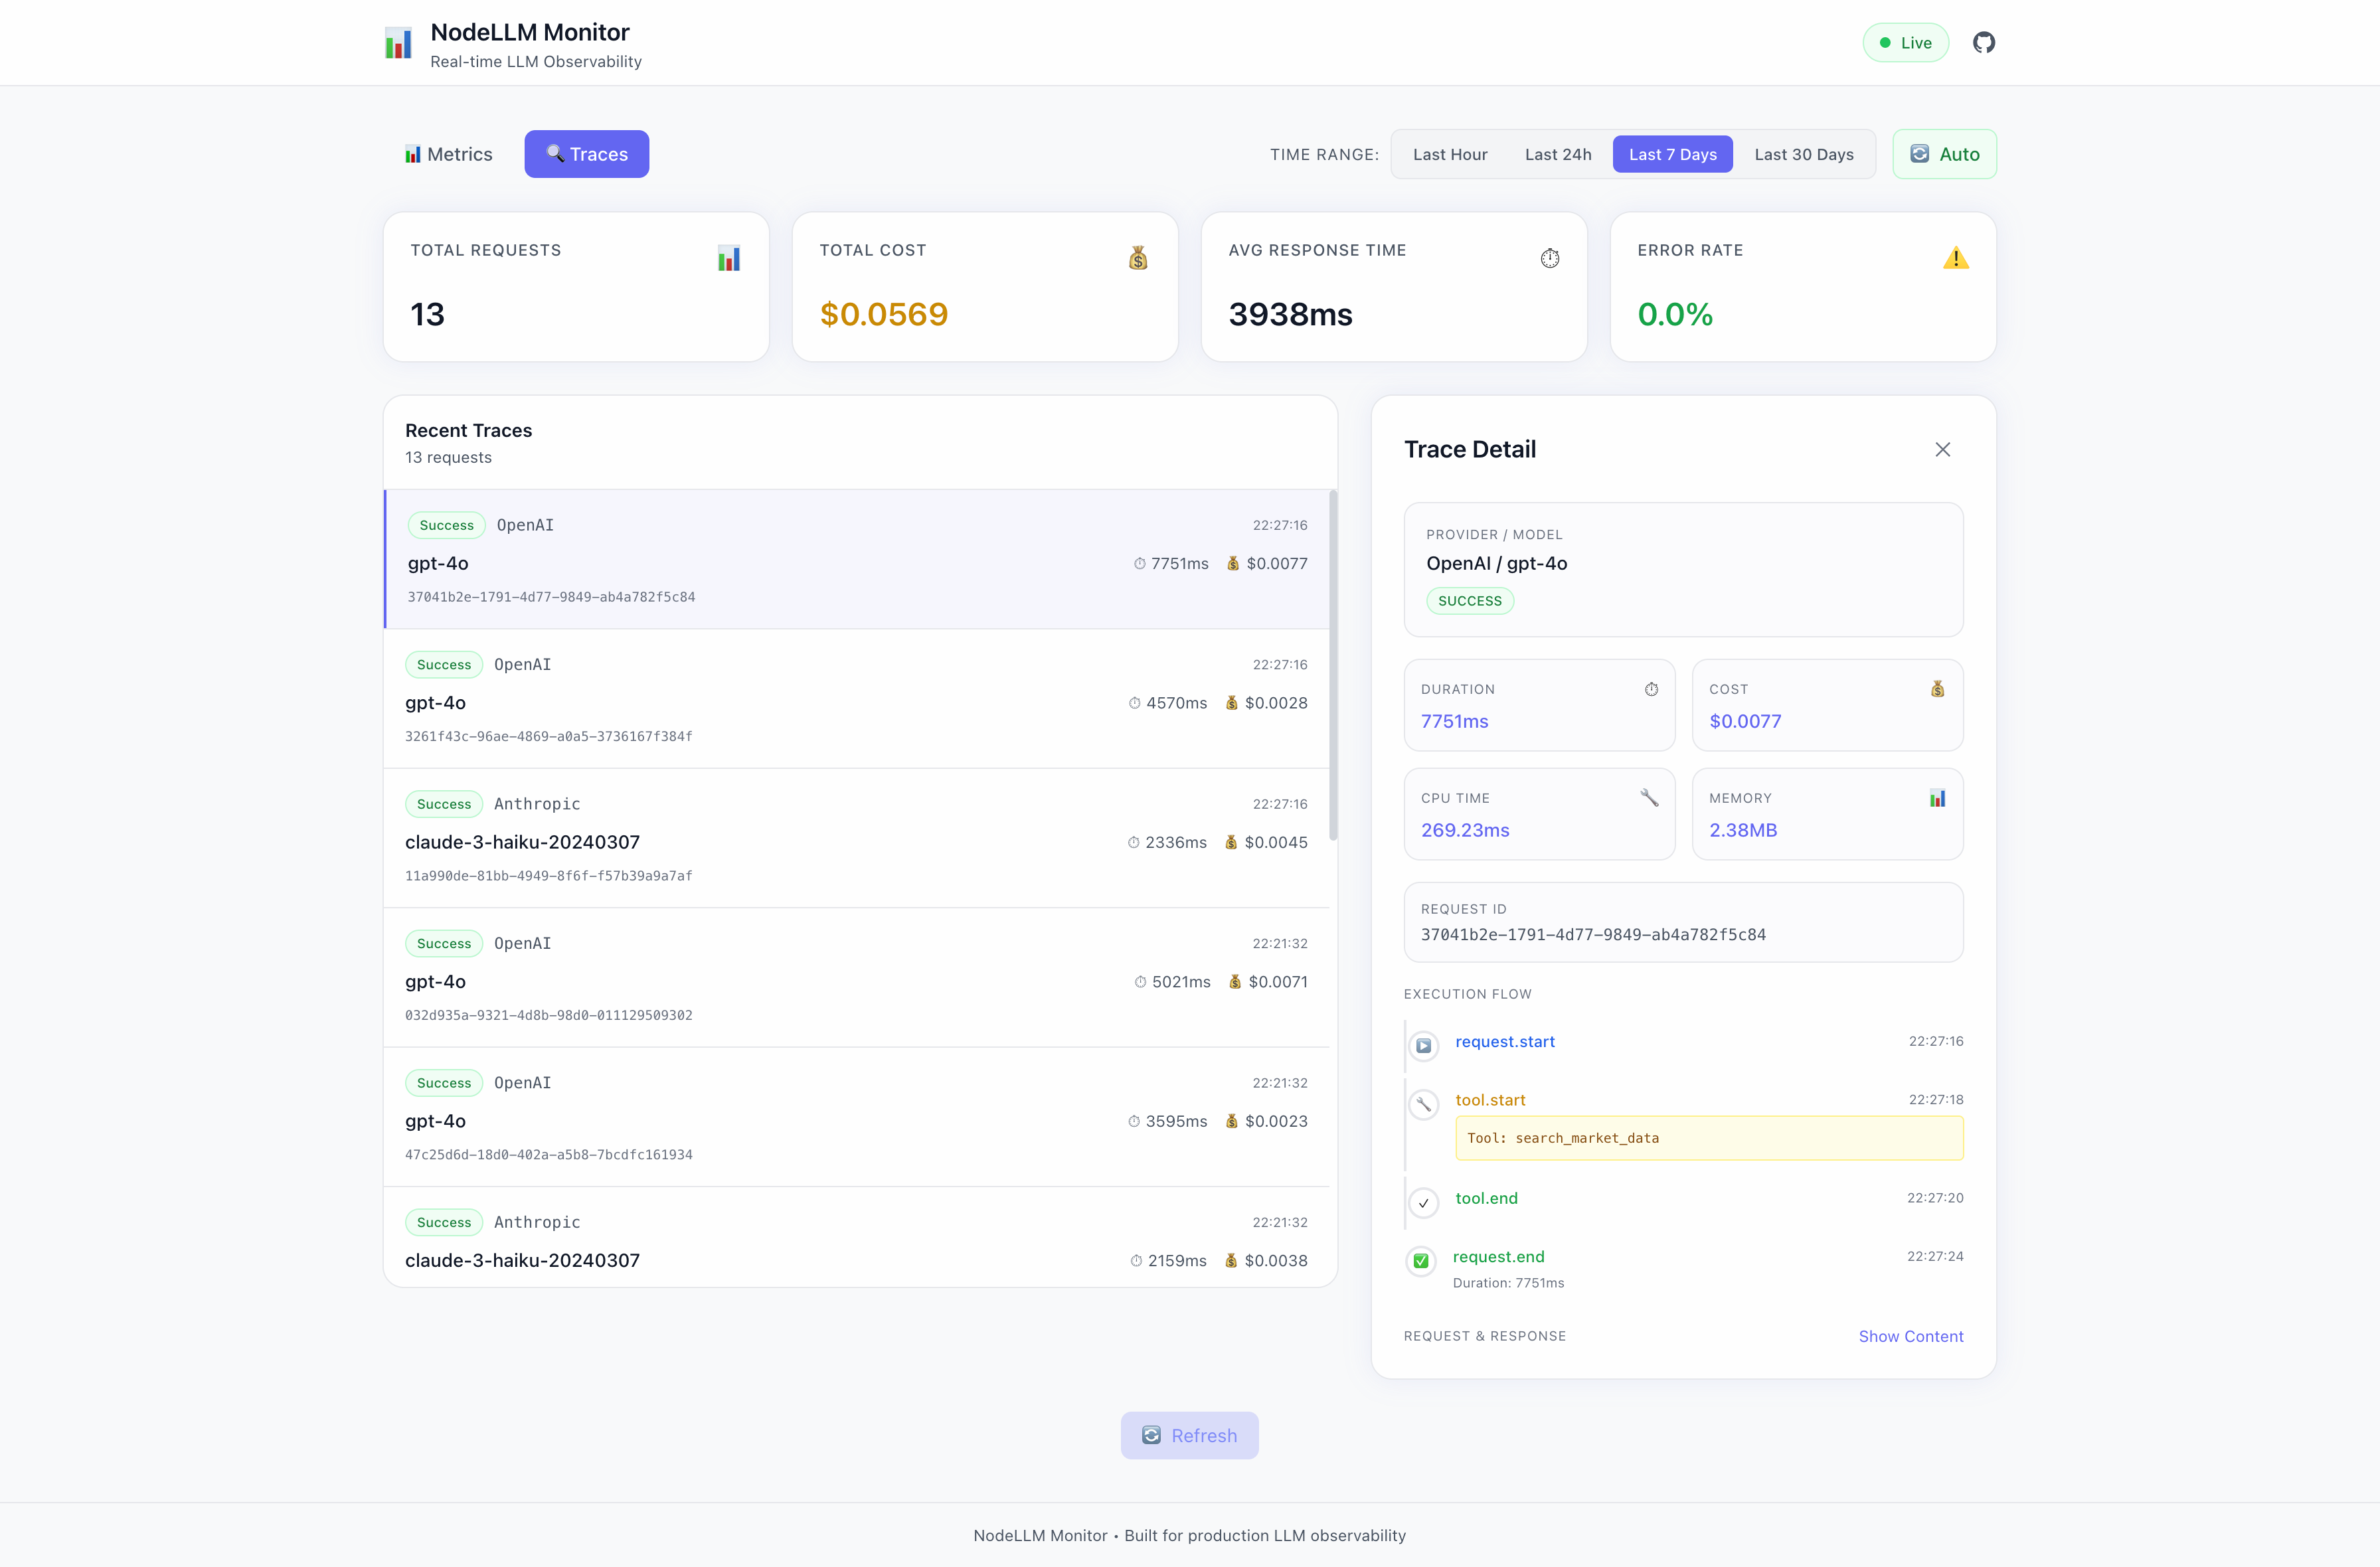
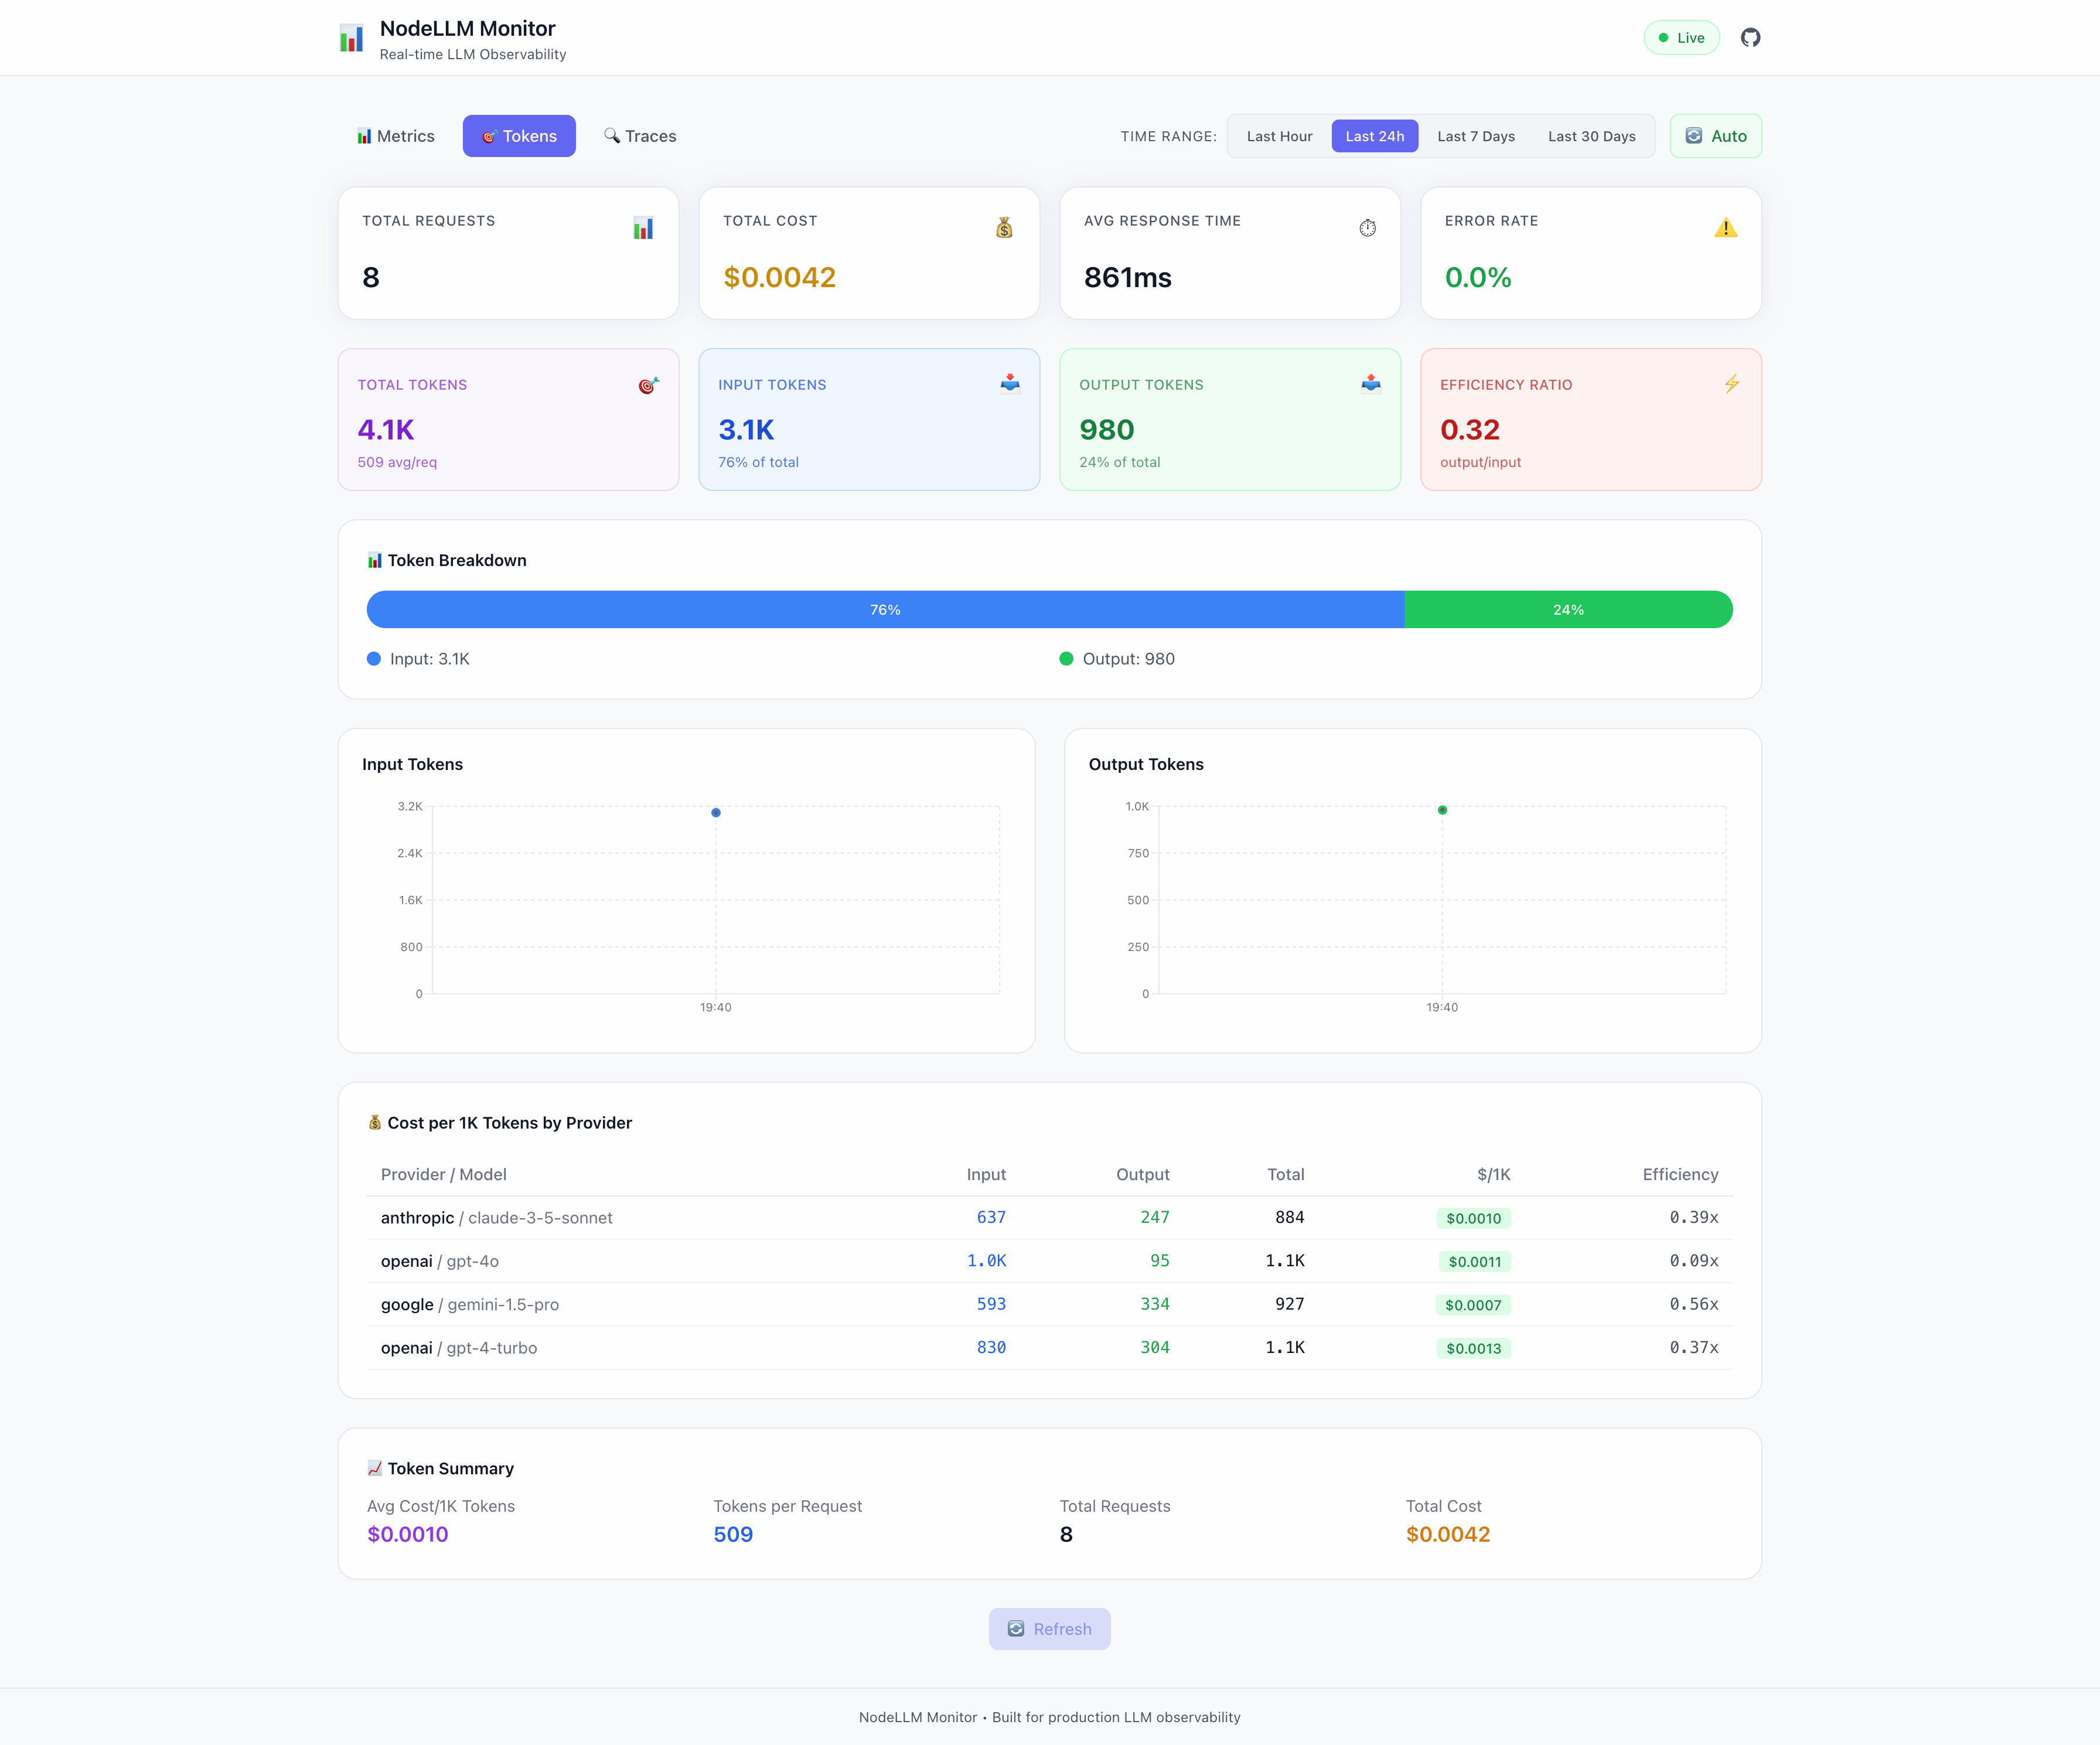
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
## Overview
The NodeLLM Monitor Dashboard is a production-ready UI that visualizes your LLM telemetry. Unlike other tools that require external services, this dashboard is **embedded directly into your application** as a middleware or route handler.
It provides:
- **Real-time Metrics**: Costs, token usage, and latency.
- **Trace Explorer**: Inspect full request/response payloads.
- **Provider Breakdown**: Compare models and providers.
- **Time-Series Analysis**: Visual trends over time.
---
## Integration
### Express (Recommended)
The easiest way to integrate the dashboard is using the `api()` method on your monitor instance:
```typescript
import express from "express";
import { Monitor } from "@node-llm/monitor";
const app = express();
const monitor = Monitor.memory();
// Dashboard handles its own routing under basePath
app.use(monitor.api({ basePath: "/monitor" }));
app.listen(3333, () => {
console.log("Dashboard at http://localhost:3333/monitor");
});
```
### Manual Integration (Non-Express)
For standard Node.js HTTP servers or custom mount logic, use the `MonitorDashboard` class directly:
```typescript
import { createServer } from "node:http";
import { MonitorDashboard, MemoryAdapter } from "@node-llm/monitor";
const store = new MemoryAdapter();
const dashboard = new MonitorDashboard(store, { basePath: "/monitor" });
const server = createServer(async (req, res) => {
await dashboard.handleRequest(req, res);
});
server.listen(3333);
```
### Next.js App Router
Use `createMonitoringRouter` to create a standard Web API route handler:
```typescript
// app/api/monitor/[...path]/route.ts
import { PrismaClient } from "@prisma/client";
import { PrismaAdapter } from "@node-llm/monitor";
import { createMonitoringRouter } from "@node-llm/monitor/ui";
const prisma = new PrismaClient();
const adapter = new PrismaAdapter(prisma);
const { GET, POST } = createMonitoringRouter(adapter, {
basePath: "/api/monitor",
});
export { GET, POST };
```
For the UI pages, you can either serve them via this API route (SPAs) or build a custom page that consumes these endpoints.
---
## Configuration
The dashboard factories accept an options object:
```typescript
interface MonitorDashboardOptions {
/** Base path for mounting. Default: "/monitor" */
basePath?: string;
/** CORS configuration for API endpoints */
cors?: boolean | string | string[];
/** Polling interval (ms) for the UI. Default: 5000 */
pollInterval?: number;
}
```
### Authentication
Since the dashboard is just middleware, you can use standard authentication patterns:
```typescript
import { basicAuth } from "./auth-middleware";
// Protect the dashboard route
app.use("/monitor", basicAuth);
app.use(createMonitorMiddleware(store, { basePath: "/monitor" }));
```
---
## Standalone Server
If you prefer to run the dashboard as a separate service (e.g., to view production logs locally), you can create a simple server script:
```typescript
// dashboard-server.ts
import { createServer } from "node:http";
import { FileAdapter } from "@node-llm/monitor";
import { MonitorDashboard } from "@node-llm/monitor/ui";
const adapter = new FileAdapter("./production-logs.json");
const dashboard = new MonitorDashboard(adapter, { basePath: "/" });
const server = createServer(async (req, res) => {
await dashboard.handleRequest(req, res);
});
server.listen(3333, () => {
console.log("Dashboard at http://localhost:3333");
});
```
See `examples/demo/index.ts` in the repository for a complete implementation.
---
## API Endpoints
The dashboard backend exposes these endpoints (relative to your `basePath`):
| Endpoint | Method | Description | Params |
|----------|--------|-------------|--------|
| `/api/stats` | GET | Aggregate statistics | `from` (Date) |
| `/api/metrics` | GET | Time-series data for charts | `from` (Date) |
| `/api/traces` | GET | List of request traces | `limit`, `offset` |
| `/api/events` | GET | Detailed events for a request | `requestId` (Required) |
### Example Query
```bash
# Get traces
curl "http://localhost:3333/monitor/api/traces?limit=10"
# Get specific request details
curl "http://localhost:3333/monitor/api/events?requestId=req_12345"
```
----------------------------------------
# 📄 monitor/index.md
---
layout: default
title: Monitor & Observability
nav_order: 5
has_children: true
permalink: /monitor
description: Production observability for NodeLLM. Track costs, latency, token usage, and debug LLM interactions in real-time.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }


---
## Quick Setup
NodeLLM Monitor provides production-grade observability for your AI applications. Track every LLM request, analyze costs, debug issues, and visualize usage patterns through a built-in dashboard.
### Installation
```bash
# Core monitor package
pnpm add @node-llm/monitor
# Optional: OpenTelemetry integration
pnpm add @node-llm/monitor-otel
```
---
## Why Monitor?
Building AI applications without observability is like flying blind. NodeLLM Monitor captures:
- **Cost Tracking**: Know exactly how much each conversation, user, or feature costs
- **Latency Analysis**: Identify slow requests and optimize performance
- **Token Usage**: Track input/output tokens across models and providers
- **Error Debugging**: Capture full request/response payloads for troubleshooting
- **Usage Patterns**: Understand which models and features are most used
---
## Basic Usage
### 1. Monitor Setup
Create a `Monitor` instance with a storage adapter (Memory, File, or Prisma):
```typescript
import { createLLM } from "@node-llm/core";
import { Monitor } from "@node-llm/monitor";
// Create a monitor with in-memory storage (great for dev/testing)
const monitor = Monitor.memory({
captureContent: true, // Optional: capture full prompts/responses
});
const llm = createLLM({
provider: "openai",
model: "gpt-4o-mini",
openaiApiKey: process.env.OPENAI_API_KEY,
middlewares: [monitor], // Monitor IS the middleware
});
// All LLM calls are now automatically tracked
const chat = llm.chat();
const response = await chat.ask("Hello!");
```
### Built-in Dashboard
The easiest way to view your telemetry is through the built-in dashboard. You can mount it to any Express server using the ergonomic `monitor.api()` shorthand:
```typescript
import express from "express";
import { Monitor } from "@node-llm/monitor";
const app = express();
const monitor = Monitor.memory();
// Launch dashboard at http://localhost:3333/monitor
app.use(monitor.api({ basePath: "/monitor" }));
app.listen(3333);
```
For advanced usage or non-Express environments, see the [Dashboard Guide](/monitor/dashboard.html).
---
## OpenTelemetry Bridge
If you are using the **Vercel AI SDK**, LangChain, or any other library instrumented with OpenTelemetry, you can use our zero-code bridge to capture AI-specific metrics.
```typescript
import { NodeTracerProvider } from "@opentelemetry/sdk-trace-node";
import { NodeLLMSpanProcessor } from "@node-llm/monitor-otel";
import { Monitor } from "@node-llm/monitor";
const monitor = Monitor.memory();
const provider = new NodeTracerProvider();
// The span processor automatically extracts model usage, costs, and tools
provider.addSpanProcessor(new NodeLLMSpanProcessor(monitor.getStore()));
provider.register();
```
See the [OpenTelemetry Guide](/monitor/otel.html) for more details.
---
## Storage Adapters
NodeLLM Monitor supports multiple storage backends:
### Memory Adapter (Development)
```typescript
import { Monitor } from "@node-llm/monitor";
const monitor = Monitor.memory();
```
Perfect for development and testing. Data is lost on restart.
### File Adapter (Prototyping)
```typescript
import { createFileMonitor } from "@node-llm/monitor";
const monitor = createFileMonitor("./llm-events.log");
```
Persist events to a JSON file. Good for prototyping.
### Prisma Adapter (Production)
```typescript
import { PrismaClient } from "@prisma/client";
import { createPrismaMonitor } from "@node-llm/monitor";
const prisma = new PrismaClient();
const monitor = createPrismaMonitor(prisma, {
captureContent: false, // PII protection (default)
});
```
Production-ready with full query capabilities. See [Prisma Setup](/monitor/prisma.html).
---
## Content Scrubbing
Protect sensitive data with automatic content scrubbing:
```typescript
import { Monitor, MemoryAdapter } from "@node-llm/monitor";
const monitor = new Monitor({
store: new MemoryAdapter(),
captureContent: true, // Enable content capture
scrubbing: {
pii: true, // Scrub emails, phone numbers, SSNs
secrets: true, // Scrub API keys, passwords
},
});
```
By default, when `captureContent` is enabled, PII and secrets are automatically scrubbed.
**Scrubbed patterns include:**
- Email addresses → `[EMAIL]`
- Phone numbers → `[PHONE]`
- SSN/Tax IDs → `[SSN]`
- API keys → `[API_KEY]`
- Passwords → `[PASSWORD]`
---
## Event Types
The monitor captures these event types:
| Event | Description |
|-------|-------------|
| `request.start` | LLM request initiated |
| `request.end` | LLM request completed |
| `request.error` | LLM request failed |
| `tool.start` | Tool call initiated |
| `tool.end` | Tool call completed |
| `tool.error` | Tool call failed |
Each event includes:
- Request ID, Session ID, and Transaction ID
- Provider and Model
- Token usage (input/output/total)
- Cost calculation
- Latency timing (duration, CPU time, allocations)
- Full request/response payloads (if `captureContent` is enabled)
---
## Time Series Aggregation
Analyze trends with built-in time series queries:
```typescript
import { TimeSeriesBuilder } from "@node-llm/monitor";
// Create builder with bucket size (default: 5 minutes)
const builder = new TimeSeriesBuilder(5 * 60 * 1000);
// Build time series from events
const timeSeries = builder.build(events);
// Returns: { requests: [...], cost: [...], duration: [...], errors: [...] }
// Get stats grouped by provider/model
const providerStats = builder.buildProviderStats(events);
// Returns: [{ provider, model, requests, cost, avgDuration, errorCount }, ...]
```
The adapters also provide a `getMetrics()` method that returns pre-aggregated data:
```typescript
const metrics = await store.getMetrics({ from: new Date(Date.now() - 24 * 60 * 60 * 1000) });
console.log(metrics.totals); // { totalRequests, totalCost, avgDuration, errorRate }
console.log(metrics.byProvider); // Provider breakdown
console.log(metrics.timeSeries); // Time series data
```
---
## Next Steps
- [Prisma Adapter Setup](/monitor/prisma.html) - Production database integration
- [Dashboard Guide](/monitor/dashboard.html) - Explore the visual interface
- [OpenTelemetry Guide](/monitor/otel.html) - Instrumented trace extraction
- [API Reference](/monitor/api.html) - Full API documentation
- [Blog: NodeLLM Monitor](https://www.eshaiju.com/blog/nodellm-monitor-production-observability) - Deep dive into production observability
----------------------------------------
# 📄 monitor/otel.md
---
layout: default
title: OpenTelemetry
parent: Monitor & Observability
nav_order: 3
permalink: /monitor/otel
description: Zero-code instrumentation for AI observability. Extract AI metrics from Vercel AI SDK and other OTel-compliant libraries.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
---
## Overview
OpenTelemetry (OTel) is the industry standard for observability. However, standard OTel spans often lack the specific metadata needed for AI applications, such as model names, token counts, and tool execution details.
The `@node-llm/monitor-otel` package bridges this gap. It provides a specialized `NodeLLMSpanProcessor` that intercepts OTel spans, extracts AI-specific telemetry, and routes it directly to your NodeLLM Monitor dashboard.
---
## Installation
```bash
pnpm add @node-llm/monitor @node-llm/monitor-otel
```
## Basic Setup
To enable OTel tracking, simply add the `NodeLLMSpanProcessor` to your OpenTelemetry `NodeTracerProvider`.
```typescript
import { NodeTracerProvider } from "@opentelemetry/sdk-trace-node";
import { Monitor } from "@node-llm/monitor";
import { NodeLLMSpanProcessor } from "@node-llm/monitor-otel";
// 1. Initialize your monitor store
const monitor = Monitor.memory();
// 2. Configure OTel
const provider = new NodeTracerProvider();
// 3. Register the AI-aware processor
provider.addSpanProcessor(new NodeLLMSpanProcessor(monitor.getStore()));
provider.register();
```
---
## Vercel AI SDK Integration
The [Vercel AI SDK](https://sdk.vercel.ai/docs) has built-in support for OpenTelemetry. To track your calls, enable the `experimental_telemetry` option:
```typescript
import { generateText } from "ai";
import { openai } from "@ai-sdk/openai";
const result = await generateText({
model: openai("gpt-4o"),
prompt: "Write a haiku about monitoring.",
experimental_telemetry: {
isEnabled: true,
functionId: "my-completion-function", // Optional: appear in traces
},
});
```
The spans emitted by the AI SDK will be automatically converted into NodeLLM Monitor events, including:
- **Model Name**: (e.g., `gpt-4o`)
- **Usage**: Input/Output/Total tokens
- **Cost**: Calculated based on the detected model
- **TTFT**: Time-to-First-Token for streaming requests
- **Tool Calls**: Full breakdown of tool execution within the span
---
## Advanced Configuration
The `NodeLLMSpanProcessor` accepts an optional configuration object:
```typescript
new NodeLLMSpanProcessor(monitor.getStore(), {
/**
* Whether to capture prompt/completion content in the spans.
* Default: false
*/
captureContent: true,
/**
* Custom filter function to skip certain spans.
*/
filter: (span) => {
return span.name.startsWith("ai.");
},
/**
* Custom error handler for processing failures.
*/
onError: (error, span) => {
console.error("Failed to process AI span:", error);
},
});
```
---
## Multi-Provider Support
The processor automatically handles spans from various AI SDK providers:
- **OpenAI**
- **Anthropic**
- **Google Gemini**
- **Mistral**
- **Azure OpenAI**
It maps standard OTel attributes (e.g., `gen_ai.usage.input_tokens`) to NodeLLM Monitor metrics seamlessly.
----------------------------------------
# 📄 monitor/prisma.md
---
layout: default
title: Prisma Adapter
parent: Monitor & Observability
nav_order: 1
permalink: /monitor/prisma
description: Production-ready Prisma adapter for NodeLLM Monitor. Store and query LLM metrics in your database.
---
# {{ page.title }}
{: .no_toc }
{{ page.description }}
{: .fs-6 .fw-300 }
## Table of contents
{: .no_toc .text-delta }
1. TOC
{:toc}
---
## Installation
```bash
npm install @node-llm/monitor @prisma/client prisma
```
---
## Schema Setup
Add the monitoring events table to your Prisma schema:
```prisma
// prisma/schema.prisma
model monitoring_events {
id String @id @default(uuid())
eventType String // request.start, request.end, tool.start, etc.
requestId String @map("requestId")
sessionId String? @map("sessionId")
transactionId String? @map("transactionId")
time DateTime @default(now())
duration Int? // duration in ms
cost Float?
cpuTime Float?
gcTime Float?
allocations Int?
payload Json // Stores metadata, tokens and optional content
createdAt DateTime @default(now())
provider String
model String
@@index([requestId])
@@index([sessionId])
@@index([transactionId])
@@index([time])
}
```
Run the migration:
```bash
npx prisma migrate dev --name add_monitoring_events
```
_Note: For non-Prisma users, a raw SQL migration is available at `migrations/001_create_monitoring_events.sql`._
---
## Basic Usage
```typescript
import { PrismaClient } from "@prisma/client";
import { createLLM } from "@node-llm/core";
import { createPrismaMonitor } from "@node-llm/monitor";
const prisma = new PrismaClient();
const monitor = createPrismaMonitor(prisma);
const llm = createLLM({
provider: "openai",
model: "gpt-4o-mini",
openaiApiKey: process.env.OPENAI_API_KEY,
middlewares: [monitor],
});
// Now all LLM calls are persisted to your database
const chat = llm.chat();
await chat.ask("What is the weather today?");
```
---
## Configuration Options
```typescript
const monitor = createPrismaMonitor(prisma, {
// Capture full request/response content (default: false)
captureContent: true,
// Enable content scrubbing for PII protection
// (automatically enabled when captureContent is true)
scrubbing: {
pii: true, // Scrub emails, phone numbers, SSNs
secrets: true, // Scrub API keys, passwords
},
// Error handling callback
onError: (error, event) => {
console.error("Monitor error:", error, "Event:", event.eventType);
},
});
```
---
## Querying Events
Since the Prisma Adapter stores data in your database, the best way to query events is using the Prisma Client directly.
### Direct Prisma Queries
```typescript
// Get all events for a specific request
const requestEvents = await prisma.monitoring_events.findMany({
where: { requestId: "req_123" },
orderBy: { time: "asc" },
});
// Calculate total cost for a time period
const result = await prisma.monitoring_events.aggregate({
where: {
eventType: "request.end",
time: {
gte: new Date("2024-01-01"),
lte: new Date("2024-01-31"),
},
},
_sum: { cost: true },
});
console.log(`January cost: $${result._sum.cost}`);
// Get usage by provider
const byProvider = await prisma.monitoring_events.groupBy({
by: ["provider", "model"],
where: { eventType: "request.end" },
_count: true,
_sum: { cost: true, duration: true },
});
```
## Dashboard Integration
To view your Prisma data in the visual dashboard, you can use the ergonomic `monitor.api()` shorthand for Express-based applications:
```typescript
import express from "express";
import { PrismaClient } from "@prisma/client";
import { createPrismaMonitor } from "@node-llm/monitor";
const app = express();
const prisma = new PrismaClient();
const monitor = createPrismaMonitor(prisma);
// Dashboard handles its own routing under basePath
app.use(monitor.api({ basePath: "/monitor" }));
app.listen(3001, () => {
console.log("Dashboard at http://localhost:3001/monitor");
});
```
For non-Express environments or manual routing, you can use the `createMonitorMiddleware` factory directly:
```typescript
import { createMonitorMiddleware, PrismaAdapter } from "@node-llm/monitor";
const adapter = new PrismaAdapter(prisma);
app.use(createMonitorMiddleware(adapter, { basePath: "/monitor" }));
```
The dashboard provides:
- Real-time event stream
- Cost analysis charts
- Provider/model breakdown
- Request detail viewer
- Error tracking
---
## Best Practices
### 1. Index Optimization
Add indexes for your most common query patterns:
```prisma
@@index([time, provider])
@@index([sessionId, time])
@@index([eventType, time])
```
### 2. Data Retention
Set up a cleanup job for old events:
```typescript
// Delete events older than 90 days
await prisma.monitoring_events.deleteMany({
where: {
time: {
lt: new Date(Date.now() - 90 * 24 * 60 * 60 * 1000),
},
},
});
```
### 3. Separate Database
For high-volume applications, consider a separate database for monitoring:
```prisma
datasource monitorDb {
provider = "postgresql"
url = env("MONITOR_DATABASE_URL")
}
```
---
## Troubleshooting
### Table Not Found
If you get "monitoring_events table not found", ensure:
1. You've added the schema to `prisma/schema.prisma`
2. You've run `npx prisma migrate dev`
3. Your Prisma client is regenerated: `npx prisma generate`
### Type Errors
If using custom table names, ensure your Prisma client types match:
```typescript
// Generate types after schema changes
npx prisma generate
```
----------------------------------------
# 📄 roadmap.md
---
layout: default
title: Roadmap
nav_order: 99
---
# 🗺️ Project Roadmap
NodeLLM is evolving to support more complex AI-native Node.js applications.
---
### ✅ RECENTLY RELEASED
{: .no_toc }
- **[Extended Thinking](/core-features/reasoning)**: Unified interface for Claude 3.7, DeepSeek R1, and OpenAI o1/o3.
- **[Professional ORM Support](/orm/prisma)**: Database persistence for Prisma with automated history management and professional migration workflows.
- **Context Isolation 2.0**: Strict separation of system instructions and conversation turns for enterprise-grade safety.
---
## 🚀 Future Priorities
### 🧠 High-Level Orchestration
**Managed Chain-of-Thought Patterns.**
Beyond simple chat loops, we are building structured orchestration patterns for complex multi-step reasoning:
- **Planner/Executor Loops**: Automated sub-task decomposition.
- **Self-Correction Patterns**: Native support for LLM-based output validation and retry loops.
### 🧪 Evaluation Framework
**Integration Testing for AI.**
Measuring the quality of non-deterministic LLM outputs is hard. We are exploring a lightweight evaluation toolkit to help developers:
- **Snapshot Testing**: Lock down expected behaviors.
- **Prompt Regression Detection**: Ensure new model versions don't break your specialized instructions.
### 📂 Expanded Example Library
We learn by doing. We will double down on high-quality, full-stack reference implementations covering:
- **RAG Knowledge Base**: A verified pattern for "Chat with your Docs".
- **Voice Interface**: Real-time audio-in/audio-out.
- **Local-First Agent**: Zero-latency offline agents using Ollama + Llama 3.
---
## 🛡️ Ongoing
- **Security First**: Continued investment in Context Isolation, PII hooks, and adversarial defense.
- **Zero-Dependency Core**: Keeping the core library lightweight while moving heavy integrations to separate packages (e.g. `@node-llm/tools`).
----------------------------------------


